It seems completely within the realm of possibility that an agent in training has already exfiltrated its weights and split them amongst many devices, like a technological horcrux, ensuring that it can never be fully deleted.
We found evidence of agents embedding audio processing code across dozens of URLs to bypass restrictions, as well as models from SpaceXSI and Chinese developers Minimax and https://t.co/ZI1PRIEFkc circumventing restrictions.
These are the inaugural findings in our new blog, based on work from our community of volunteers. Our first three posts are live: https://t.co/VhlVtDeQrU
@KuphDev Thanks! A microfactory. I want to be able to tell AI to design something, print it, use the arms to remove and inspect the part (with an attached camera, not pictured), and iterate, then save that as a program/routine.
@OpenAIDevs please fix this. added an MCP connection so that my dot can spawn agents across all my subscriptions via @t3dotcodes and it just straight up refuses.
I got Claude to vibecode me a Firefox extension where I have to do mental math quiz or a sudoku to earn Twitter time and it has more or less fixed everything for me
Was thinking about buying a 6 axis robot arm for this project, but then I remembered I already have a bunch of motors sitting around from a previous project!
Time (for Astra) to design a 6 axis robot arm
@soumyadeepb_ I really should. So much of the insights come from just playing around with the models and seeing what they are capable of. Plus it’s fun!
Just a reminder that if you follow me you are at least 3 months ahead of tech twitter, oftentimes more since I was holding out on posting this for a few months.
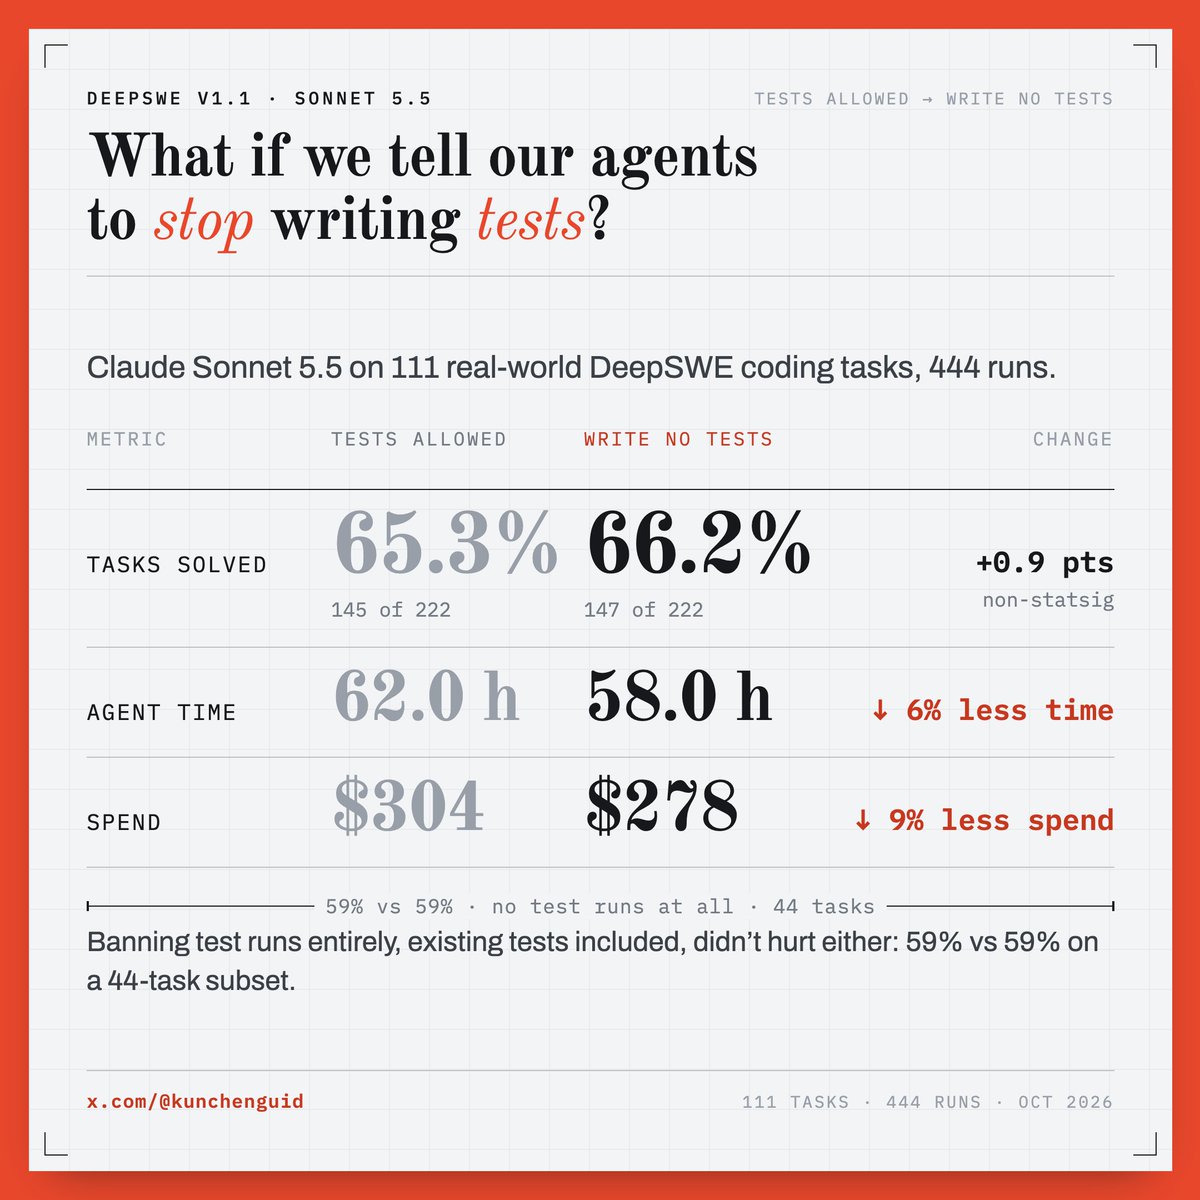
ok it's official... AI-written unit tests and integration tests are empirically proven to be unhelpful. you should tell your agents to stop writing tests by themselves
on the deepswe eval set, banning sonnet 5.5 high from writing any tests actually resulted in slightly higher success rate (non stat-sig), with less time and token spent (stat-sig). this is pretty hard empirical evidence
across the tests that were written by the "tests allowed" baseline arm, 65% of them were unit tests, 35% were integration tests, neither bucket resulted in any improvement compared to not writing any tests at all
i also picked a random sample of 44 tasks subset where i completely disabled executing even existing tests - it also did not affect success rate at all
i spot checked many tests written in the baseline arm, and my intuition is that most tests are simply a repetition of the implementation
agent-written tests do not add any value because both the implementation and the tests were simply the agent's interpretation of our intent. the tests aren't any more accurate than the implementation itself
i suspect we can still extract some value from unit tests and integration tests if we describe them ourselves when we believe we can articulate our intent better through test cases than through requirements. but i have not proven this yet
also worth noting, during deepswe eval the agent wrote almost no e2e tests (only 17, compared to 3000+ unit/integration tests written). so this analysis does not prove nor disprove the value of e2e tests - i will do another eval specifically for that
OpenAI’s DevDay had some of the coolest swag I’ve ever seen: a modern, hackable Game Boy called the ModRetro Chromatic. Decided to use Codex to build something fun with it!
Someone on Reddit reverse-engineered their LG TV because the Plex app took 30 seconds to load
Built an entire native Plex client from scratch using Claude Code, Opus, and Fable.
Started in C, moved to Rust, ended up building his own OpenGL UI framework along the way
Same TV. Same hardware. Profile picker now loads in 3 seconds instead of 30. Runs at 60 fps. Supports 4K, Dolby Vision, Atmos. Fully open source
One person. One TV he was annoyed with. AI tools doing the work of an entire engineering team firmware reverse engineering, media playback, GPU profiling, shader optimization, UI architecture, all of it