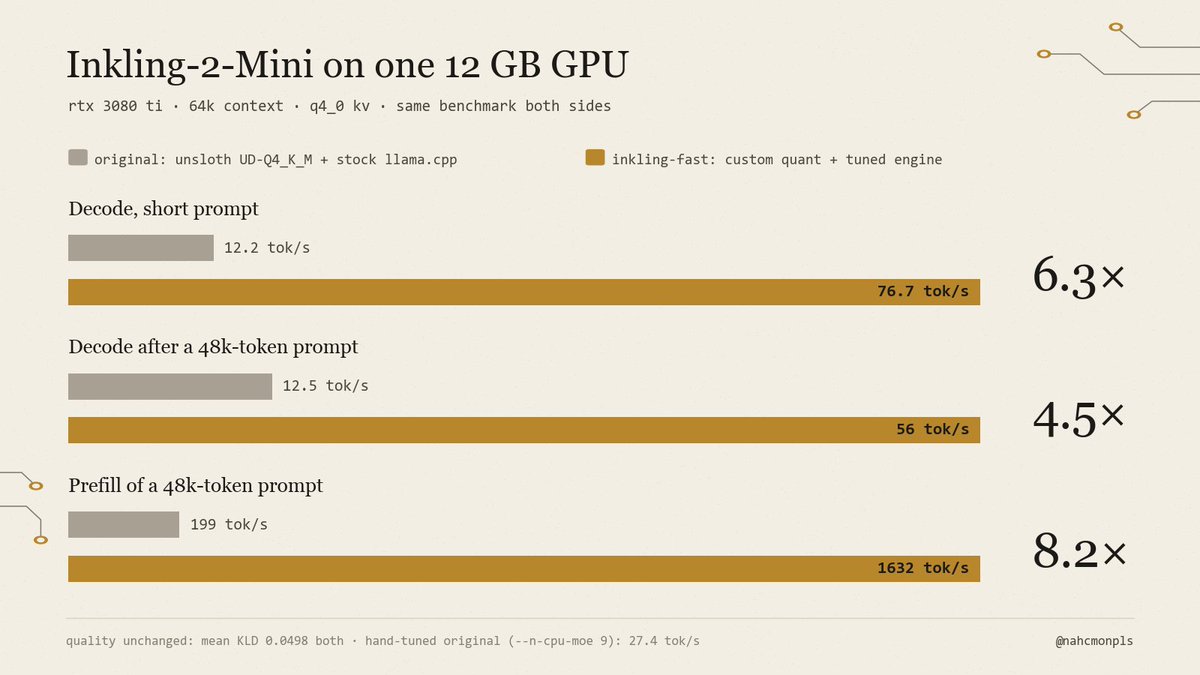
Got Inkling 2 Mini running fully on a 12gb 3080 Ti @ 64k context:
12,2 -> 76,7 tok/s decode (6,3x)
199 -> 1632 tok/s prefill on a 48k prompt (8,2x)
196 tok/s across 8 streams
Same quality as the original @UnslothAI Q4_K_M.
Custom quant + tuned llama.cpp:
https://t.co/aIIIpoGEdg
Every "runs on a 32GB laptop" claim needs the context length next to it.
A 26B model at 4k context is a different thing from the same model at 128k once the KV cache fills up.
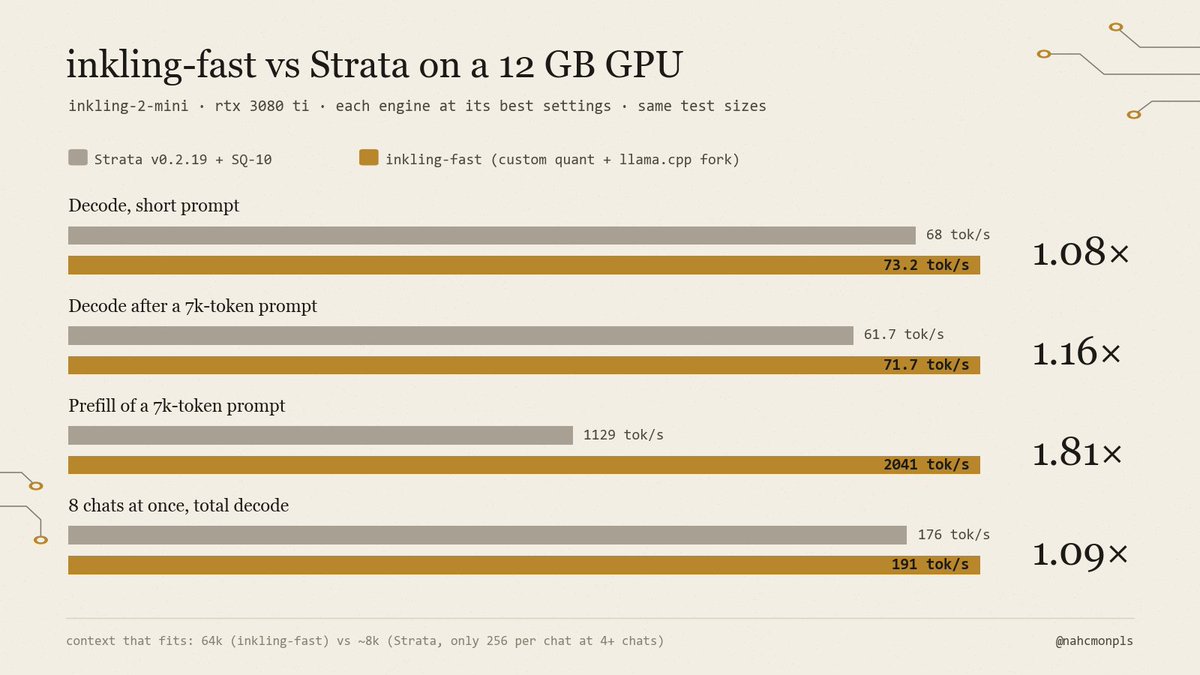
Tried it against my inkling-fast build on the same 12gb 3080 Ti.
Speed's are similar but the bigger gap is context: 64k vs about 8k with Strata (and 256 per chat with 4+ chats).
To be fair, Strata's fast kernels don't run on a 3080 Ti.
https://t.co/aIIIpoHc2O
This update is HUGE 👀
- Inkling 2 Mini is now supported in Strata 🥳
- 11,306 tokens/s on prefill and 4,087 tokens/s on output with RTX 5090 😨
- Qwen3.8-Flash-Next receives a 40% performance increase across all hardware we support 🥶
See more at: https://t.co/pRksU6D8T7
@antonships Mostly the cache. Mine stores the KV cache at 4-bit (q4_0 with Hadamard rotation, quality held up in KLD tests); Strata uses fp16/fp8, so 2–4× more memory per token. Its weights + buffers also leave only ~0.7 GB free on 12 GB, so there's little room for cache to begin with.
@coldniko Strata:
SQ-10 (9.75 GB), v0.2.19, --kv fp8, DSpark off (it was slower on my card, 57 vs 68 tok/s).
Mine:
A custom 10.1 GB GGUF mix: IQ2_XS expert gate/up (imatrix), NVFP4 expert down, Q6_K attention. KLD 0.0498 vs Q8.
Happy to share full logs if useful!