Open Source Avengers, Assemble!
Ask an expert AI agent team to solve complex problems together 🔥
Consilium brings together multiple agents that debate and use live research (web, arXiv, SEC) to reach a consensus. You set the strategy, they find the answer.
⬇️ Demo on Hugging Face
I'm excited to share the launch of MedGemma 💎
🤗4B multimodal and 27B thinking text models
👀 Image classification and interpretation
🧠Medical text comprehension and clinical reasoning
Models and demo: https://t.co/jm9e7pRnux
Docs: https://t.co/k9ALjzYGDX
The Phi-4-reasoning tech report is a real tour de force in both rigour and pragmatism.
The main lessons for me are:
> Most gains come from careful SFT, with RL the 🍒 on top
> Filter the data for the most "teachable" prompts, ie not too easy for the model you want to tune.
> Use majority voting of teacher models to derive difficulty heuristic when verifiable answers aren't available
> The optimal SFT data mixture can be derived "additively" by fine-tuning domain-specific models on math/code and then using those signals to figure out which subsets to combine in the final model
> Including a reasoning-specific system prompt in SFT helps make the model more robust
> Length-aware penalties help with stability (similar to https://t.co/DLv1e6HgOk and DAPO)
> Popular evals like AIME24/25 are noisy as hell and should be repeated 50 times at least to mitigate variance. Kudos to MSFT for actually publishing std errors in their evals!
> RLVR induces a sharper distribution of pass@1 scores than SFT
I attended a vibe coding hackathon recently and used the chance to build a web app (with auth, payments, deploy, etc.). I tinker but I am not a web dev by background, so besides the app, I was very interested in what it's like to vibe code a full web app today. As such, I wrote none of the code directly (Cursor+Claude/o3 did) and I don't really know how the app works, in the conventional sense that I'm used to as an engineer.
The app is called MenuGen, and it is live on https://t.co/bQonQT88t0. Basically I'm often confused about what all the things on a restaurant menu are - e.g. Pâté, Tagine, Cavatappi or Sweetbread (hint it's... not sweet). Enter MenuGen: you take a picture of a menu and it generates images for all the menu items and presents them in a nice list. I find it super useful to get a quick visual sense of the menu.
But the more interesting part for me I thought was the exploration of vibe coding around how easy/hard it is to build and deploy a full web app today if you are not a web developer. So I wrote up the full blog post on my experience here, including some takeaways:
https://t.co/2kkQh0ElgB
Copy pasting just the TLDR:
"Vibe coding menugen was exhilarating and fun escapade as a local demo, but a bit of a painful slog as a deployed, real app. Building a modern app is a bit like assembling IKEA future. There are all these services, docs, API keys, configurations, dev/prod deployments, team and security features, rate limits, pricing tiers... Meanwhile the LLMs have slightly outdated knowledge of everything, they make subtle but critical design mistakes when you watch them closely, and sometimes they hallucinate or gaslight you about solutions. But the most interesting part to me was that I didn't even spend all that much work in the code editor itself. I spent most of it in the browser, moving between tabs and settings and configuring and gluing a monster. All of this work and state is not even accessible or manipulatable by an LLM - how are we supposed to be automating society by 2027 like this?"
See the post for full detail, and maybe give MenuGen a go the next time you're at a restaurant!
Traditional RAG vs. HyDE, visually explained!
One critical problem with the traditional RAG system is that questions are not semantically similar to their answers.
Consider the example where you want to find a sentence similar to "What is ML?" It is likely that "What is AI?" will appear more similar than "Machine learning is fun."
This semantic dissimilarity leads to several irrelevant contexts being retrieved during the retrieval step.
HyDE solves this issue.
The visual below illustrates how this approach differs from traditional RAG.
Here's how it works:
- Use an LLM to generate a hypothetical answer (H) for the query (Q). This answer doesn't have to be entirely correct.
- Embed the answer using a contriever model to obtain E. Bi-encoders trained with contrastive learning are generally used for this purpose.
- Use the embedding E to query the vector database and retrieve relevant context (C).
- Pass the hypothetical answer H, the retrieved context C, and the query Q to the LLM to produce a final answer.
Done!
Now, of course, the hypothetical generated will likely contain hallucinated details.
But this does not severely affect the performance due to the contriever model—one which embeds.
More specifically, this model is trained using contrastive learning and it also functions as a near-lossless compressor whose task is to filter out the hallucinated details of the fake document.
This produces a vector embedding that is expected to be more similar to the embeddings of actual documents than the question is to the real documents.
Several studies have shown that HyDE improves the retrieval performance compared to the traditional embedding model.
But this comes at the cost of increased latency and more LLM usage.
Enjoyed this? You should also my RAG series! From building and optimizing RAG apps to evaluating performance and crafting agentic & multi-modal systems—it's all here.
Link in the next tweet!
_____
Find me → @akshay_pachaar ✔️
For more insights and tutorials on AI and Machine Learning!
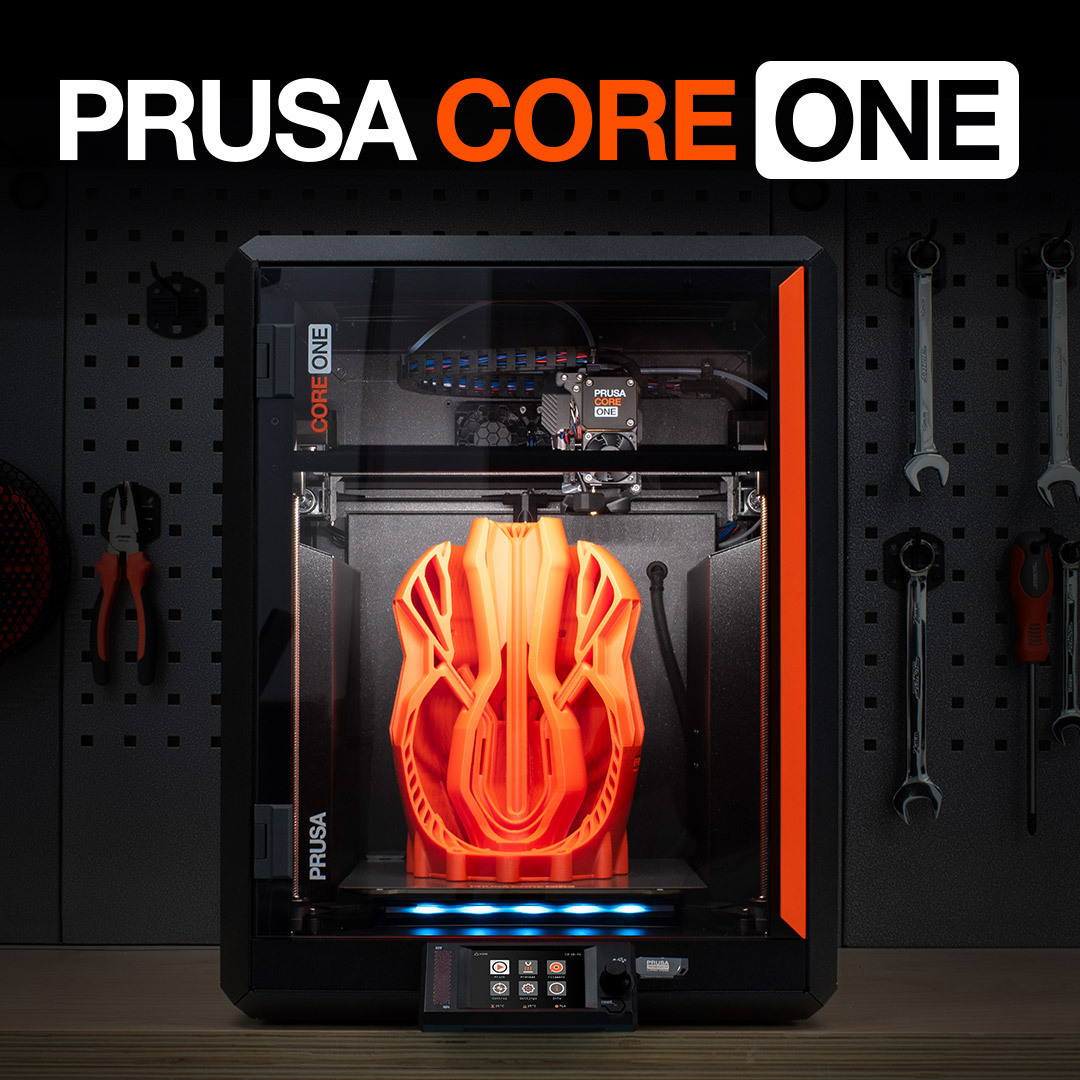
Introducing Prusa CORE One – our fully enclosed CoreXY 3D printer with active chamber temperature control! 🎉
https://t.co/NrDQQgT53X
It’s precise, fast, and reliable, handling everything from PLA to Nylon with incredible print quality and high dimensional accuracy. We've packed everything we've learned from the XL, AFS and HT90 into it. ✨
👀If you're at Formnext see it live at hall 12.1, booth G39
So cool to start seeing LeRobot, @huggingface and open-source more and more prominent in robotics. Openness, collaboration and democratization in full-force!
The world is torn between two factions, one lives in tune with nature, the other believes in the supremacy of men. Not an easy decision who to align with, but certainly one that will drastically change the story you experience.
Just one more day! #indiegame#rpg#pixelart
Uh, we're in Popular Upcoming already. Expected this to happen like 24 - 48 hours before launch, not like 5 days before. That's HYPE! 🐗
#gamedev#indiedev#steam
C is Latin, the root of all modern languages, the whole universe used to speak it.
C++ is French, it’s Latin with fancy rules, used by the elite around the world & in specific circles.
JavaScript is English, everybody speaks it, most speakers speak it poorly and others don’t bother learning another language.
Java is German, it’s verbose, over-complicated and it made me cry several times. I won’t elaborate.
Python is Esperanto, it was created to be so easy everyone could speak it. Its speakers could benefit from a shower once in a while.
Rust is Russian, most speakers have an authoritarian left background and want to spread it worldwide.