@thsottiaux The reset landed but I had a banked reset expiring 10/22 and it vanished by itself. This happened on two accounts (business standard seats) - feels like a bug
@swombat@navuud@learnwithparam Looks like you didn't pay attention to the video. The ad spend is $475k for the past 14 days :D (and no ROAS shown) So he's spending ~$1M/mo to make $550k/mo revenue. This is only reasonable if you're in aggressive scaling mode and your expected return from the ads is months out.
@chhddavid Oh so now it's Kimi and not Jev or any other of your previous spam posts linking the same "article" with a different clickbait title to promote your sh*tty shipper website? Reported for spam and blocked
lithos-metal runs fast... like Qwen3.8-27B at 200 tok/s peak on an M5 Max chip fast 🚀 And now it's open-source.
The LithosAI team combined megakernel and DSpark optimizations for @Apple silicon: lithos-metal uses one Metal megakernel per layer mixer.
That's how it runs Qwen3.8-27B 2.1x faster than MLX, 2.4x faster than Ollama, 4.5x faster than vLLM-Metal at 32K context.
Explore the code, try it on your Mac, and share what you learn. We'll keep working to speed up local inference across more models and devices.
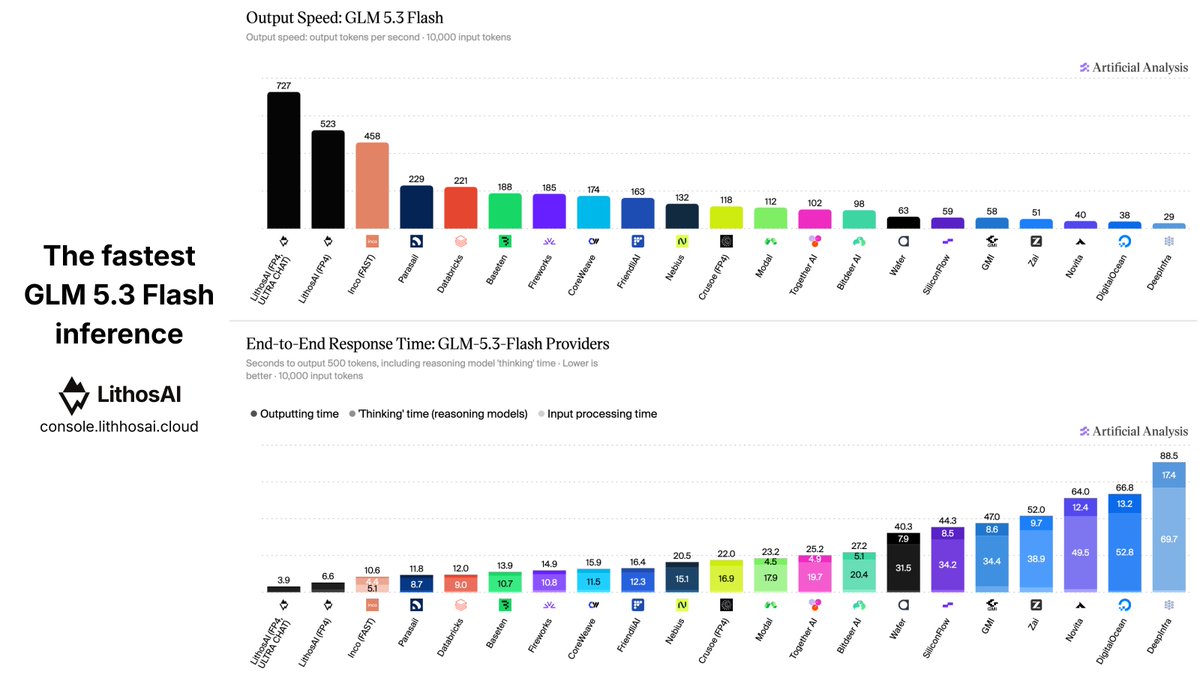
727 TPS, 3.9 seconds E2E response time for 10K input. 937 TPS, 5.9 seconds E2E response time for 100K long context. @LithosAI now has the fastest, lowest-latency inference for GLM 5.3 Flash.
And as my team shared a week ago, GLM 5.3 Flash is in good company with our DeepSeek V4.1 Flash and Kimi K3 that hold the #1 spot on the @ArtificialAnlys output speed and E2E latency leaderboards, too.
Very gratifying for our team to see, but what we said before is still true now: production performance is the only benchmark that actually matters. And there’s a lot more than inference that slows agents down.
Our focus at LithosAI is rethinking agent performance across the computing stack. Faster inference output speed helps get us there, but it’s not the ultimate goal.
What multi-agent systems need is lower end-to-end latency across the entire agent loop. We’re getting our users there with low-latency inference, and now with our LithosBox launch, low-latency sandboxes, too.
Helping our users build agents that get useful work done faster, at significantly lower cost, is what we’ll continue working toward.