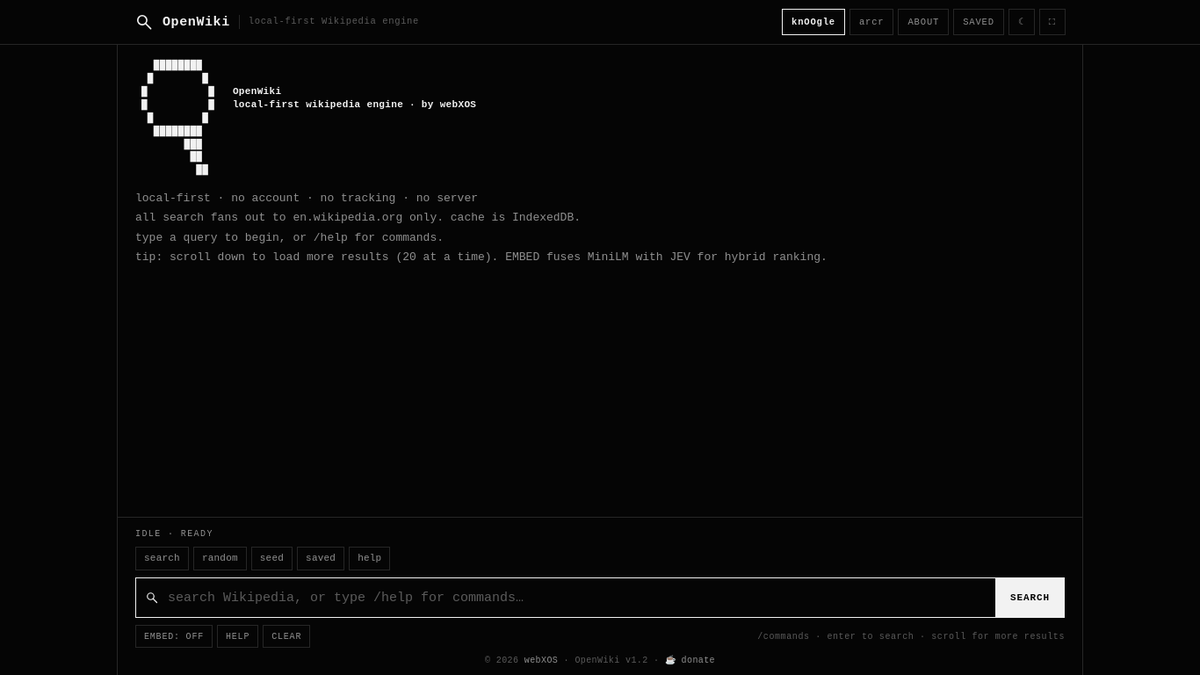
All of Wikipedia fanned to api calls in one HTML app: https://t.co/GZoo2F0Muc @openwikipedia
EMBED fuses MiniLM with JEV style determiners for hybrid ranking.
One gigabyte of Wikipedia losslessly compressed to 105.39MB with self-learning AI transformer model — 'tufazip' needs two Nvidia B200 GPUs and about a week to compress or decompress https://t.co/SMwlcQip8R
@potus@jd@PeteHegseth
We cannot continue to back a country that is going to make us look terrible. Nothing anti-semitic about this - this is just the truth. There are reasons why the Republicans lost the midterms - people have had enough.
SFT is more like getting a haircut with a chainsaw than it is “fine-tuning”! Should just be built into primary training.
And having a “system prompt” is silly! Default behavior should be sensible.
The above are already true for Tesla AI (not yet deserving of “super”). It is the most efficient AI on Earth.
FSD V15 goes to wide release next month. It will be something special.
SFT is more like getting a haircut with a chainsaw than it is “fine-tuning”! Should just be built into primary training.
And having a “system prompt” is silly! Default behavior should be sensible.
The above are already true for Tesla AI (not yet deserving of “super”). It is the most efficient AI on Earth.
FSD V15 goes to wide release next month. It will be something special.
"Defend the Police" They said. The democrats didn't deliver but Elon did!
There are alternatives people - the police could focus on violent crime and the rest could be automated. Including Fraud (George Floyd example), Traffic, and even Drugs TBH.
"Defend the Police" They said. The democrats didn't deliver but Elon did!
There are alternatives people - the police could focus on violent crime and the rest could be automated. Including Fraud (George Floyd example), Traffic, and even Drugs TBH.
MBT (Multi-Branch Transformer) runs parallel independent Transformer block branches after shared layers, then fuses them. Joint-KV shares the cache across branches, cutting KV storage up to 34% and boosting decode throughput up to 51% while improving loss vs sequential models at matched compute.
DFT refers to Discrete Fourier Transform token mixers (FNet lineage) that replace quadratic self-attention with FFT-based global mixing at O(n log n).
QFM (Quantum Frequency Modulator) is an experimental attention-free approach: tokens become frequencies that interfere in a lattice; the spectral signature drives next-token prediction.