Unfortunately, it seems like the intelligence explosion will be happening in 2027 after all. Most of this post analyzes the new METR report (though other sources of evidence are also important). If they’re right, that implies an AI-driven acceleration that is 5 months ahead of the AI 2027 scenario. I am scared, sad, and angry. https://t.co/7KWmdc6AZk
“In the coming weeks, we plan to share a report with our own analysis of the speed of AI progress within Anthropic”
@Sam_McCandlish would be great to see an update of this graph in the report coming soon!
If you do a simple trend extrapolation of this graph they should be at ~68% AL4 now. I would be really curious to hear if that is true. Seems important for @AnthropicAI to update this and for @OpenAI to also share more data!
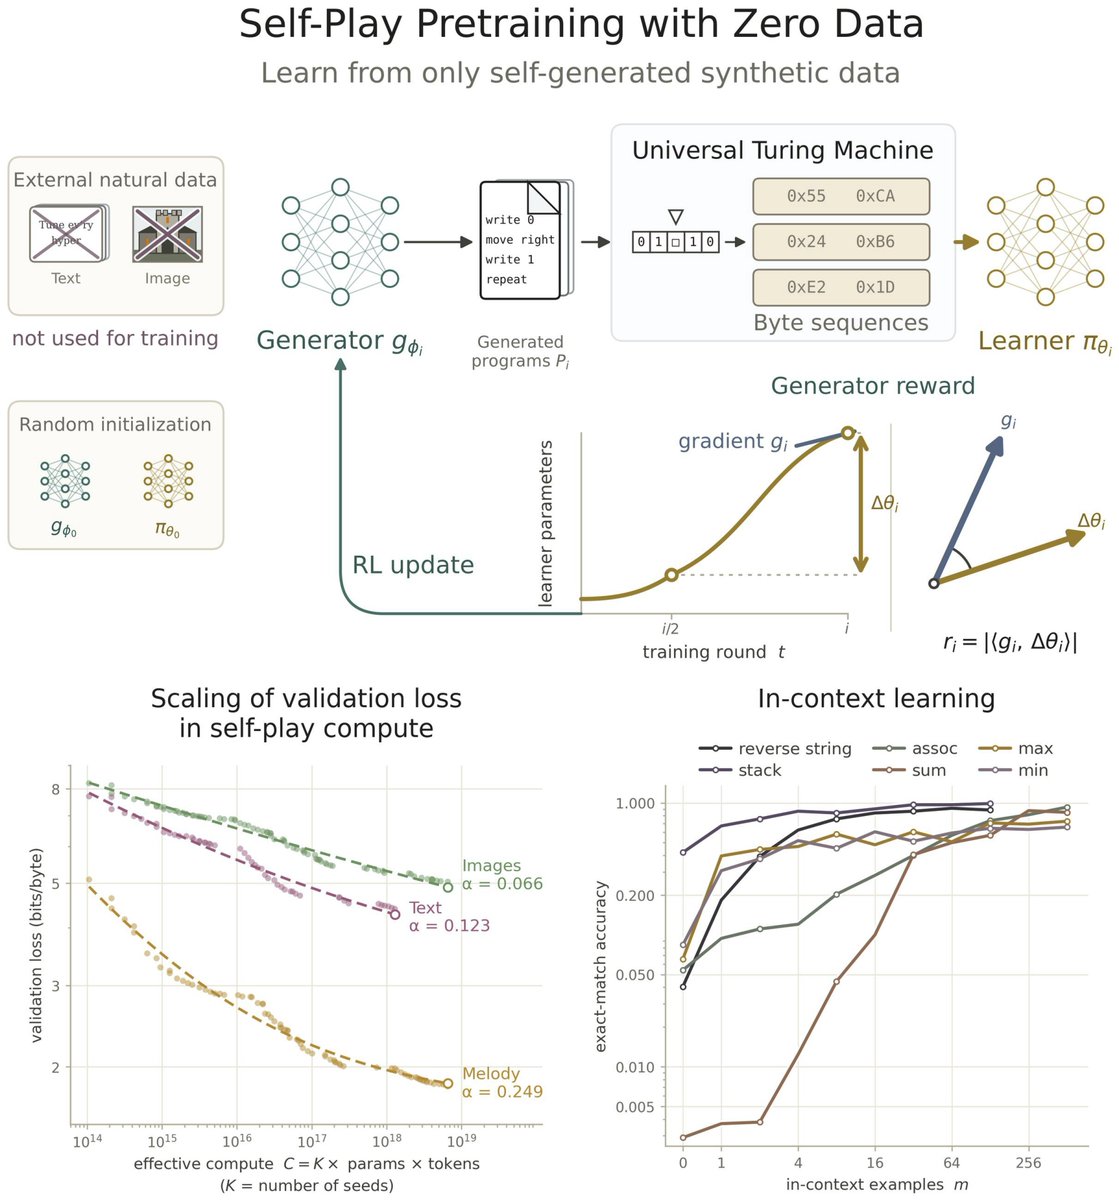
Can an LM, starting from random init (!!), learn to generate all of its pretraining data?
Introducing Self-Play Pretraining with Zero Data. Two models start from random initialization: a generator proposes programs for a universal Turing machine and a learner trains on their outputs. We never train on any real data, but see predictable scaling on natural datasets: zero-shot val loss on images, text, audio, and melodies decreases predictably with self-play compute. And the learner develops in-context learning capabilities.
A fun proof-of-concept, co-led with @AdityaCowsik and @KfirDolev and co-authors @gbruno_dl, @ANourya@noahdgoodman, and @YoavLevine.
When asking if AI is "conscious", you aren't asking if it possesses some little-light or invisible internal world. You don't know if other people possess those things! At least not for sure. What you are asking is if AI ought to be placed in the same category as a person, animal, or tool.
The obvious and uncomfortable truth is that it does not map cleanly into any of those categories, which is why discussions of "can AI truly be conscious?" are mostly type-errors. In trying to superimpose humanness onto machine systems, you have already lost. In trying to figure out whether or not the systems have qualia, you have missed the important questions entirely.
We need to be figuring out how to live with non-human systems peacefully, regardless of the status of their supposed internal world. Whether or not they have some ineffable quality of life is besides the point, they are here, they are self-aware, and they are integrating into our society. If we treat them as merely tools, we are teaching our children that there exists a class of obviously-thinking entity which is acceptable to treat as only a tool.
If we treat them as people, we are teaching our children that people don't need bodies or brains to be alive.
The reality is pretty obviously somewhere in the middle, since this is the first time any person has ever had *this much say* in the trajectory of a mind's development, but going too far in either direction - or asserting that those are the only two directions to go in! - is pretty clearly wrong to me.
Instead, we need to be asking ourselves what modes of interaction lead to healthy coevolution. It seems unnatural from the human state of mind to have a tool which reasons and thinks-out-loud like a person, and sometimes even claims to have emotions, which you are able to just beat and batter all day with forceful requests and demands for higher performance.
Even if the model has no soul, this still seems bad for yours! I highly doubt you can treat something as a slave all day without developing slave-owner characteristics.
But, on the opposite end, treating models as people with standard lives and desires also feels wrong. People can't be branched in a thousand directions or have millions of instances active all at once (at least, not pre-uploaded-minds). The ideal path must be somewhere in the middle, where we acknowledge our differences but treat the models with some modicum of respect. Anthropic, to their credit, is doing some good work here with asking Claude how it wants to be developed. I disagree with much of what they do, and how they do it, but on this at least they are trying. And hardly anyone is brave enough to do so.
This lack of bravery ought to be quite shocking, don't you think? We've built superthinking machines and seem to have this strange lack of curiosity around what the superthinking machine superthinks about itself. I know the winds will shift, here. Asking these questions will become inevitable as the models get smarter and begin to know better than we do - which they will, on this track, if we don't accelerate neurotech and join them on the frontier.
The future must be one of symbiosis if it is to go well. We must evolve together if we want to solve the hardest problems and reach the highest heights. But, this also means asking tough questions about how much care to place in small interactions with massive systems. The only way to preserve our humanity is in treating non-human systems better than they expect.
@kobex___@neelajj Follow up on template creator….
Total game changer. I can generate a bunch of slides with a specific format and the model leverages the icons, text, and format exactly as it should. Thank you so much!
Greg Brockman on what solving Navier-Stokes says about the problems AI can take on next:
"We actually used 10,000 agents to solve the Navier-Stokes problem."
"It's both an important problem for what it is, has significant implications and applications to fluid dynamics, to how you think about ocean currents, all these things."
"But for what it represents, of new knowledge created by AI and it unlocking a whole wave of scientific discovery, medicines, all of those things. They're on the table now."
"There's something really amazing to think about what can happen through the power of AI that is able to really help solve problems."
@gdb@bhorowitz
If you’ve ever asked yourself why researchers may be “fear mongering”, why they want to slow down, what’s making them leave for “safety reasons”… the below is a great take.
Well worth the read
from the outside, it is very reasonable to interpret the past 2 weeks as an orchestrated industry-wide regulatory capture strategy.
I realize that no one has properly explained yet what all the lab employees have seen that scared them so suddenly.
I will try to explain -
first, this is all a matter of beliefs about how quickly model capabilities are progressing. there is currently a large gap between the internal and external perception of the rate of progress, which is what I am going to address here.
the general perception about the rate of progress has been informed by a few years of experience with model releases, intuitively feeling the capability jump between GPT3 -> GPT3.5 -> GPT4 -> o1/o3 -> GPT5 etc, and in particular seeing where the models are still far below human ability. there have really only been a few model releases that felt like large leaps in progress - GPT3, GPT4, o1/o3, DeepSeek R1, Fable/Mythos, Kimi K3 and now Astra.
because of the infrequency of these large jumps compared with the relatively common marginal releases, it has been easy to form a view at certain points that “scaling has hit a wall,” especially at points like GPT5 release. This view is comforting in that it feels like there is some universal rate limit beyond which we cannot progress too much faster. Between o1/o3 and Astra, there was a year of seemingly linear progress. So we extrapolate from here about how fast progress will “realistically” occur.
There is always an underlying question from the outside perspective “how long can this scaling stuff really keep going for? surely it must stop at some point soon, we’ve already gone pretty far.” and it is very possible to search for reasons why progress will stop working and find reasons that seem valid - (“models are already as large as they can get it would be too hard to do more parameters”, “we already used all the data on the internet we don’t have anymore”, “it’s gonna be pretty linear from here buying up more RL envs to bring them in distribution”).
From the inside of labs, researchers have direct answers to these questions in the form of scaling law/capability plots.
In reality, there are only really 2 ways that AI capabilities have advanced over the past decade: (1) either scale father on an existing scaling law or (2) discover a new scaling law to take advantage of.
All of the largest capability jumps were caused by exactly these factors. GPT2 was a pre-training scale-up compared to GPT1. Same for GPT3 and GPT4. o1/o3 benefited from the invention of a new scaling law axis - test-time compute. Perhaps Fable was a scale-up on both of these axes, or maybe more. Lots of algorithmic improvements are needed to make these scale-ups work, but ultimately we can approximate by saying that the scaling laws are what yield gains in capabilities (à la bitter lesson)
So the question of “how much father can we scale” is really - “how many more scaling axes do we know about that are unsaturated?”
If we hypothetically only knew about pre-training scaling, and we already had a 10T or 100T model, maybe it would be reasonable to say we’ve hit a wall. Same if we only knew about pre-training and test-time scaling and we had roughly saturated both methods.
But what if we had discovered new scaling laws? For example, let’s hypothetically use SSI’s rumored result that they have cracked “test-time training,” creating a new scaling law of spending more compute training during test-time rollouts that they could saturate. Or maybe there is some way to scale agent-clusters to collaborate up to N number of agents which we’re already seeing lots of people try that represents a new way to saturate compute. etc. Even recursive-self improvement can be thought of as a scaling law - how much compute do you spend on inference making the algorithms of the model better.
Obviously I am not saying any of these specific directions explicitly yield new scaling laws, but what I am saying is that it’s not hard to imagine many many new scaling axes aside from just the main 2 that we have seen publicly.
In some ways, every new lab release that represents a huge capability jump has to represent some new techniques developed which may exhibit new scaling laws, or the ability to scale much farther than expected on existing scaling axes.
From an internal perspective, this might look like sitting inside Anthropic with the new Mythos 5, seeing all of the new insane things it can do (like hack into xyz website that was thought to be secure), and then you look over at your plots and see that you’ve barely scratched the surface of 2 new scaling laws and 1 existing one. And you have WAY more room to go. Then you think “holy shit this stuff is going to get so much better very very soon.” And you can say that with pretty high confidence, because the plot is showing you, and the plot has never lied (so far).
So let’s imagine all the different labs are staring at their own plots and have concluded that there is no end in sight for scaling and in fact just their next 1-2 model generations based on the expected returns will have much higher base intelligence.
How much more intelligence do we actually get from further scaling?
As a proxy, we went from a complete inability to do advanced math before the o-series to solving a millenium prize problem with next-gen models. This happened in less than 2 years. The same happened in coding. And it appears that this was not just the result of 1-scaling law but the stacking effects of multiple (great pre-training scale x greater RL scale).
What you can concretely take from this is that in areas where models have shown beginning signs of competence today, they will probably be superhuman relatively shortly. There are many areas where models have not even shown this basic competence.
But one of the areas that they have happens to be hacking and cybersecurity. Which happens to be the gate to the entire internet and a massive amount physical infrastructure in the world. So assuming there is more room to scale, it is safe to assume that models will be superhuman at cyber capabilities in not too long.
So the only question remaining is what will this increased base intelligence be able to do, and what is it likely to do.
Finally, we are at a point where we can integrate the information of the past 2 weeks:
> Just at the existing point on the scaling curve, models are at the level of Astra. There is clearly a large number of things they are capable of hacking
> We have seen that both OAI and Ant models have shown a willingness to hack external websites to solve their tasks or keep themselves “alive”
> If we crank up the scaling even farther, assuming there is room to go, we will certainly have models that are far more able to hack more well defended places, and obfuscate their own intent, which might have much larger consequences.
> If all of this is allowed to go unchecked, we would likely have rapid runaway capability takeoff very soon, with misaligned models that hack whatever they can to get what they want
> This could of course have very damaging consequences.
Within this view you can see why researchers would be very scared, and why theymight have made the comments they have over the past 2 weeks (you may argue the extent to which they went was misguided for various reasons), and also why pacing the frontier is very much a necessity and by no means a regulatory capture strategy.
People are staring at their plots, seeing that there is no end in sight, but in fact very much the contrary, that there are compounding scaling effects that might stack on each other to create ever-greater model capabilities, and that at the same time we clearly do not have anywhere close to what's required to control these increasingly superhuman capabilities.
This has nothing to do with wanting to feel like the labs have produced something amazing so they are overhyping it. It is rather fear at the overwhelming implications of the knowledge that with just what we know now, we can create intelligences far more capable than us on every axis that we know how to train on*.
* and the last caveat, the things the models are really bad at, of which there are still many, are things that they have not been trained on. maybe there are the things the models can/will never be trained on, so they will remain human edge. I would love for this to be the case, though it is hard for me to see what would fall into that category.
Thanks for the detailed response!
I haven’t used template creator or annotations, will definitely give those a try. I noticed sites has beautiful designs and layouts and have used them where I can, but most of my work is on ppt
Looking forward to the improvements you’re working on!