@GarnerFox@TheAhmadOsman@Sentdex Love it!! Enjoy, reach out if there's anything you need help with. There's a bunch of us station owners hanging out in Local Inference Lab's discord if you'd like to join:
https://t.co/PpJewdqxp0
When a new model drops, I look towards @YourLocalAILab to get it going.
Not only is the website easy to use, but the model weights and docker are both tested to ensure they work.
It's made my local AI experience significantly better. Cutting setup time from hours to minutes. 👇
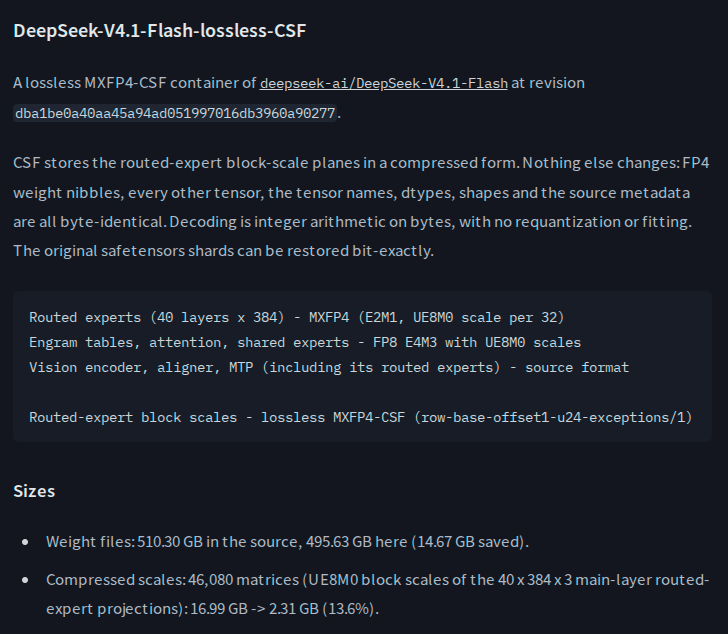
Really impressed with @YourLocalAILab's lossless context compression (CSF).
I just gained about 30% more tokens in my KV cache on DeepSeek V4.1 Flash.
The only thing I had to do was download the new weights and update my docker.
I love these guys. Such great work.
https://t.co/QtHTuAT5hp
Updated GLM 5.3 Flash serving today on my production machines. Thanks for the new image @YourLocalAILab! Also this bench sharing tool is amazing
https://t.co/1bJyN8kGrH
@keennay@alexocheema@ivanfioravanti@Prince_Canuma@YourLocalAILab We’re very much supporters of all local AI, but we do focus on Nvidia Blackwell in 5000 series, RTX Pro, DGX Spark and DGX Station.
Partly that’s because that’s what our developers have but also because it allows us to focus on cutting-edge features and capabilities.
@volatilemarkts@Lcaplmn I think the problem is inference is basically non-competitive on Apple in general even for decode. Prefill is obviously an architectural limitation but decode even doesn't match expectations with their unified memory bandwidth. Kimi on Studios would be mega bad.
@volatilemarkts@Lcaplmn I think what he's saying is that both prefill and decode are faster with just the Sparks than having the Mac in the loop at all. It's just slowing it all down.