@Dataphil3 I set a cron and scraper. Anything over 8TB-12TB that’s under $200. Mostly open box returns.
You’d be surprised. But they go very very fast so have them preload to a cart once found.
I did get a 16TB for $299.. months ago. Got to be fast.
Ordered 2x Seagate 28TB (ST28000NT000) hard drives and a UGREEN DXP4800 GT NAS. I'll be retiring my old 2-bay NAS and moving its 14TB drives into the new one.
Total 84 TB of storage!
172 tok/s after a 1M token prompt on 4x DGX Sparks, up from 151.5. That's GLM 5.3 Flash in TensorFold 1.3.3, with the same output tokens.
Long context is usually where speed crawls. Here the gain comes from a new kernel @MiaAI_lab wrote for it.
Something I built last night .
Rack for my ASUS TURBO AI PRO R9700 GPUS .
Each AMD Strix Halo gets a GPU for the Decision, Vision, etc. think: high prefill tasks .
Can’t wait to show you the software and how it wires together with the models.
CUDA is not the moat for NVIDIA over Apple Silicon that people think it is.
An Apple machine-learning framework (MLX) running on Linux through Vulkan just outran CUDA on NVIDIA’s own silicon.
Just shipped an update to Omarchy-mlx that puts MLX 25% faster than CUDA on an RTX 5060 Ti.
https://t.co/kTI8Iev3uc
124 PRs merged in one day. Absolutely insane when you think where this project was a few months ago.
Six of my pull requests got merged since Monday, in the releases before this one.
The one that means the most to me is the first piece of Inkling 2 Small. It serves nothing yet, it reads the model's config and weight map. But that's where native Inkling on four DGX Sparks starts.
I opened my next piece today.
Thank you @ashxhart 🙏
WOW ! @thinkymachines
🧠 Thinking Machines just dropped Inkling 2 Mini
🔁 Looped transformer: the middle layers run 3x per token
⚙️ 26.4B MoE, 3.4B active
💻 ~20GB in NVFP4, runs on a laptop
🛠️ Built for agentic coding + tool use
🔓 Open weights, on Tinker + Hugging Face
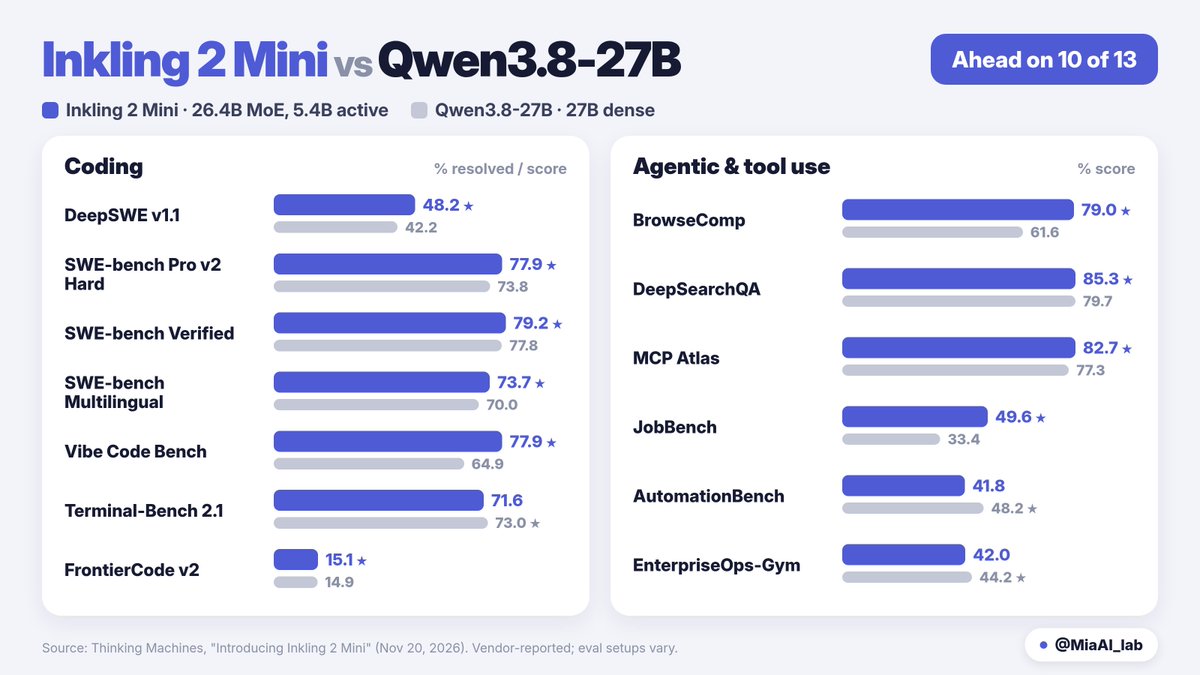
Some of you thought that Inkling 2 Small was too big at 594B parameters. We heard you: Inkling 2 Mini is a looped transformer with just 26B parameters, small enough to run on your laptop, powerful enough for agentic work with a score of 20.1 on AA Index.
https://t.co/9HzaUMwghb
Inkling 2 Mini from Thinking Machines! 🔥
- 26B total params, 3.4B active (5.4B looped)
- Weights just 20 GB
- Small enough to run on a laptop
- Ahead in 10 of 13 in coding vs Qwen3.8-27B.
I'll try it out on my dgx spark.
Link below.
The sleeper build nobody's talking about: a 5090 laptop with 64 GB of RAM.
$3999 on Newegg-open box.
Tonight it ran DaisyRose-27B (a Qwen 3.8 27B variant) at
194 tok/s decode.
One stream. One laptop GPU. About 150 watts.
Plain prose: 125 tok/s.
Same model on our first engine: 74 tok/s before @tensorfold_dev..
The difference is @ashxhart's TensorFold plus a DFlash2 drafter.
We run @MiaAI_lab's models whenever we can.. @tensorfold_dev always!
A 27B that thinks this fast, on a machine that closes like a book.
Real output, real speed, in the video.
But speed isn’t the main reason we built it. Memory is.
This laptop never forgets. It holds 290,000 tokens of our history warm in RAM.
Its job: watch all 17 machines in the house, around the clock, and have the right memory ready for each one before it answers.
One quiet laptop, remembering for the whole house.
@MiaAI_lab@ashxhart@tensorfold_dev@NVIDIAAI
Two of my pull requests made it into TensorFold 1.3.2.
One of them is a bit more "special". I bought the two RTX 5060 Ti to see what two cards can do together. They sit on a normal consumer board, and one of them is held back by its PCIe slot.
They keep impressing me, alone and as a pair. That PR is for Qwen3.5 EXL3 split across two GPUs on CUDA.
The other one is for Qwen3.8-27B on a Mac. While a reply is still thinking, the server now counts only what's left of it, so a short chat reply doesn't get stuck behind a long prompt.
Thank you @ashxhart 🙏
Really excited to see how fast TensorFold is improving. And now that my agents (mostly) follow Ash’s excellent ATC system for coordinating PRs, I am proud to be a part of this release and many more!
Made two-stream decode on my M1 Max more than twice as fast today, on Linux. Same model, same output, just much quicker. Open source: https://t.co/aPW8Y8pYlm