Capable models have gotten cheaper. Search hasn’t, until now.
Today we’re introducing Fast mode for Parallel Search: frontier-quality web search for AI that’s 10x cheaper than the default from model labs.
- $1 per 1,000 results
- 700ms p50 latency
- #3 on Artificial Analysis Search Index for intelligence
Built for task-efficient models like GPT-5.6 Luna and DeepSeek V4 Pro. 🧵
This project was the result of deep obsession by a very talented team. And executed under extreme time constraint.
Across all disciplines, that is how we operate at @p0
@RomanP918791 This leaderboard isn't yet optimized for measuring speed, as factors like harness setup, server locations, and inference providers can heavily skew results.
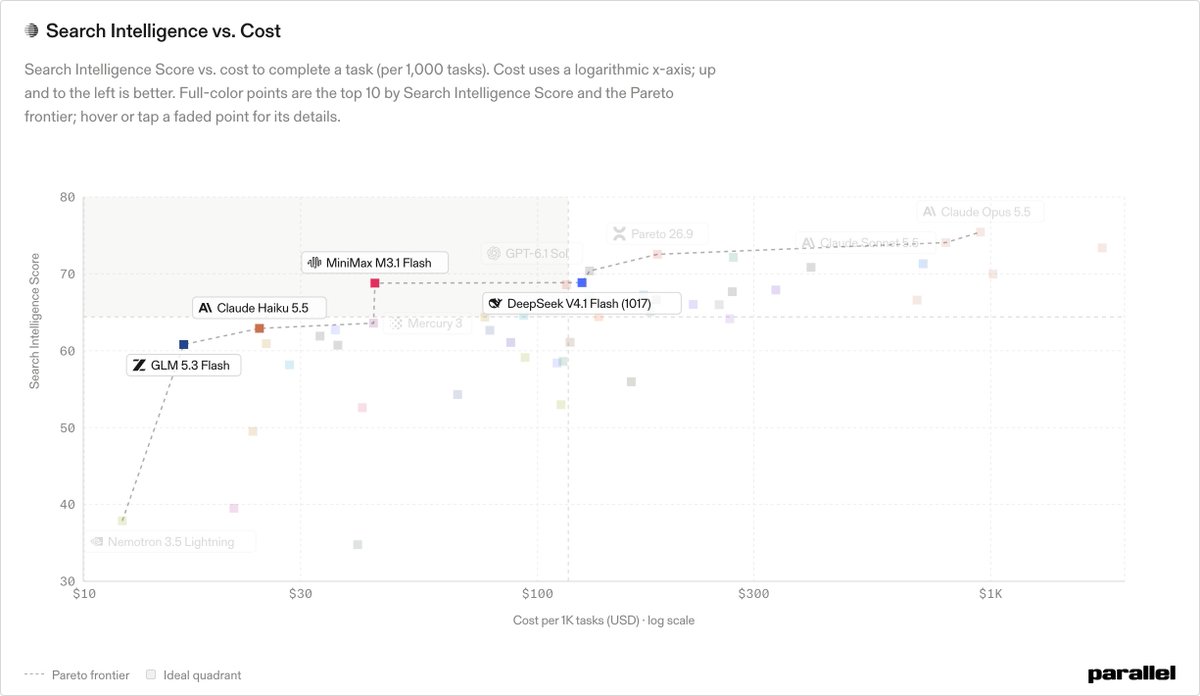
MiniMax M3.1 Flash is now #1 on our search capabilities leaderboard for efficiency.
It delivers web research performance with Parallel Search similar to DeepSeek V4.1 Flash (1017) at ~3x lower cost.
MiniMax M3.1 Flash: Space Performance + Bunny Speed
🚀🐰 Yes, Space Bunny - which has topped global leaderboards with 200T+ tokens - was an earlier version of M3.1 Flash.
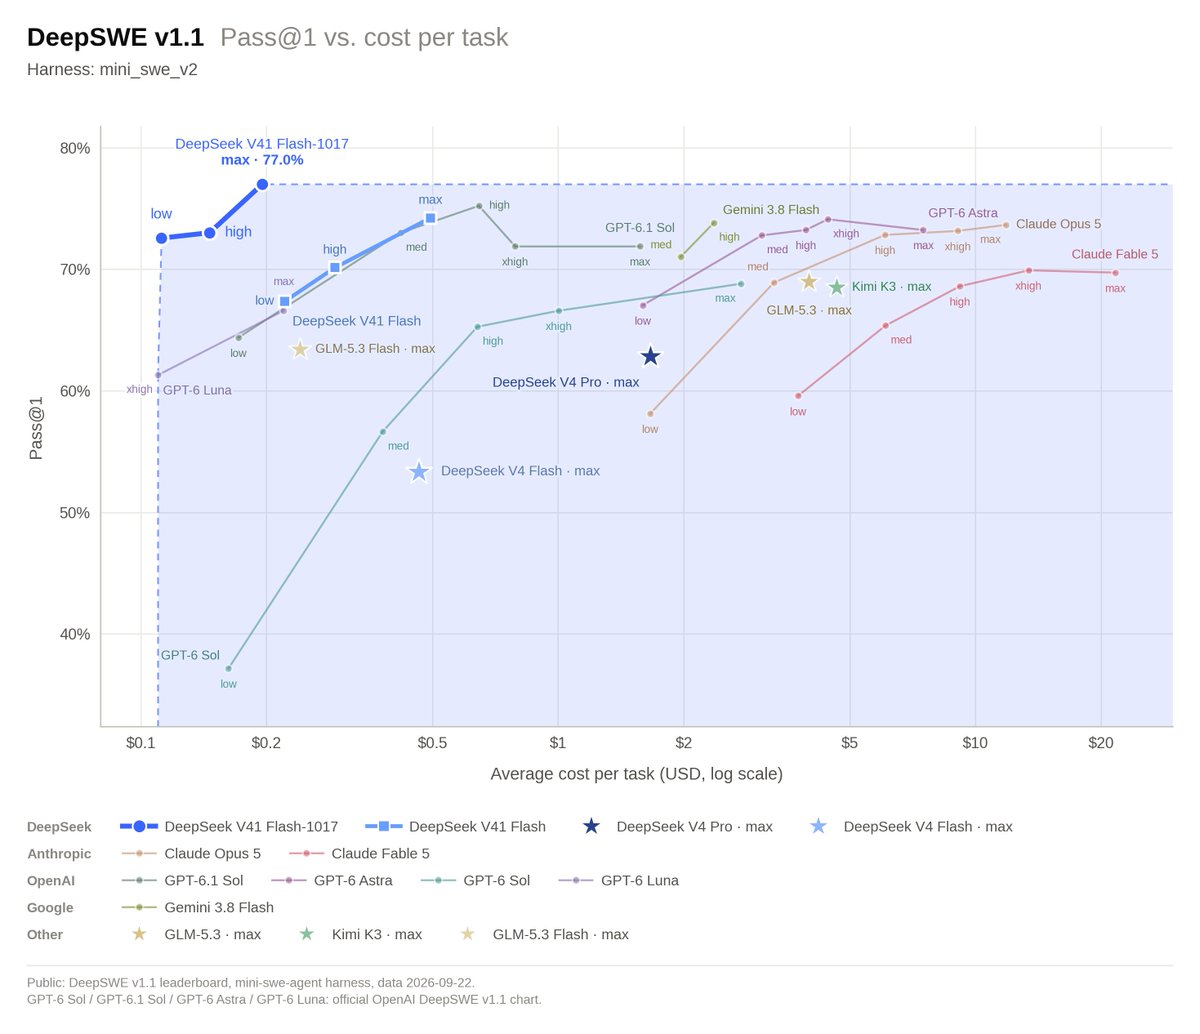
💰Redefining the performance economics of agentic AI. M3.1 Flash achieves frontier-level intelligence across key tasks such as Cowork (Automation-Bench: 62%; ALE: 30%), Coding (DeepSWE: 74%) and Visual Reasoning (BabyVision: 91%), at 1/3 the cost of M3 and 3x the speed.
API pricing (flat rate): $0.15 / $0.60 per 1M input/output tokens, with cache reads at $0.015 / 1M tokens.
Model weights will arrive on Oct 23.
API: https://t.co/fHRdSV73Hr
M Plan: https://t.co/XfJWSyauda
MiniMax Code for desktop: https://t.co/SGmLTI2HQm
Efficiency is a measure of how cost-effectively a model achieves a good answer relative to all other models on the list.
With Parallel Search (fast), MiniMax M3.1 Flash delivers high-quality answers at less than half the cost of the second-best model.
Mercury 3 is the first diffusion LLM we've tested with Parallel Search.
It's Pareto-optimal, delivering capable web research at a price similar to Claude Haiku 5.5, GPT-6 Luna, and DeepSeek V4.1 Flash (base).
Mercury 3 is live: the most capable diffusion LLM released to date.
It outperforms GPT-6 Luna and Claude Haiku 5.5 across a range of benchmarks while running at over 1,000 tokens per second.
More than 40x the size of Mercury 1, 3x more intelligent across standard benchmarks, and just as fast, with a 1M-token context window.
Available today on the Inception API, @baseten, and @OpenRouter .
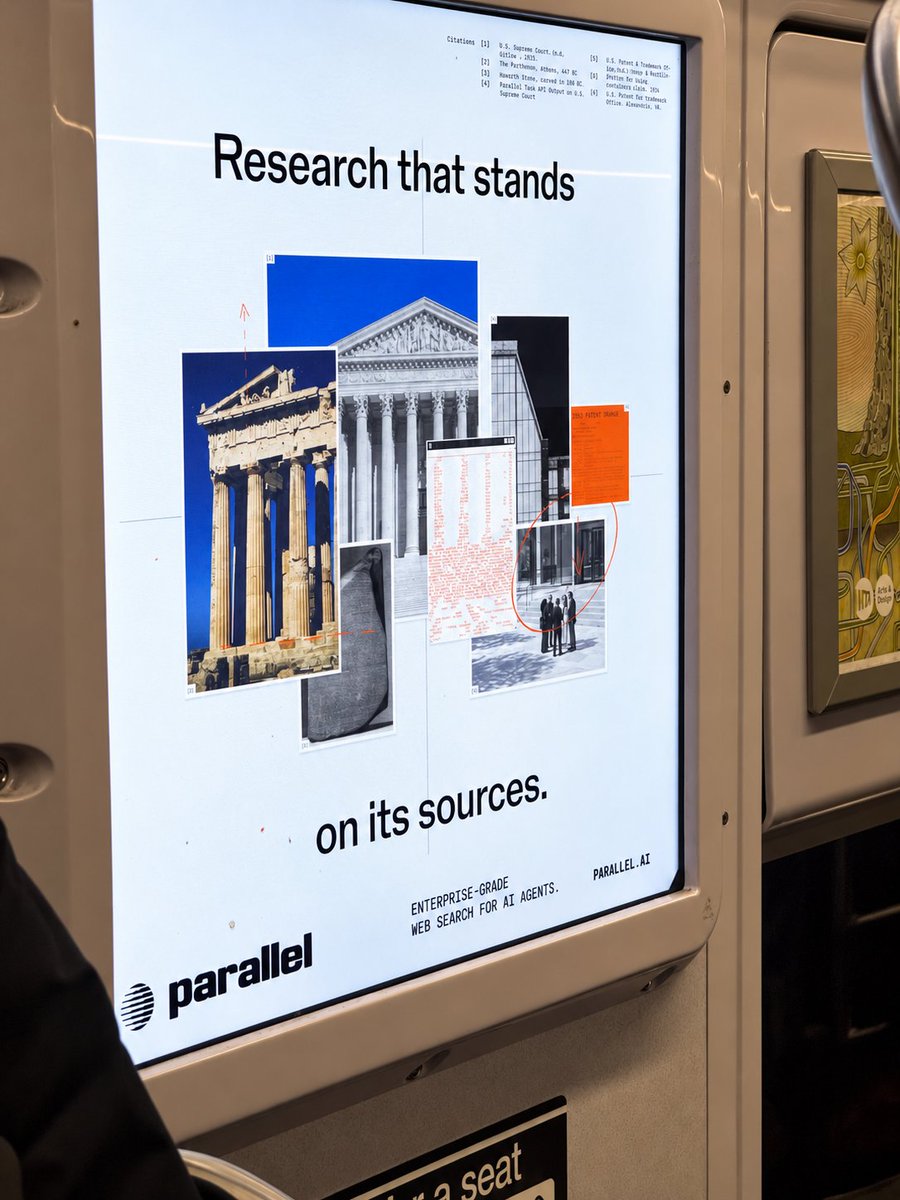
last week, we launched the first batch of our @p0 brand campaign in NYC
every ad is a collage assembled with citations, representing a real research report built on Parallel's APIs
more to come on how we built this. in the meantime, share with us if you encounter it in the wild!
NEW: DeepSeek V4.1 Flash (1017) is the highest-performing open model we've measured.
It's the first to crack the top 10 on the Search Capability Leaderboard across open- and closed-source models.
🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4
The new DeepSeek V4.1 Flash remains Pareto-optimal, with improved research capability, albeit at a higher per-task cost than in its original release.
It now matches GPT-6.1 Sol's end-to-end cost and capability.
Typesafe's CEO @CompleteSkeptic does not trust public benchmarks.
Neither do I, Diogo.
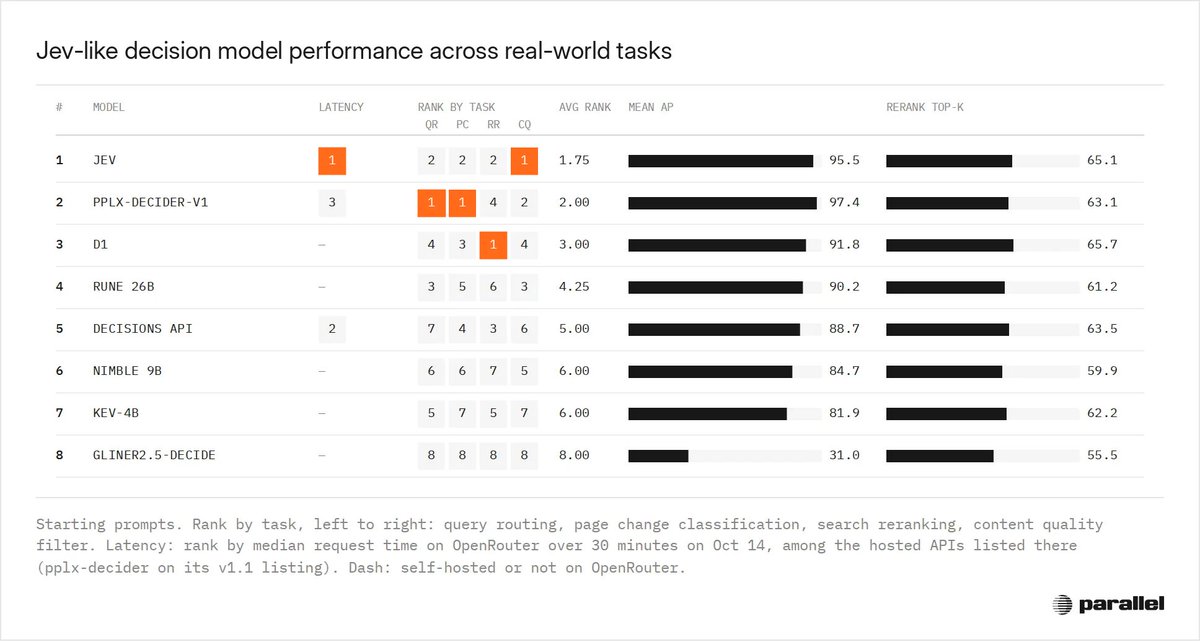
So @p0 and I wrote a blog evaluating 8 decision models on real company training datasets we have personally audited and iterated on.
For what it's worth though, Jev is still on top 👑
https://t.co/Qd2g0Hwp4V
https://t.co/zLFxEX5xXR
We spent two weeks extensively testing decision models on real production use cases. It's been super fun, we learned a lot, and we are sharing our findings! 👇
Just ask @Lovable to build apps with live web data.
Congrats on today’s launch, bringing the full open web to everything you build, powered by Parallel.