New H3 Image is out today, from Prodia. This model excels at high-def, characterful gens and editing images.
Up to 4x cheaper than fal for 2k and 2.5x cheaper for 4k. Single image edits are ~40% less.
Your agent can set it up for you using this instruction:
👉 Integrate Prodia’s inference.minimax.h3-image.base.txt2img.v0, docs link in comment
There’s been a lot going around about making AI yapper videos for sub $3 or sub $2. I made one for 53¢. Here’s the recipe for a much cheaper AI influencer.
1. Character sheets (optional)
2. @inworld TTS – this step is tenths of a penny; stay below 15s audio
3. @prodialabs H3 Fast model + reference audio and the character sheets if you’re using them
4. @MireloAI to re-add the Inworld TTS .wav and some background music (video models compress audio and I want rich audio)
5. Capcut to put our logo on it
DONE!
(prompt and character sheets in comments)
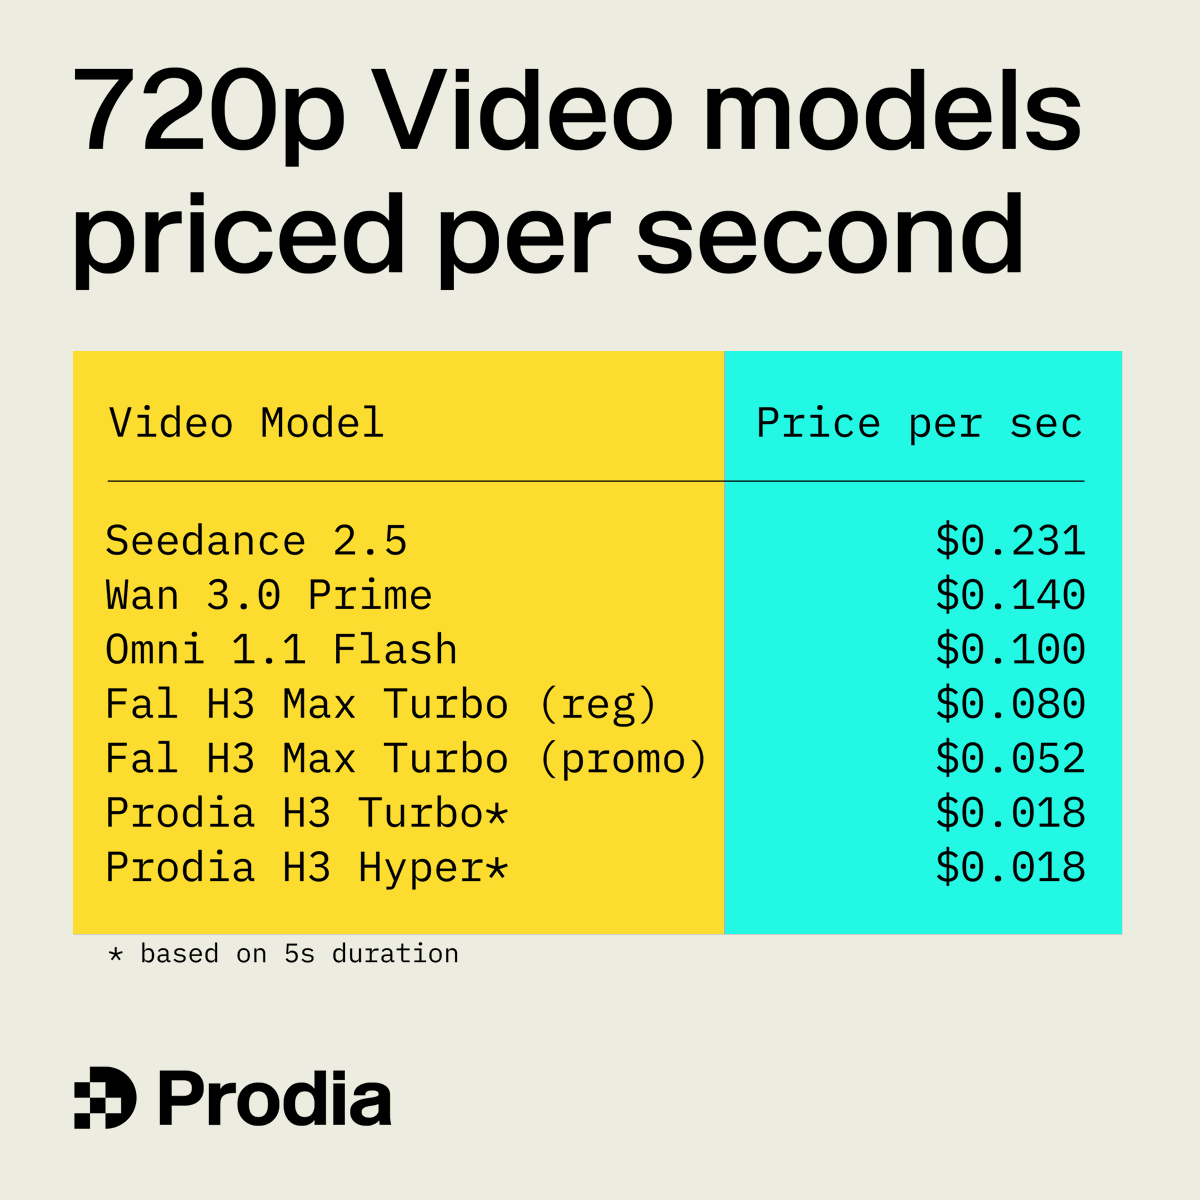
Here’s three 5-second videos with the same prompt. Our competitor’s video is nearly 1.5x more expensive than ours, at 13¢ vs ours at 8.85¢.
Can you spot the difference? Is it worth nearly $500 for every 10k users you add?
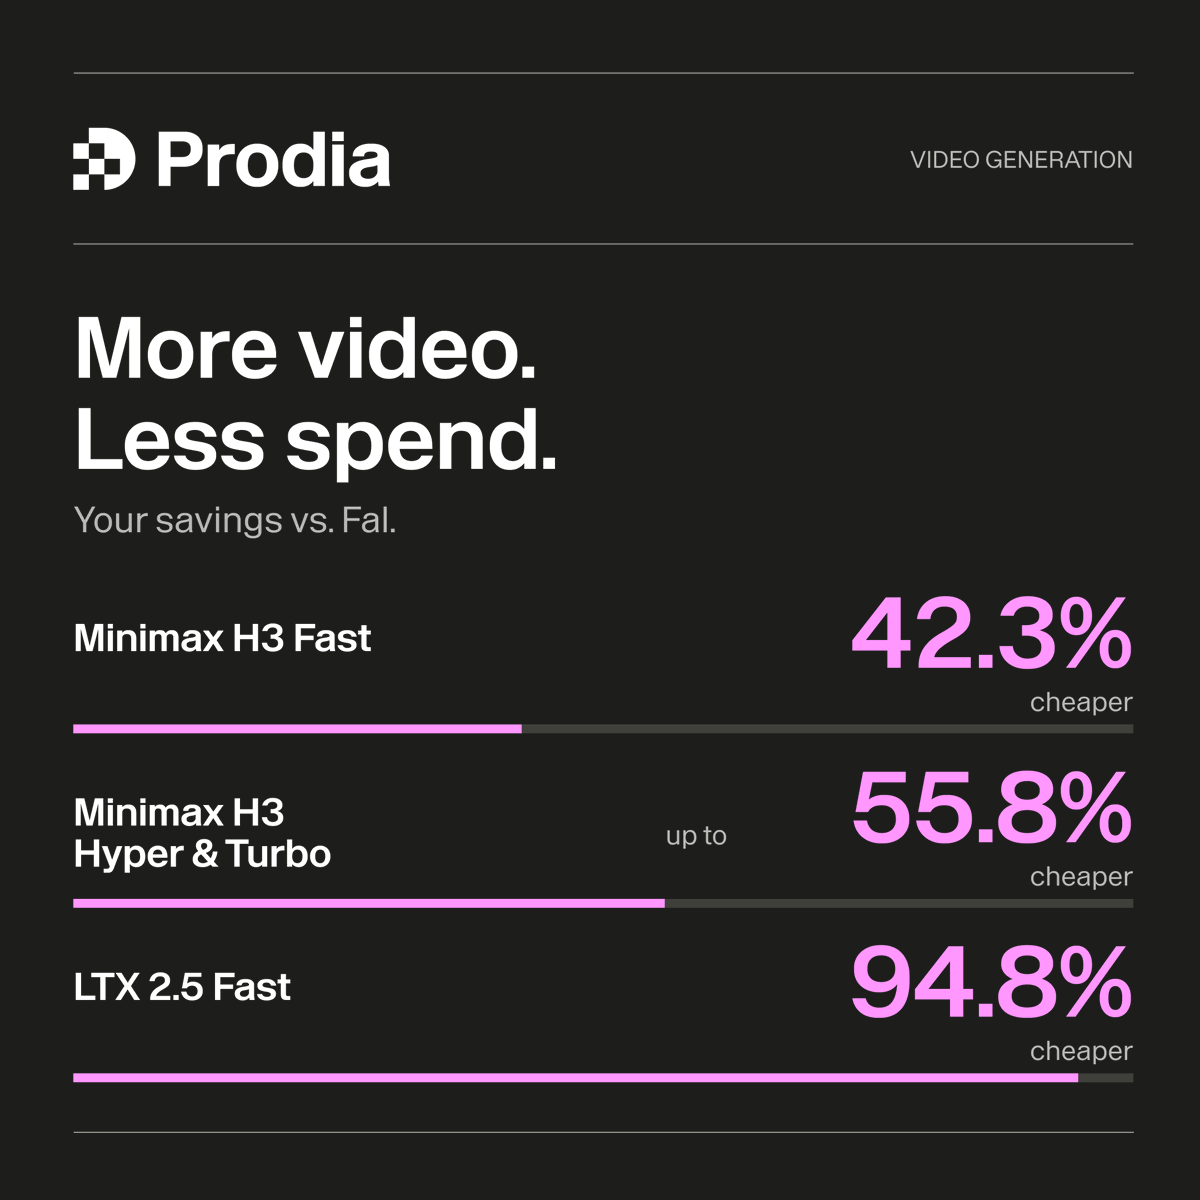
Check out H3 Turbo and H3 Hyper, from Prodia.
How to use this:
1. Look at your use case specific rankings
2. Pick a price point and pick 3 models to test in the spread below that price point
3. Crosscheck against the common pressure tests AA also now has rankings for and check those rankings for problems that are typical in your use case
Example:
use case = nail polish brand wants to make videos for 36 different skin tones
👇
retail & ecommerce use case —> stay below price point —> cross-ref vs the human anatomy rankings —> test, test, test
H3 from @MiniMax_AI is live on Prodia! 🎬
Independently ranked on Artificial Analysis: #1 for video editing with audio, #2 for text-to-video with audio, #2 for image-to-video.
What everyone's shipping with it:
▸ On-screen text that stays stable across every frame — kinetic type moves instead of warping
▸ Audio + picture generated in one pass, in stereo. Lip sync holds across a full sequence, not just one beat
▸ Native audio in 11 languages, voiceover and on-screen text in the same generation
▸ Higher share of usable takes per generation → fewer rerolls, lower spend
I need a break from AI...
switching off from tech... by painting generated art (with Prodia) to paint by tokens? what?
London AI teaming up with @prodialabs & @UseCorgi
to have a chill Sunday afternoon painting in Corgi Cafe London first collab!
Whos coming?
Same 4-model video grid, different prompt. Wan 2.2, P-Video, Seedance Lite, Seedance Pro Turbo.
Variance between models on identical prompts is why multi-model access matters in production.
FLUX.2 [dev] vs. FLUX.2 [klein] 9B
4.5s at $12/1K vs 0.9s at $6/1K. 5x faster, half the price.
For product catalogs and e-commerce thumbnails, that math compounds fast.