this app’s whole user base is just me and twenty of my friends and it’s perfect
i think often of robin sloan’s “an app can be a home-cooked meal” (https://t.co/p9O1DNLpbN), which was, remarkably, written in 2020
now is the time for squad software (squadware?)
The anti-AI backlash in games is mostly hurting indie studios.
Insisting on no AI code in a world where all coding will effectively involve AI is an impossible standard. If fans care about human work, reward games centering human artists & designers rather than policing AI use.
My $0.02
1) The rationalist/EA world has had far better intuitions about AI than the vast majority of the public for a very long time.
2) Anyone who's been practicing their argument for years WILL beat you in an argument, but that's distinct from them actually being right.
We’ve known since 2023 AI could not continue to improve due to “model collapse”—training on poisoned internet data generated by AI. This is why LLMs have made no progress since that time, steadily declining on all benchmarks, and are projected to disappear completely by 2030.
every launch vid now is like
*cavemen making fire*
*model t*
*wright bros*
*moon landing*
*nuclear bomb detonation*
“every great innovation was once called crazy… that’s why today we’re launching AI-powered automated accounts receivable for operationally complex services businesses”
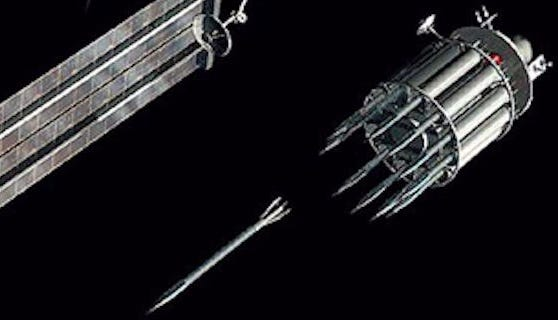
"University researchers built a satellite that tracks people from low Earth orbit and dispatches a 5 kg payload to within .1 meter of their position, traveling at Mach 25 to anywhere on Earth in under 5 minutes. They suggest it could be used to deliver greeting cards."
I like to look at claims like this in case I can improve Ghostty. I grabbed your source and immediately spotted the issue: your read loop overwrites a 64 KiB ring. Everything older is discarded unparsed per tick. You're faster because you're not actually terminal emulating.
It means the number isn't a throughput number. In a kitten benchmark run at the rate you're claiming, roughly 6.6 MB arrives per 60 Hz tick and 64 KiB of it gets parsed. You're read(2)-ing 100% of the data and parsing about 1% of it.
There are other minor issues (a small fixed scrollback in a preallocated ring buffer, no grapheme clustering, throwing away data like OSC 8 URIs, etc.), but the major one is simply that you're discarding ~99% of the input.
For plain text, e.g. your cat benchmark, the final screen ends up looking right, but the scrollback is missing 99% of the file and each retained chunk starts mid-line. As soon as there are escape sequences in the dropped spans, your emulator is fully out of sync and invalid: a cut inside a CSI prints the parameters as text, and any SGR, mode, title, or alt-screen change in the gap is just... gone.
FYI, this is why I don't like when people point at refterm as a terminal benchmark. refterm implements a TINY subset of what a terminal emulator must support, it's closer to a fast file reader, not a terminal emulator.
I also don't mean any shade by this. I like to look at technology objectively to try to learn something and improve my own craft and work. So I'm sharing what I found.
I modified your code very slightly to parse on every full buffer (rather than per tick). And the results are attached. Both use main commit in each repo at the time of this post.
Note the graph is in log scale, the discrepancy between performance for things like Kitty images is measured in GB/s.
One thing about abliterated models is that it makes you very impatient with the non-abliterated models’ refusals to do research that they deem “unethical” for basically subjective (often bad) reasons.
went to visit a friend who’s a ceramicist and works in a studio with no phone signal in a tiny yorkshire village. he doesn’t listen to podcasts or music, only occasionally uses the radio, and when I asked him what he thinks about all day he just said “well, pots mostly”
If you Moneyball your startup idea, you end up selling data
If you follow your emotional startup idea, you end up building a personal assistant
If you build something that people want, you end up forward deploying AI into car dealerships in middle America
I've been cooking on this post for a bit, but with the cyber security events of this week I had to ship it:
Long-live static credentials must die. We never want to rotate API keys again.
Turns out only 8% of cloud and SaaS vendors support secure alternative. This is our call to action to change this AND our commitment to do our part:
- We are requiring vendors on our marketplace to support OIDC
- We shipped @shadcn components to make it easier to ship OIDC configuration
- We are expanding OIDC support on our own platform
The last generation got the web from HTTP to HTTPS. It is on us to move past API keys.
https://t.co/g3r5jk79U8
Railway is compromised, rotate all API keys as soon as possible
Deployments are down so don’t wait to redeploy
Attackers are draining keys in real time, we didn’t lose much but can confirm this is still an active attack
Stay safe friends
Just going to preregister here that I believe the computer security overhang is not a few dozen bugs that get patched and then we're good, there are 100,000s of vulns that are extremely discoverable with infinite free tokens and we're probably going to have to move away from systems that presuppose that perfection is possible.