1/n 🚀 Introducing MobileLLM-Pro: Our latest 1 billion parameter foundational language model designed to deliver high-quality, efficient on-device inference across a wide range of general language modeling tasks – A thread 🧵
🤗Model Checkpoints: https://t.co/t6ocm3wGSB
Work done with my amazing collaborators Ernie Chang, Wei Wen, Igor Fedorov, Chinnadhurai Sankar, Tarek Elgamal, Hanxian Huang, Naveen Suda, Vish Vogeti, Yanghan Wang, Alex Gladkov, Kai Sheng Tai, Zechun Liu, Abdelrahman Elogeel, Tarek Hefny, Yangyang Shi, Vikas Chandra, Ahmed Aly, Anuj Kumar, Raghuraman Krishnamoorthi, and Adithya Sagar
I am looking for a postdoc to lead projects related to this collaboration, on scaling laws, emergence and interpretability in pre- and post-training & inference/reasoning, in multimodal foundation models (language, time series, tabular data etc). HPC experience is a plus.
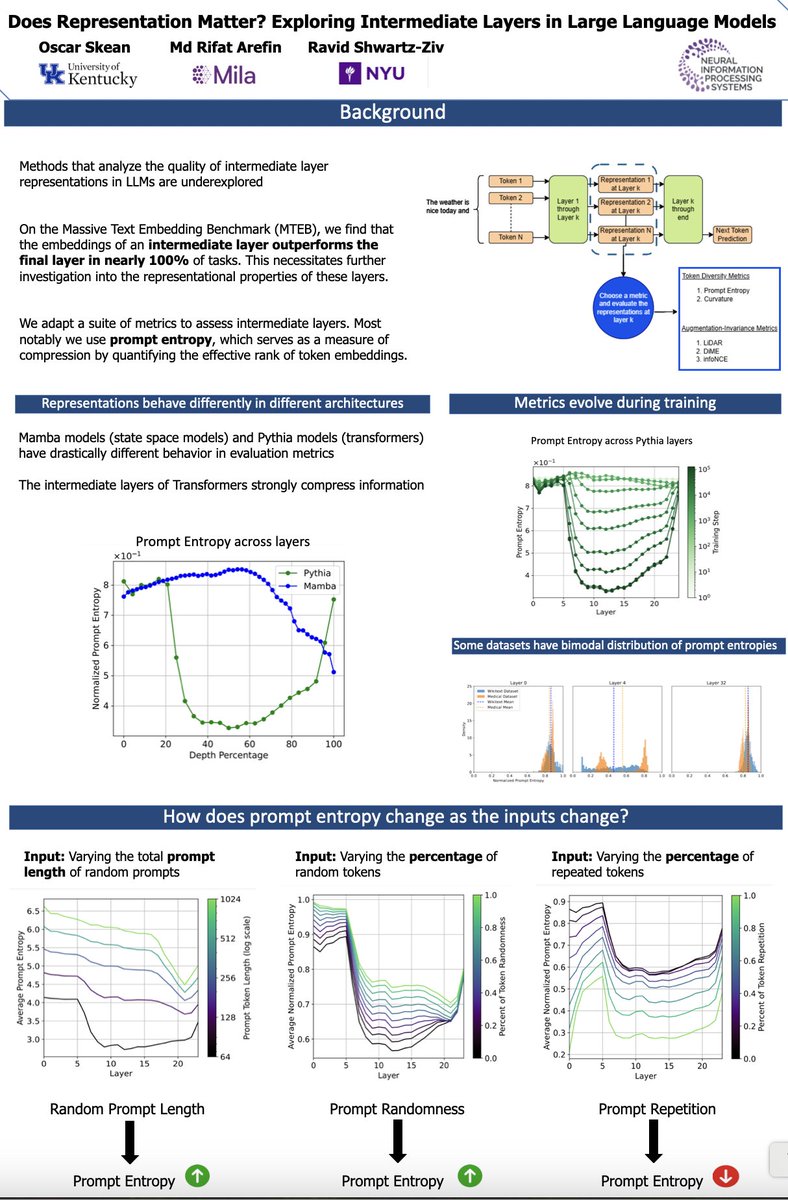
If you're at ICML, come tomorrow (Tuesday) to Oscar's talk, where he will present our paper "Layer by layer: Uncovering hidden representations in language models" at 10am (West Ballroom D) and for the poster session at 11am (East Exhibition Hall A-B #E-2607).
Interested in representation in intermediate layers of LLMs? What is a good representation, and how can it be measured? Visit Oscar's poster on "Does Representation Matter? Exploring Intermediate Layers in Large Language Models"
Mila's annual supervision request process opens on October 15 to receive MSc and PhD applications for Fall 2025 admission! Join our community! More information here https://t.co/r01eLcXtZw
Excited to share our work "Unsupervised Concept Discovery Mitigates Spurious Correlations" at #ICML2024
Come see our poster today, July 25th at 1h30-3pm.
Paper: https://t.co/cBHRuyxKnv
Poster: https://t.co/HPGIkC5kql
Code: https://t.co/tu4d4aT5a5
@Mila_Quebec
🚨 Open-source AI community - stop building everything from scratch, let's build on each other's (and your own) work over time - continually, as we should! Don't waste previoius compute and human effort!
See https://t.co/jugB0DW4KZ - simple & useful tips on how to just keep training foundaiton models on new data without forgetting or performance degradations w.r.t. usual large-scale training!
Kudos to our amazing team, @kgupta24@benjamintherien@ai_phd@MatsRichter@QuentinAnthon15@TLesort@ebelilov !
Join our Scaling, Alignment & Open-Source AI workshop Fri, Dec 15 in New Orleans or remotely https://t.co/3lsCLcVBqV!
Hear Nick Bostrom, Yoshua Bengio (TBA) @ylecun@tegmark@percyliang@juliabossmann@JJitsev@ethanCaballero@irinarish and others discuss the Open Source and the Future of AI, and engage in discussions on new scaling laws, "emergent" behaviors, continued pretraining, multimodal alignment, compression & fast inference, time-series foundation models and open generalist agents, and recent supercomputing efforts (Trillion Parameter Consortium) and more! Join us for the Open Source AI party sponsored by @cerebras, @togethercompute and @UMontreal's CERC-AAI Lab led by @irinarish!
Great job, @togethercompute and INCITE (@UMontreal@AiEleuther@laion_ai ) teams and all the collaborators! It's awesome to see the RPI 7B (RedPajama-INCITE) model outperform ALL the best open models of same size - Llama-7B, Falcon-7B, and MPT-7B on HELM benchmark!
We are glad to announce that our paper: "Challenging Common Assumptions about Catastrophic Forgetting" co-authored with @ostap__alex, @__z__9, @rarefin15, @prlz77 , @lcharlin , @irinarish has been accepted to @Collas2023.
(arXiv https://t.co/HHbczhnyCU)
[A thread (1/N)]