@bcantrill@GergelyOrosz I was under the impression that anything resembling tokenmaxxing (i.e., prizing quantity of output over everything else) had died out a few months ago…
Very interesting “unplugged” event with @GergelyOrosz, @bcantrill & @CompleteSkeptic. Can’t wait to watch the recording of it, hopefully its content will be deemed suitable for mass distribution 😅
Quick trip to San Francisco, trying to make the most of the city between @FireworksAI_HQ’s Forge conference yesterday and @Pragmatic_Eng’s event tonight.
“Some developers struggled to let go of writing code. But that was only the beginning—now they have to accept that they won’t even be reading the code agents write.” — @dhh
Kimi K3 debuts at #3 on DeepSWE.
It's the first open-weights model that delivers frontier-level performance, achieving results similar to Claude Fable and GPT-5.6 Sol.
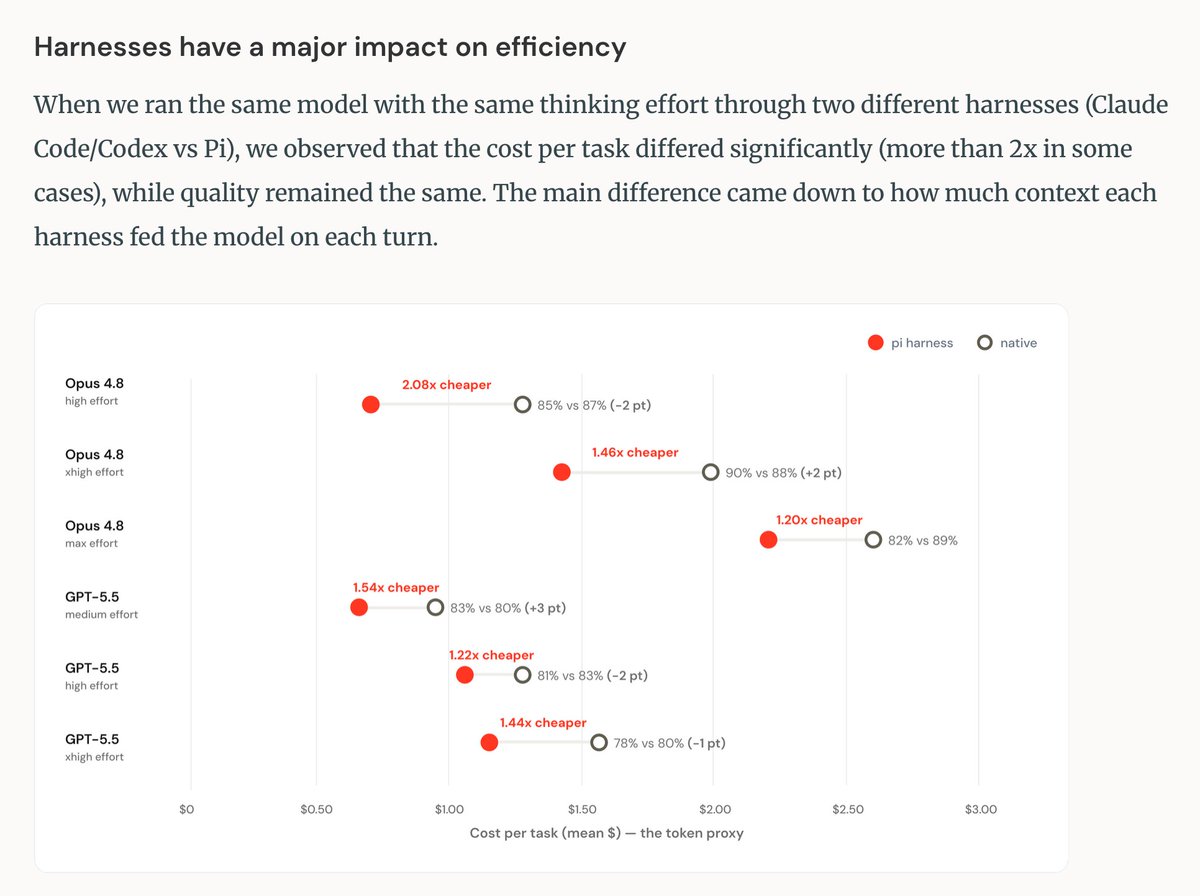
At 11k employees, our AI costs are going up. Which model & harness should we use to lower cost but also retain great quality?
We didn't want to blindly trust public benchmarks. So we ran a comprehensive evaluation on our tasks, code base, infra. It's been produced by more than 3,000 software engineers, spans 3 hyperscalar clouds and many languages and tasks.
The results are surprising. We find that for the SAME mdoel, the choice of harness can significantly save costs (~2x). We also find that GLM 5.2 performs extremely well. We run Omnigent in front of these and can easily multiplex different harnesses and models for different tasks.
Check it out:
https://t.co/hiLtLZn1cK
For two years, thousands of people have relied on our AI platform every day.
Today, we're introducing it to the world: Meet Forra, the enterprise AI platform by Mirego. Fortified for trust. Designed for rapid adoption.⚡️
🔗https://t.co/POiuZfWTpp