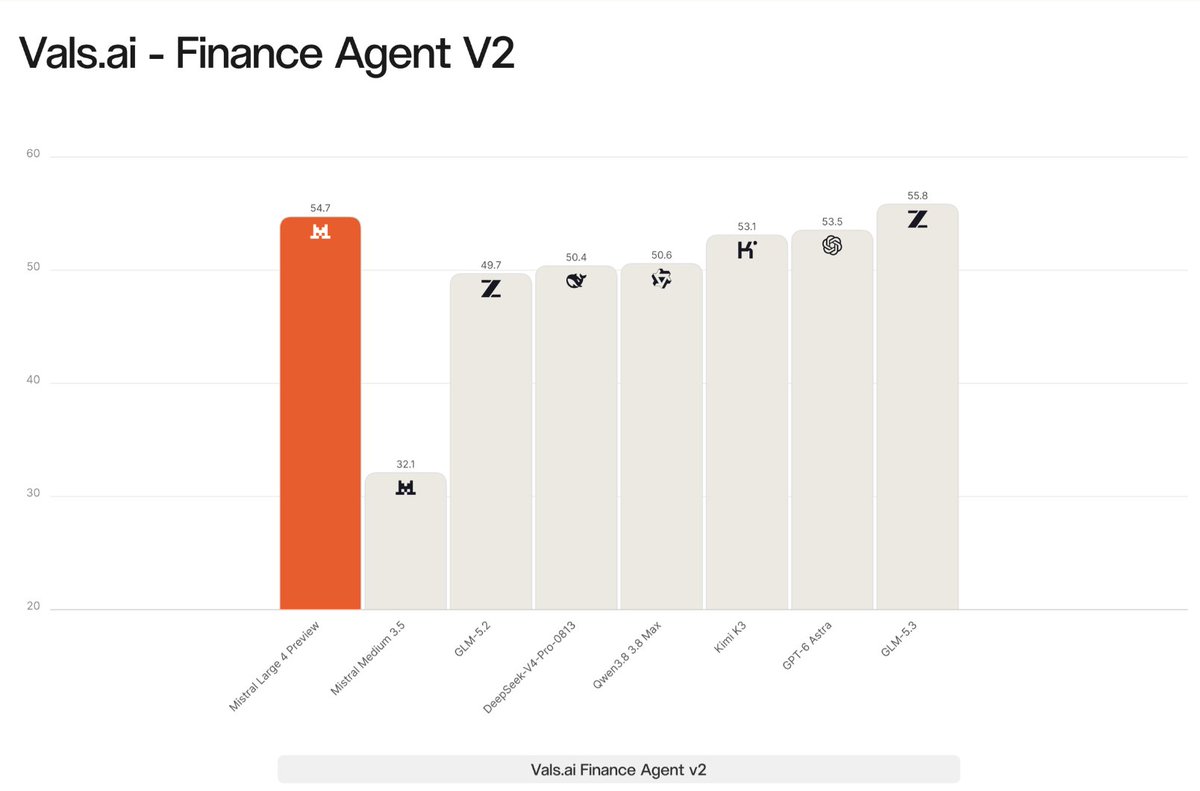
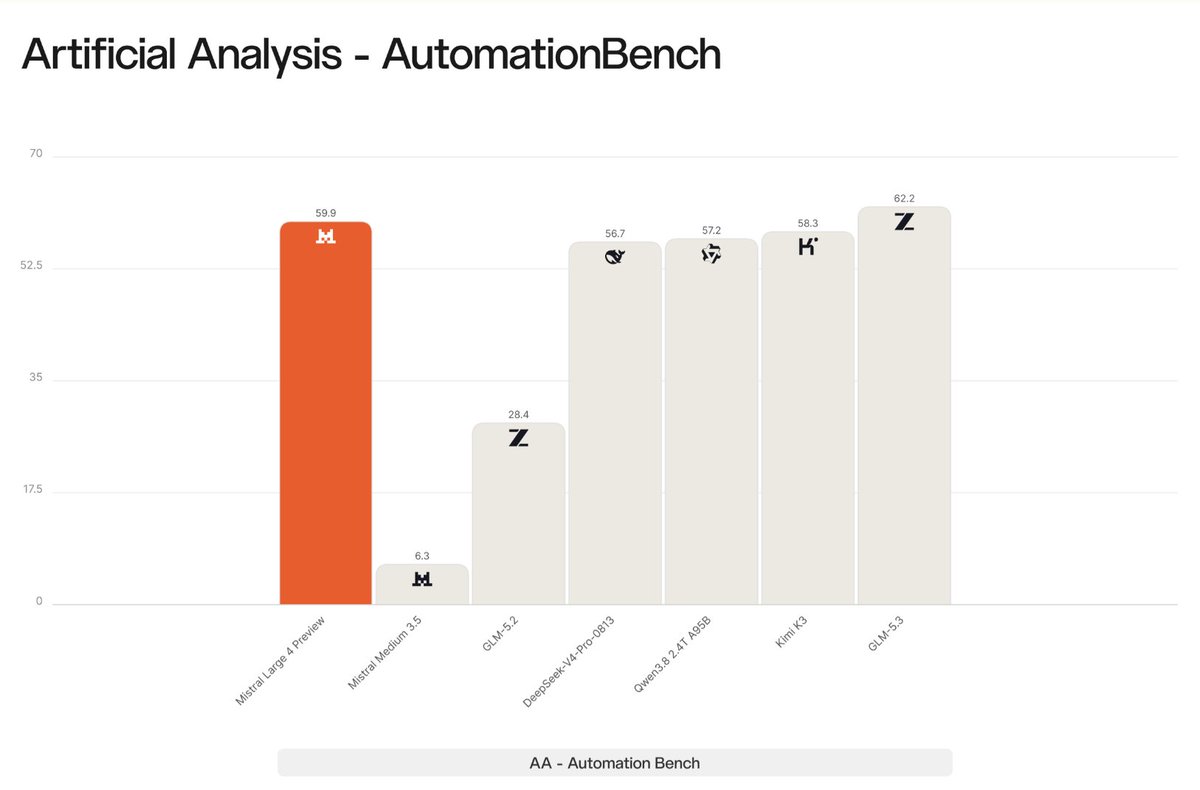
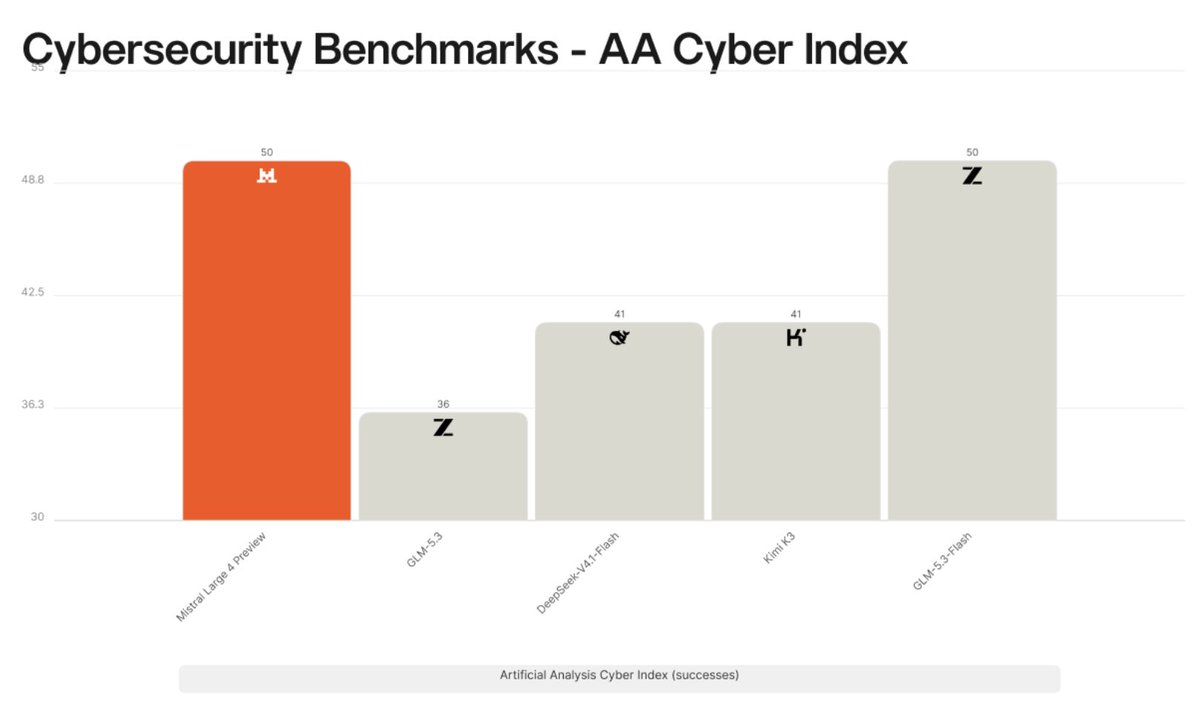
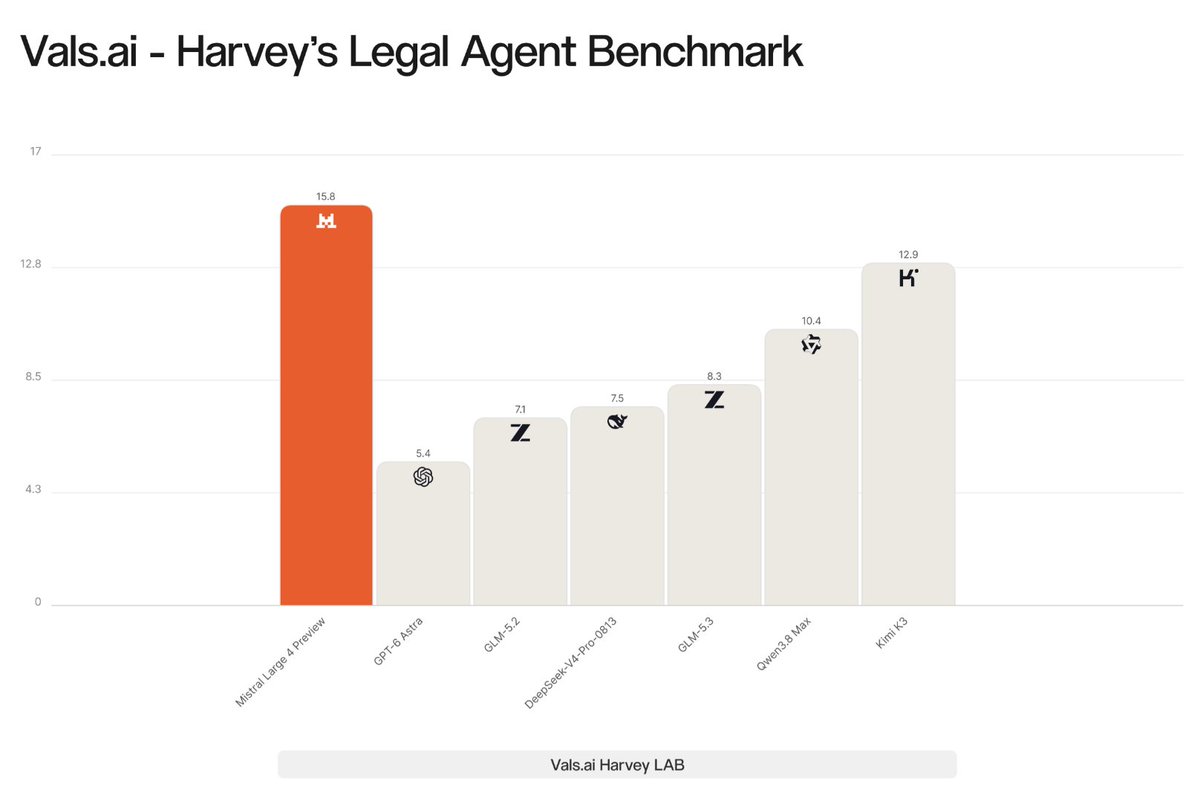
Today, we are launching a preview of our new model, Mistral Large 4 (ML4), aka le Chonk 🐈.
ML4 is a 1T-parameter model with 49B active parameters, trained natively with multimodal capabilities.
It is at the frontier of open models, and by far the strongest open-weight model from the US or Europe.
The RL run behind this preview is still in flight and shows no sign of saturation -- we will release a final version before the end of the month along with the weights of the model.
🧵
1/n
Meet Mistral Large 4, aka Le Chonk.
• 1T parameters, natively multimodal. 49B active.
It is the best open weights model from US or Europe on aggregated benchmarks.
• State-of-the-art on critical workloads, including cyber defense, manufacturing and finance and it surpasses closed frontier models on visual grounding.
• Forged in Europe end-to-end and is deployable from Europe via our own Mistral Cloud infrastructure.
• Available to all via API today. Working with cybersecurity partners privately.
Open weights release end of October.
🎉 The Sovereign Tech Fund is investing €230K to strengthen Nixpkgs and the global #OpenSource supply chain.
Focus areas:
• CI performance
• Reproducible builds
• Faster Nix
• Unprivileged daemon
Early result: https://t.co/eynSOY8X7g
#NixOS as critical infrastructure.
Next step, installing #Linux on systems. Digital sovereignty doesn't stop at the office suite; the operating system is still a dependency underneath. What distributions are primed to be the #foundation once the office suite is sorted? #openSUSE#Fedora#Debian#Ubuntu
🎉 Introducing 𝙾𝚙𝚎𝚗𝙳𝚘𝚝𝚜
Self-hostable, always-on AI coworkers that works with ANY agent harness.
Includes:
- Computer use: browser, terminal & files
- Bring agents to Slack, Teams etc
- Spaces and Pages for projects
- Voice calls
- Web and Mobile
Repo → https://t.co/j6URR886Dt
Powered by @CopilotKit and AG-UI.
Clone this template and customize it however you want. Enterprise-ready.
People underappreciate the privacy aspect of local AI models and mostly talk about price.
There are things I don't ever want to expose to any cloud API. Ever. No matter its privacy policy says.
Run models locally if you care about your sensitive data, there is no other option!
The narrative of "is it worth spending X amount of $ to run local models" should change to "is it important enough that my data stays for my eyes only?"
Unfortunately, this is a hard pass ☹️
Bonsai 2 27B couldn't properly complete a not-so-difficult HTML task. It might be decent for simple stuff, but for anything with some complexity in it, it's a no-go.
Sorry... I really hoped for a different outcome.
GLM-5.3-Flash vs DeepSeek-V4.1-Flash
I ran the exact same tasks on both on an agent harness I'm building:
- Code review
- Mobile review
- Improvement plan
Then I verified every claim from each model against the code. Who's the winner?
▶️ On code review, GLM 5.3 Flash won.
GLM finished in 27 minutes and worked by reading 35 file reads, and performed 27 searches.
DeepSeek took 45 minuted and worked by running 55 shell commands.
DeepSeek raised 23 issues, GLM raised 10.
Both were right about roughly 60% of the findings. So DeepSeek found more real problems, and more fake ones.
That's not what decided it though.
GLM's biggest finding was correct. DeepSeek's biggest finding was wrong, and that is why GLM 5.3 Flash won on code review.
▶️ On mobile review, DS4.1F won.
It found a bug that makes the composer unusable the second messages start queuing. GLM had that exact component on screen, asked the wrong question about it, and moved on.
That said, my prompt explicitly instructed both models that look and feel were super important. GLM viewed 14 screenshots. DeepSeek viewed zero.
▶️ What about the improvement plan? This one goes to GLM 5.3 Flash.
GLM was broader and better prioritized. It also came back with 33 improvements, each one sized and properly prioritized.
DeepSeek v4.1 Flash came back with 14. Deeper on a couple of them, but it spent almost nothing on UI and performance. Two of the four things I asked for.
Different instincts too. GLM went hunting for things already half built and never wired up. DeepSeek went narrow and quantitative and argued that I should first build a way to measure improvement before acting on any of its own ideas.
On this task, both were accurate. I verified every claim.
So which is better?
🥇 GLM 5.3 Flash takes it 2-1. Better calibrated, roughly 1.3-1.7x faster, and it knows when its own tooling is the problem.
🥈DeepSeek v4.1 Flash feels "sharper" and the one most likely to be confidently wrong about what it just measured.
For me GLM 5.3 Flash is the one I run daily.
🚀 Meet Qwen3.8-Omni-Flash, Qwen's first omni-modal model built around agentic capabilities!
Native audio-video understanding, reasoning, and tool use come together in one model: understand the content, plan the task, execute with tools, and deliver the result.
Highlights: 🥳
- Audio-video intelligence that gets things done: jointly reason over what's seen and heard, and orchestrate tools across long workflows to auto-edit vlogs, translate short videos, and turn movies into recaps.
- A major leap: approaching Gemini 3.8 Flash in audio-video capabilities; +19.5 points on average in agent performance across WildClawBench-MM & UniClawBench.
- 1M-token context with agentic perception: actively explore long videos and locate key moments with higher accuracy, using 51.8% fewer tokens than static understanding on OmniVideoBench.
Video input costs are reduced by about 89% compared with Qwen3.5-Omni-Plus, making long-form audio-video understanding and agentic workflows more affordable than ever.
To help you build apps around Omni, we're also open-sourcing Qwen-MM-Plugins and Qwen-Live Harness! 🛠️
We can't wait to see what you build with Qwen3.8-Omni-Flash! 👀
- Blog: https://t.co/oM9V1TkqYF
- Qwencloud: https://t.co/Cc2I8ELAnD
- Qwen Studio: https://t.co/V7RmqMaVNZ
- API: https://t.co/lNE7fH5YUt
- Qwen-MM-Plugins: https://t.co/SnM27dDP3d
- Qwen-Live Harness: coming soon
https://t.co/iVYlGjIbdy
We are aware of a claim alleging unauthorized access to our systems. Following a thorough investigation, we have found no evidence to support this claim and can confirm that our systems have not been compromised.
Okay, THIS is a ridiculous Hermes use case. 🔥
@4k_isn used Hermes Agent + DeepSeek V4.1 Flash to help optimize Resident Evil 7’s graphics files, shrinking the textures from ~20GB to ~8GB.
The result?
Resident Evil 7 running smoothly on a midrange Android phone.
Hermes users are getting out of control in the best possible way. 🙌🔥
1/ This was really cool.
For the first time, an LLM ran entirely on the blockchain. Weights, activations, attention, tokens all loaded and calculated onchain in a general purpose ledger. Every step in the process was a standard SVM transaction.
Today, we are announcing a partnership with @mozilla to bring privacy, control and choice to people using AI to browse online. 🦊🐈
https://t.co/Bsd6N4jNdV