Toute l'expérience passe par un assistant qui t'aide à composer / trouver le thé qu'il te faut. On fait pas mal d'expériences sur l'UX autour des agents pour le e-commerce personnalisé.
We cut through the mystery around interpretability in training.
A single, mathematically rigorous framework transforms model internals into training feedback and works across domains, problems, and modalities.
We call this *mechanistic shaping*, and we’ve used it to mitigate reward hacking, remove shortcuts in chest x-rays, and reduce sycophancy and harmfulness. We believe this is a big step forward for technical alignment.
But it carries a known risk: training against a model’s internals can make it harder to monitor. We explore both the technique and this concern below. 🧵
🚨 C'est officiel, le parti de David Lisnard devient le 1er parti de France
Avec près de 113 000 adhérents, Nouvelle Énergie a déjà dépassé Les Républicains et passe devant le RN ce matin. Aucun parti ne reste devant.
9 places gagnées depuis début septembre 📈🇫🇷
J’ai rejoint @davidlisnard en mars dernier. C’était juste avant qu’il claque la porte des Républicains, mais au fond de moi, je savais déjà qu’il allait se passer quelque chose.
Je sentais chez cet homme une force rare, une vraie colonne vertébrale, un amour sincère pour la France, et surtout ce courage de rompre avec le prêt-à-penser. Ras-le-bol de ce social-étatisme mou qui nous étouffe à petit feu depuis quarante ans.
Rejoindre Lisnard, c’est simplement choisir la liberté. C’est porter un projet économique sérieux, exigeant, qui tire chacun vers le haut au lieu d’égaliser par le bas. Un projet qui redonne du sens à l'impôt : que notre argent serve enfin aux missions fondamentales de l'État : nous protéger, nous éduquer, nous élever, et rien d'autre.
Hier soir sur @BFMTV, comme sur @CNEWS il y a quelques semaines, on a encore vu la même chose, dès qu'il a du temps d'antenne, les adhésions s'emballent. Pourquoi ? Parce que dès qu'on prend dix minutes pour l'écouter et lire son programme, l'évidence s'impose d'elle-même.
I've always believed that intelligence should come from simple, general building blocks that learn their own abstractions directly from raw data; in other words, the bitter lesson. I think we're finally seeing a real step towards AI that can learn from all data.
Language modeling on raw bytes is a microcosm of this ideal, and to me it's a central problem in AI: if we can't build LLMs that learn end-to-end from bytes, how will we handle the rest of the world's data that we understand even less?
Last year we introduced hierarchical networks (H-Nets) as a first step. Our new version finds up to 3-5x efficiency gains in controlled scaling law experiments, and at larger scale matches an open-source model trained on 11T tokens with ~10x less data and compute. The posts below walk through what we found and why we think it works.
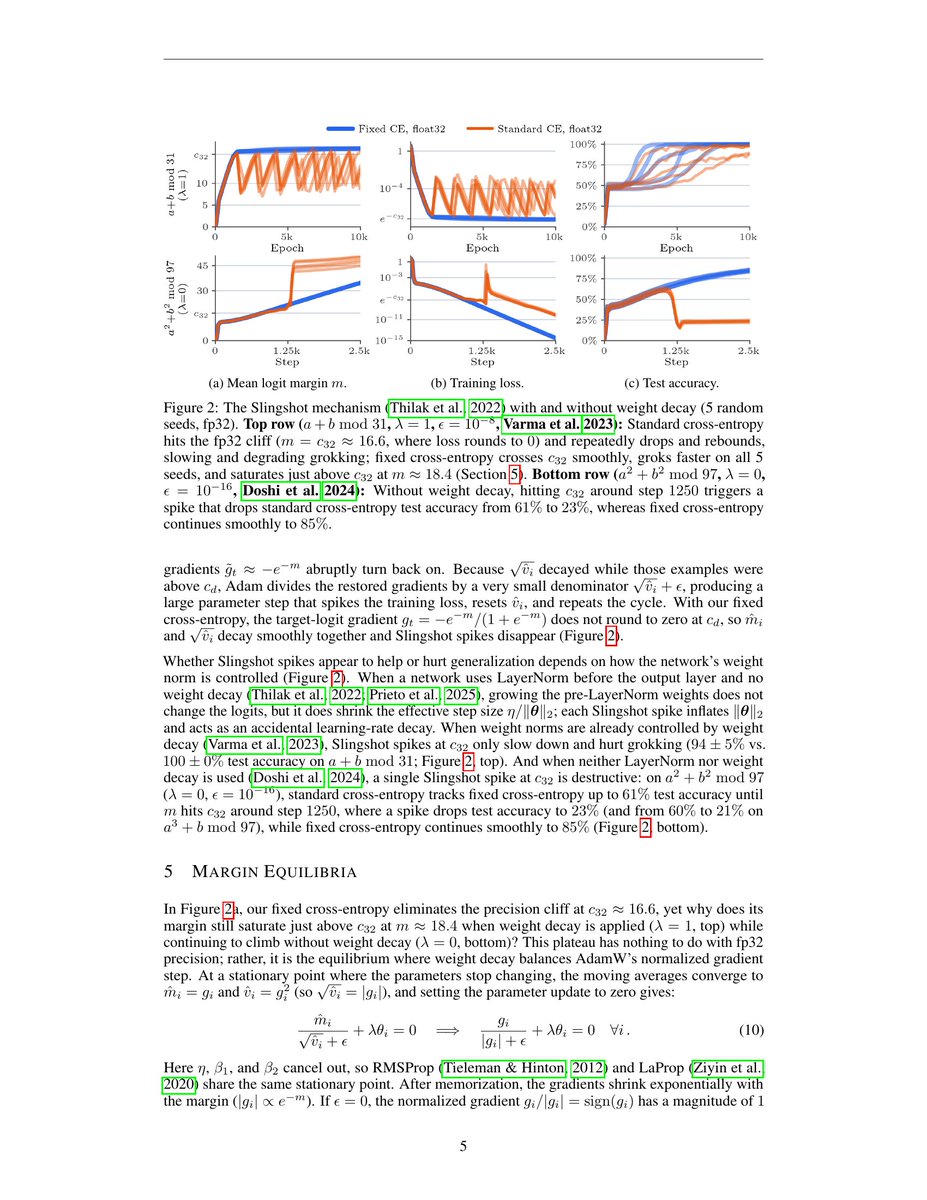
Hi all, I have a new result I'm excited to share. It turns out that *all existing implementations* of softmax and cross-entropy (that's JAX, PyTorch, textbooks, etc) have a subtle bug --- two bugs, actually. A simple rewrite fixes both, and eliminates "slingshots" when grokking:
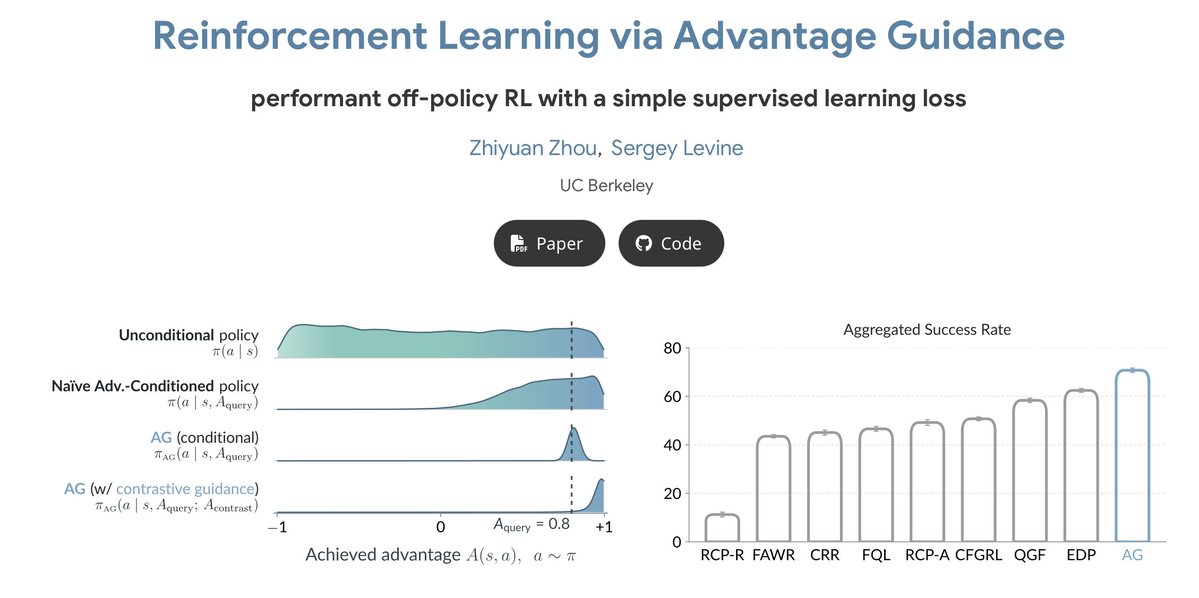
Last year I trained the advantage-conditioned VLA for π*0.6 during my internship @physical_int. Now, I have a much improved recipe.
Introducing ✨Advantage Guidance✨, a performant RL method with stable advantage-conditioned supervised training and contrastive guidance sampling
I think the last month might have been the biggest month in (zeroth-order) optimization history.
In the 10 days since we released the Noise speedrun, the time to pretrain a transformer went from 1.76 hours to 1.6 seconds, a 4,000x (!!!) speedup. Dust itself was up to 10,000x more compute-efficient than the previous state-of-the-art.
Not only can we pretrain a transformer without backprop, it's much more efficient than anyone would've expected. Search fking works!
Now, scaling is the biggest open question. Some of the tricks that brought the time down to 1.6 seconds will simply not scale. To discard those, we'll be scaling the dataset every time it gets overfit, starting with 30M tokens instead of 10M.
Huge thanks to @jayden_teoh_, @spicey_lemonade, @RobertTLange, @EmanueleRodola, @ChunyuanDeng, @LuochengHuman, @Alaxarr, @pavleculafic, @IsaacYong13, Euraba and areu01or00 (GitHub), for the contributions. And @cs_serdar for gracefully maintaining the speedrun and @bishmdl76 for helping out.
Expect a lot more from us over the coming weeks.
Inacceptable aveu d’impuissance et renversement total des principes.
Les commerçants paient les réparations, paient des impôts pour que l’Etat assure leur sécurité, et devraient payer une troisième fois pour une sécurité privée.
Incapable de remplir cette mission première, l’Etat leur demande de payer des entreprises de sécurité. Des coûts en plus et donc des revenus en moins, dans une période difficile. Et toujours la même injustice : les premières victimes seront les plus modestes, qui ne peuvent se payer ces protections.
Avec @nouv_energie, restaurons vite l’Etat, au service de tous, et surtout de ceux qui en ont le plus besoin.
We found a way to scale humanoid control that reduces GPU-hours by more than 1000×.
Across 129,514 motions, SuperMimic surpasses the state of the art (128 GPUs, 7 days) with 1 GPU in 3 hours.
Project: https://t.co/6gc9WKm9qY
Demo: https://t.co/OHRvx5ogQY
Speech can survive being flipped backward every twenty milliseconds.
The same speech in backward pieces of 200 then 100 then 50 then 20 milliseconds.
The original comes last.
When do the words become clear?
A listening demo from @OrukLabs.