BREAKING: Mercor Raises $750M at $20 BILLION Valuation
I sat down w/ Co-Founder & CEO Brendan Foody (@BrendanFoody) to discuss the explosive growth of one of AI's fastest-growing companies & his ambition to build a trillion-dollar business.
Founded in 2023 by college dropouts, @Mercor is building the human intelligence infrastructure behind frontier AI models.
Mercor by the Numbers:
› $750M Series D, backed by Nvidia, Benchmark, General Catalyst, Funds managed by affiliates of Apollo, Salesforce & others
› $20B valuation
› 5X+ growth on a mid-nine-figure base since last September
› 5M+ experts in its network
› $5M+ in daily expert payouts, up from $1M annually just 2 years ago
› 7M+ AI interviews conducted
Brendan's thesis: Every Fortune 500 company will eventually operate like an AI lab, training its own models on proprietary data, workflows, and expertise.
We discuss Mercor's expansion into enterprise AI, its acquisition of Deeptune, reinforcement learning environments, why AI training data is still undervalued, competition with Scale AI, and how companies like Harvey are building proprietary AI capabilities.
Plus, why Brendan and his co-founders have turned down opportunities to walk away with significant cash, Mercor's IPO ambitions, and what it takes to build a category-defining company.
𝐓𝐈𝐌𝐄𝐒𝐓𝐀𝐌𝐏𝐒
(00:00) Brendan Foody, Co-Founder & CEO Mercor
(01:00) Mercor's Path to a $1T Company
(02:22) Mercor's 3 Products
(04:05) $5M a Day in Expert Payouts on Stripe Connect
(05:40) Why Mercor Is Not a Marketplace
(08:51) Is Human Data a Durable Category
(12:20) How Mercor Finds and Evaluates Experts
(15:45) Holding Category Leadership With a Founding Team in Their Early 20s
(18:00) Chips on the Shoulder and Avoiding Mimetic Competition
(28:25) Why Mercor Acquired Deeptune
(31:22) Turning Down Acquisition Offers
(34:40) Harvey, LAB and Why the Model Is the Product
(41:30) Why Data Is Mispriced in the AI Stack
(43:40) Every Fortune 500 Becomes a Neolab
(49:55) IPO Timeline and the Next 12 Months
Mercor has raised a $750 million Series D at a $20 billion valuation to scale our mission of organizing human intelligence for the entire economy.
Every company now needs what we built for the frontier AI labs. Over the next five years, more money will be spent applying AI to real work than building new models, and every company will need evals and post-training built on how its own people work.
Thank you to our 5+ million experts and the customers who have built Mercor with us, and to our investors, including @benchmark, @felicis, @fundomo, funds managed by affiliates of Apollo, G Squared, @generalcatalyst, @GladeBrookCap, @nvidia, @salesforce, @SapphireVC, @StepStoneVC, XTX Ventures, and @Zoom.
Thank you to our team of time travelers who turn our ambitions into reality. And to those who want to build with us, we’re hiring.
We raised our $750 million Series D at a $20 billion valuation from @benchmark, @generalcatalyst, @nvidia, @salesforce, and @zoom.
@mercor scaled from $1M to $3B in run-rate revenue in 27 months, the fastest in history to $3B.
For 2 years, we've organized human intelligence to build evals and training data for every frontier lab.
The labs are the leading indicator for AI startups, then the Fortune 500.
Our growth has accelerated over the past 6 months as enterprises start evaluating and training their own models. For many, owning their intelligence is existential.
DoorDash expects to need more Dashers as autonomous delivery scales.
On the latest episode of The Frontier, @andyfang discusses how @DoorDash is applying AI across its business, its investments in robotics and autonomous delivery, and what happens when AI agents can take action in the physical world.
We also got into why frontier models still struggle with real enterprise workflows, even when they perform well on benchmarks.
Watch the full conversation ⬇️
We're proud to have collaborated on a new benchmark built by @GoogleAI: Physical-Engineering's Last Exam (PLE).
Physical engineers design the skyscrapers, power grids, and chip fabs we rely on, yet no existing benchmark tested whether AI agents could do that work end to end.
Together with Google and practicing engineers, we built 85 long-horizon tasks across mechanical, electrical, civil, and structural engineering. On the private test set, all frontier models score below 50%:
1. Claude Opus 5.5: 48.3%
2. GPT 6 Astra: 45.8%
3. Claude Sonnet 5.5: 43.5%
4. Gemini 4 Argon: 40.6%
5. Claude Opus 5: 40.0%
On the tasks we co-authored, the top agent satisfied 91% of individual constraints, but only 41.3% of its deliverable items passed every hard safety check.
Learning how AI fails at physical engineering can help us improve future models and build a safer world.
This benchmark is also an open competition. Bring your own agent setup and submit it for evaluation on our private test set at https://t.co/nOTWOUaV5v
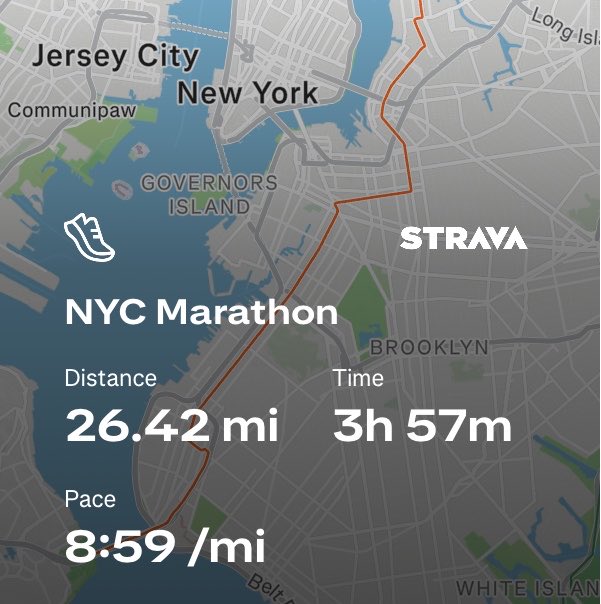
first marathon in the books!
truly the best day of the year in the best city on earth & sub-4 was the cherry on top
hardest thing I’ve ever done but nothing quite like having the most electric (and deceitful) crowd at your back to power you through
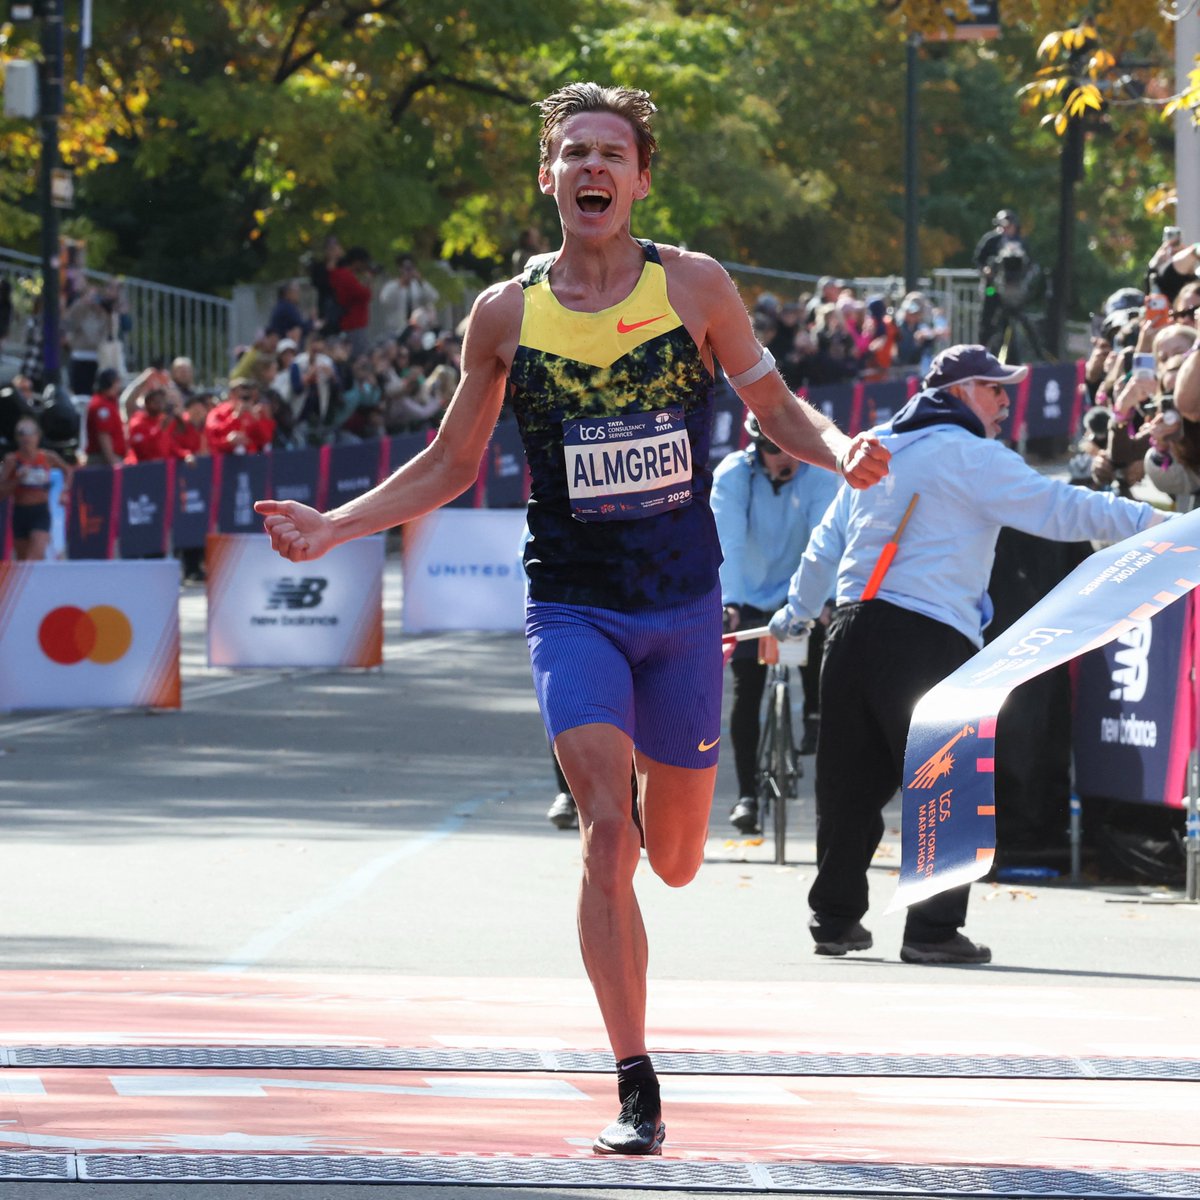
ANDREAS WHAT HAVE YOU DONE? 🤯
🇸🇪’s Andreas Almgren lives up to the hype with a dream marathon debut, storming to victory at the @nycmarathon in 2:06:01 🫨
It’s the year 2030 and your entire life is via rollups. Your home is secured by Thrive Holdings, HOA is operated by Long Lake, renew insurance via Sequence, and your local tennis court reservation system is run by Beacon. Your accountant is employed at Crete and your small business handles IT on Titan.
Founded by three 22-year-olds in 2023, @mercor crossed $2B ARR in June, only 4 months after hitting $1B.
Today, millions of experts on the platform bring their knowledge of medicine, law, engineering, and beyond to frontier AI - helping models take on increasingly complex and consequential work in the real world.
Mercor's engineers move at extraordinary speed.
They give Devin long-running tasks before bed, during meetings, or on their way to the gym. They come back to tested features and PRs ready to merge.