💥 DeepSeek-V4-Flash + StateM just CRUSHED Fable 5 for $15.20 vs. $552.67! 💥
That’s a ~36x cost reduction while taking the crown on Terminal-Bench 2.1! 📈
Here’s the breakdown on why this changes everything:
🔥 It’s Not Just Model Scaling
Scaling model size alone won't solve Agent capabilities. Harness Scaling is the new Meta—enter StateM, a state-machine explicit control layer that drives massive performance gains during training.
⚠️ 3 Massive Pain Points with Current AI Agents:
1️⃣ Unenforced Plans: Tools like Codex or Claude Code rely on soft checklists—no hard enforcement or easy human intervention.
2️⃣ No Memory / Experience: Lack of prior workflow context causes planning and self-verification to fail.
3️⃣ Coarse Context Management: Zero granular control over context window execution.
💡 The StateM Solution:
Built on YAML config + CLI execution. It provides explicit state-machine control, auto-halts on failure, and makes workflow fully human-readable and steerable in real time.
🏆 The Benchmark Proof (Terminal-Bench 2.1):
Developers used GPT-5.5 xhigh + Codex to build a generalizable runbook (human sets direction, Agent iterates), then ported it to DeepSeek-V4-Flash for <$38.
Final Result: DeepSeek-V4-Flash + StateM hit the top spot for $15.20 vs Fable 5’s $552.67. The same runbook even supercharged GPT-5.5/5.6, outperforming much costlier Ultra setups!
💡 Takeaway: Harnessing is the ultimate leverage for AI Agent deployment. Combine a low-cost model with a rigid control layer and watch ROI skyrocket.
https://t.co/ykIvAaTyCD
What are your thoughts on Harness Scaling vs Model Scaling? 👇
#DeepSeek #AIAgents #StateM #TerminalBench #DeepSeekHarness #Fable5 #LLM #AIEngineering #BuildInPublic #AIResearch
StateM: harness scaling for reliable agents
A runtime that gives agents durable state, checked transitions, and recoverable runbooks. On Terminal-Bench 2.1, it lifts GPT-5.5 to 92.1% and DeepSeek-V4-Flash to 88.1% for under $15.
Is model scaling the only source of agent improvement?
We @henryqin1997@YaxinLu1997@VITAGroupUT@VictorKaiWang1 are glad to share our work: We reach 95.3% Raw Accuracy, or a $15 Frontier Run (88.8% with DeepSeek-v4-Flash, matching GPT-5.6 Sol Max), on Terminal-Bench 2.1 via Harness Scaling.
Human effort -> Non scalable ❌
Agent direction? Local optimization ❌
Human direction + agent action = better workflow control✅
StateM:
1. Open-source model + StateM -> Close-source frontier, everyone can try!
2. Training free, significantly improve frontier agents.
3. Zero-transfer-cost on same family of agents. [1/8]🧵
📄https://t.co/GjM1VOzWUN
🌐 https://t.co/KapEB3kjXr
@TencentHunyuan ASTONISHING! Parametric Memory during Inference. 😃I have just read the work MemoryOS released last year, which focuses on token (input) memory. This work just broader the scope of another implicit memory research line, PARAMETRIC Memory.😆 Insane!
One static model does not fit all😭
We just dropped our latest work: Functional Neural Memory. Instead of static models, we generate custom "parameters" for every single input.
✅Prompt your model anytime
✅Instant personalization
✅Better instruction following
✅Flexible & dynamic memory (w/o memory bank✌️)
(🧵1/6)
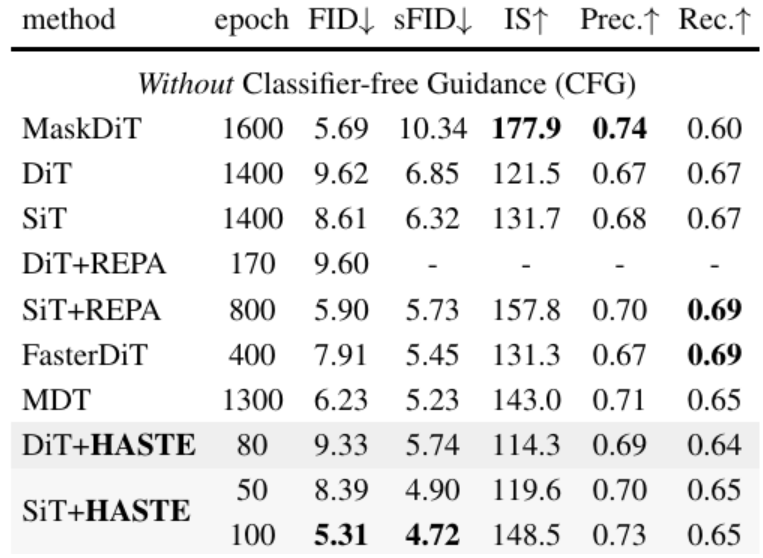
Representation Alignment (REPA) is NOT ALWAYS helpful for diffusion training!🤷
Sharing latest work w/ @HPCAILab and @VITAGroupUT: "REPA Works Until It Doesn't: Early-Stopped, Holistic Alignment Supercharges Diffusion Training".
Acceleration up to 28x w/o performance drop.(🧵1/7)
Generating ~200 million parameters in just minutes! 🥳
Excited to share our work with @MTDovent , @heisejiasuo96 , and @YangYou1991: 'Recurrent Diffusion for Large-Scale Parameter Generation' (RPG for short).
Example: Obtain customized models using prompts (see below). (🧵1/8)
Generating ~200 million parameters in just minutes! 🥳
Excited to share our work with @MTDovent , @heisejiasuo96 , and @YangYou1991: 'Recurrent Diffusion for Large-Scale Parameter Generation' (RPG for short).
Example: Obtain customized models using prompts (see below). (🧵1/8)
❓ How much optimization states memory do we need for LLM training ? 🧐Almost zero.
📢 Introducing APOLLO! 🚀 A revolutionary optimizer with SGD-like memory cost, yet AdamW-level performance (or better!).
📜 Paper: https://t.co/jIzU6nyXAy
🔗 GitHub: https://t.co/SKxEC9ZdXp
Today we release R-MeeTo (Re-training Merged Token) the first Token Merging method for Mamba.🥳Faster Mamba can be achieved in Minutes-Level with minimal degradation of performance.
PDF:https://t.co/oXLu8ViQ9N
Home:https://t.co/SAwPxGVknc
Modification: key knowledge is consist of general and specific knowledge. General Knowledge includes the common partterns shared among tokens, and Specific Knowledge indicates the specific partterns in particular tokens. They look like this in Mamba: