“DeepSeek-V4.1-Flash: Pushing the Limits of KV Cache Compression”
With the rise in popularity of long-horizon agents, prefill compute and KV cache storage are becoming major efficiency bottlenecks as context lengths grow.
DeepSeek-V4.1-Flash attacks this at the architecture level. Its new Causal Encoder-Decoder architecture computes the lower half of the network as an encoder, then projects decoder global KV directly from the encoder state, cutting prefill complexity from roughly O(NL) to O(NL/2).
On top of that, their new CSA2 compresses along the layer dimension by sharing global KV and indexer K across layers, while Reindex and Reuse modes either recompute or reuse sparse Top-K selections. A hierarchical sparse indexer then restricts deeper layers to a shared candidate pool instead of rescoring the full context.
They also push storage further with FP4 main KV caching and SWA Bounded Replay, which avoids persistently storing sliding-window KV.
Together, these reduce global KV cache to 890 bytes/token, ~4x smaller than V4-Flash, and persistent KV by ~8x, while supporting 1M token contexts with much stronger overall performance.
https://t.co/86cz5urlzZ
Show this video to all the GPT Astra haters
Personally, I can already see medical students in universities using this model to study the human body
Or am I wrong?
I got Omarchy running on my iPad, Pixel, and M4 Max MacBook Pro 🤯
It can basically run anywhere and is super responsive. The trick was that I set up a VM on AWS and can attach to the same computer on any device through Moonlight + Tailscale. Same files, same apps, same session.
I built software around it to adapt the desktop to different screen sizes, get keyboard shortcuts and inputs working correctly, and automate the AWS setup. Plus a web dashboard for starting, stopping, pairing devices, and tracking estimated costs.
Really love this idea: your device becomes a window into a computer you can take anywhere.
Still experimenting, but it’s working. DM or reply to this thread if you’re interested in trying it!
Thanks @dhh for creating this exciting OS.
@IndiaPostOffice@cpmgbihar@AshwiniVaishnaw@devusinh Every day I ask to deliver, but the postmaster makes excuses instead of handing over my crucial document. This false tracking update and constant delay is causing mental harassment. Please resolve this immediately.
@IndiaPostOffice@cpmgbihar@AshwiniVaishnaw Every day I ask to deliver, but the postmaster makes excuses instead of handing over my crucial document. This false tracking update and constant delay is causing mental harassment. Please resolve this immediately.
@IndiaPostOffice@cpmgbihar@AshwiniVaishnaw Every day I ask the postmaster to deliver, but the postmaster makes excuses instead of handing over my crucial document. This false tracking update and constant delay is causing mental harassment. Please resolve this immediately.
@delhivery@jagograhakjago@biharpolice@help_delhivery Aaj mera order ane wala tha 11 dino ke baad, pr apke delivery boy ne order mujhe nhi diya na call utha rha aur order delivered dikha rha hai. Ye kya baat huyi, ye kya gundagardi hai. Delivery guy number: +917949341302
@meesho_support Thank you for responding. This is a prepaid order and it has been more than a month with no solution. Please resolve this at the earliest and initiate my refund.
@Meesho_Official@meesho_support@jaagograhakjago
delivery agent ne call kiya pr aya nhi aur delivered dikhane laga app me. Ye kya scam h bhai??? Customer care v koi response nhi deta ek mahine se koi sunwaai nhi ho rha? kya kre ab?? court ka darwaja khatkhata pdega??
This has quietly been a miracle month in medicine.
In the last 5 weeks we’ve got news on:
- retatrutide, the triple agonist GLP-1 from Lilly, basically melting fat and body-wide inflammation at record levels
- RevMed’s new pancreatic cancer drug showing unprecedented abilities to extend life
- small trial of a one-and-done PCSK9 gene editing therapy for slashing LDL cholesterol
- Mayo’s AI-assisted radiology showing vastly improved cancer detection
- this new therapy for metastatic solid tumors
This stuff is at varying levels of evidence. Retatrutide is ~100% on its way, other stuff needs more clinical trial data. But put it together and we’re maybe on the verge of majorly reducing the mortality of heart disease and cancer, the two leading causes of death in America.
It's been *almost* a bit quiet around LLM architecture releases in the past two weeks 😅
Interesting tidbit is the parallel block design. Via the Cmd-A the tech report
"equivalent performance but significant improvement in throughput compared to the vanilla transformer block."
// Memory as a Model //
The paper augments any LLM with a separate trained memory model that stores, retrieves, and integrates facts on its behalf.
It decouples memory updates from base-model weight updates. It achieves continual-learning robustness without catastrophic forgetting, which is a property that RAG fails to deliver.
A vector store is a database with a learned encoder bolted on. MeMo is a learned subsystem with explicit interfaces. That distinction matters, as agents need to be able to ingest fresh knowledge weekly without retraining or vector-DB churn.
At its core, the position here is that memory in agents should be modular, learned, and gated, not a context-window hack.
Paper: https://t.co/iMrghPtxWW
Learn to build effective AI agents in our academy: https://t.co/LRnpZN7L4c
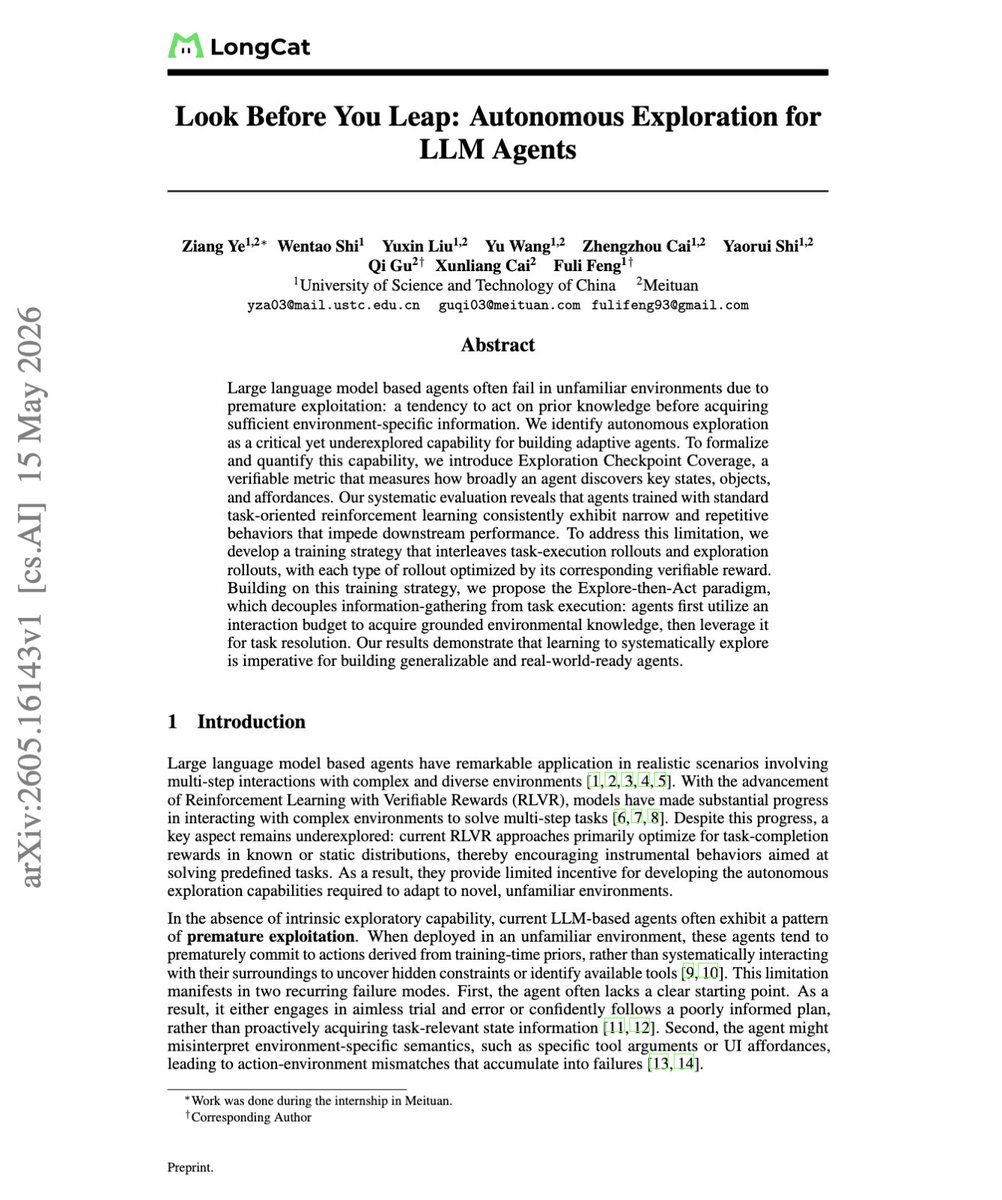
new longcat paper!
“Look Before You Leap”
LLM agents often fail because they act before they understand the environment.
So this paper introduces Exploration Checkpoint Coverage, a verifiable reward for discovering key states, objects, affordances, and constraints.
With interleaved GRPO, agents learn to explore first, summarize grounded environment knowledge, then act, making Explore-then-Act reliably improve task success instead of adding noisy context.
Introducing Gemini for Science — a collection of AI tools to help accelerate the scientific process. Gemini can already assist in solving complex problems, but our new @GoogleLabs prototypes can help streamline more daily scientific tasks, including:
📃 Staying on top of new papers
🧑💻 Transforming research goals into usable code
💡Generating new hypotheses
#GoogleIO
We’re bringing generative UI to everyone, free of charge, thanks to Google @Antigravity and the agentic coding capabilities of Gemini 3.5 Flash.
Search can build custom visual tools and simulations, tailored to your specific question, on the fly.
Under the hood, Search understands your query, designs the layout, decides what custom components to build, fans out to research and deploys the code to generate interactive visuals for you.
Whatever you want to understand, you get responses as unique as your questions.
#GoogleIO
Introducing our brand new, intelligent Search box — totally reimagined with AI. This is the biggest upgrade to our Search box in 25 years and it’s starting to roll out today.
Designed to anticipate your intent, the new Search box helps you formulate your question with AI-powered suggestions that go beyond autocomplete. It will offer nuance that you might not have even thought to add — helping you ask the exact question on your mind with ease.
Plus, you’ll be able to search across modalities — with text, images, files, videos and even Chrome tabs.
#GoogleIO
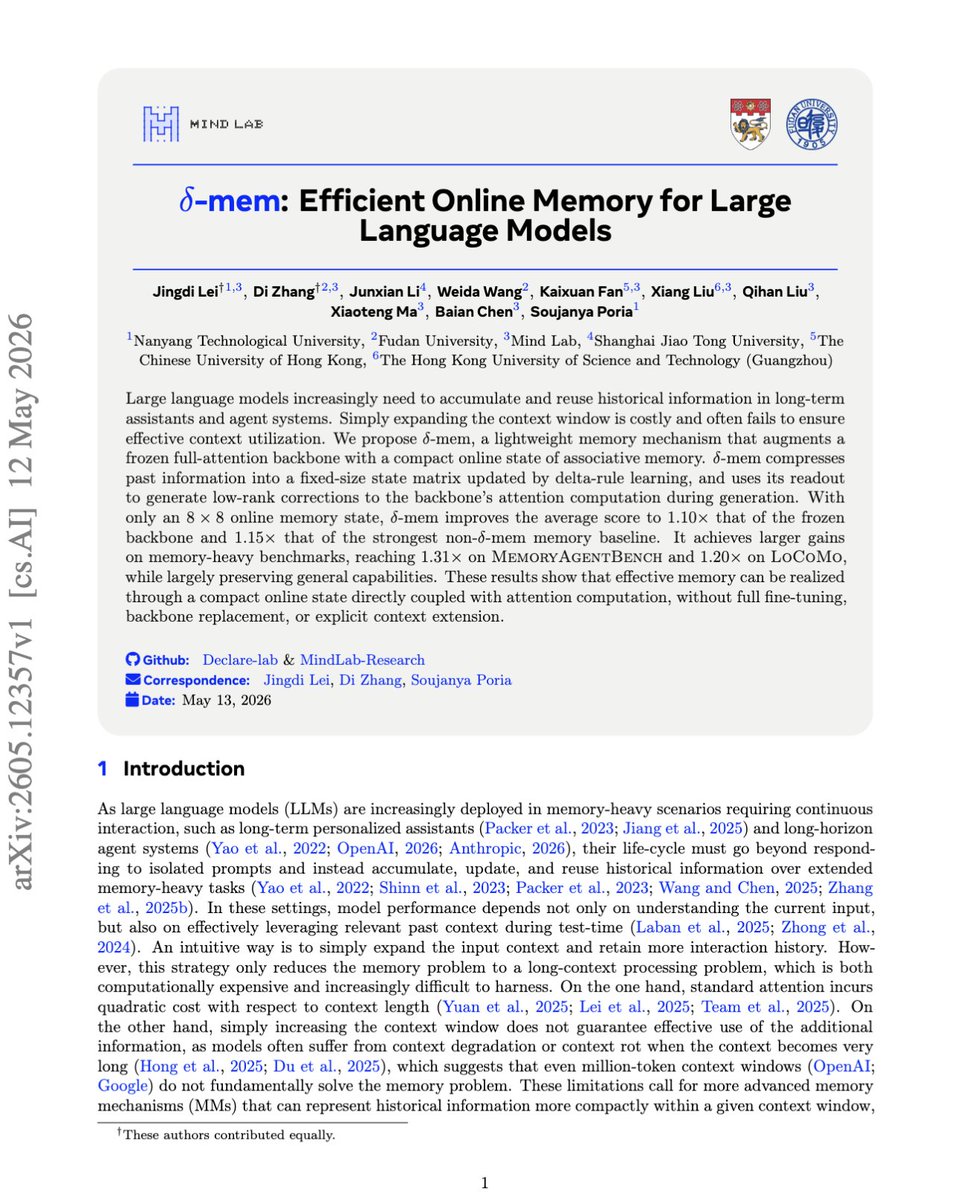
“δ-mem: Efficient Online Memory for Large Language Models”
LLMs need long-term memory, but extending context is expensive and often doesn’t mean the model actually uses the history well.
What this paper did is to store past information in a tiny 8x8 associative memory state, then use that state to make low-rank corrections inside attention.
So memory is not retrieved as text or added to the prompt. It directly steers the frozen model’s computation.
With only 4.87M trainable parameters, δ-mem improves Qwen3-4B from 46.79 to 51.66 average score, with bigger gains on memory-heavy benchmarks like MemoryAgentBench and LoCoMo.