I gave a lecture at @Stanford CS 25.
Lecture video: https://t.co/Js7SThVO6S
AI is moving so fast that it's hard to keep up. Instead of spending all our energy catching up with the latest development, we should study the change itself.
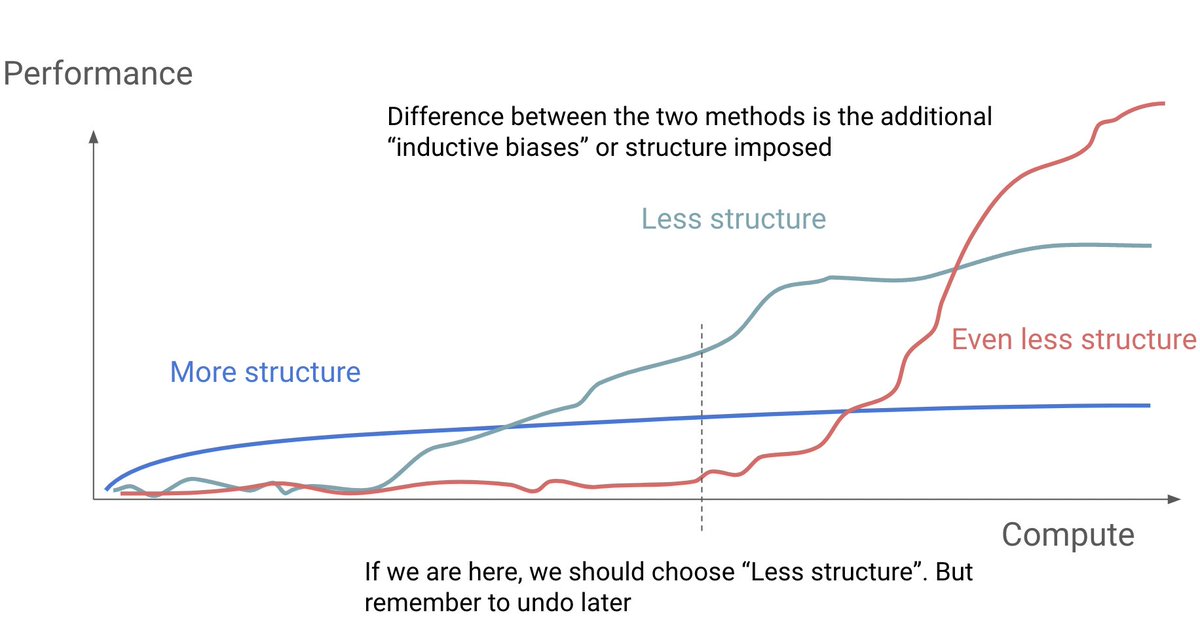
First step is to identify and understand the dominant driving force behind the change. For AI, a single driving force stands out; exponentially cheaper compute and scaling of progressively more end-to-end models to leverage that compute.
However this doesn’t mean we should blindly adopt the most end-to-end approach because such an approach is simply infeasible. Instead we should find an “optimal” structure to add given the current level of 1) compute, 2) data, 3) learning objectives, 4) architectures. In other words, what is the most end-to-end structure that just started to show signs of life? These are more scalable and eventually outperform those with more structures when scaled up.
Later on, when one or more of those 4 factors improve (e.g. we got more compute or found a more scalable architecture), then we should revisit the structures we added and remove those that hinder further scaling. Repeat this over and over.
As a community we love adding structures but a lot less for removing them. We need to do more cleanup.
In this lecture, I use the early history of Transformer architecture as a running example of what structures made sense to be added in the past, and why they are less relevant now.
I find comparing encoder-decoder and decoder-only architectures highly informative. For example, encoder-decoder has a structure where input and output are handled by separate parameters whereas decoder-only uses the shared parameters for both. Having separate parameters was natural when Transformer was first introduced with translation as the main evaluation task; input is in one language and output is in another.
Modern language models used in multiturn chat interfaces make this assumption awkward. Output in the current turn becomes the input of the next turn. Why treat them separately?
Going through examples like this, my hope is that you will be able to view seemingly overwhelming AI advances in a unified perspective, and from that be able to see where the field is heading. If more of us develop such a unified perspective, we can better leverage the incredible exponential driving force!
Slides: https://t.co/RccKFOqK7e
All attendees at #USCAP2021,
@MorphleDigiPath builds Supreme Quality Whole Slide Scanners at a fraction of the market price.
As USCAP 2021 approaches towards the end,
Don't miss our very special USCAP 50% Discount !!
Link to avail the Discount : https://t.co/5euUjF6ZX3
Affordability without compromises. With our #USCAP2021 50% discount, the cost of owning the end-to-end Whole Slide Imaging system goes down to just USD 11000 for you.
Visit us at https://t.co/bSFUMWvCTE
Reach us at https://t.co/3jgH2B0a87
#USCAP2021VNI#IAMUSCAP#PathTwitter
**New Paper Alert**
Presenting HoVer (HOppy-VERification) 🪜🐰Dataset for manyhop evidence extraction & claim verification at #emnlp2020 findings with @YichenJiang9@mohitban47, Charles, Zheng and Maneesh
Checkout https://t.co/tgPlYd2n7q.
Happy to share "HoVer: A Dataset for Many-Hop Fact Extraction & Claim Verification" in #emnlp2020 findings, requiring info from up to 4 Wiki articles + reasoning graphs of diverse shapes.
(cc @mohitban47 & @shikh_kgp, charles, zheng, maneesh) 1/4
Website: https://t.co/auSM75rwlA
#Sadak2 is 98% Nepotistic. We rated it based on 5 categories, Producer, Lead Artists, Supporting Artists, Director & Writer. 4 out of 5 categories have Bollywood Family members. When #nepometer is high it’s time to #boycottbollywood
Will you watch this movie? Tell us in comments
I was mildly sick for a few days w/ covid symptoms. Then my 29 yr old healthy boyfriend got really sick. 13 days later, after a relentless fever, awful nausea, pneumonia in both lungs + a reluctant trip to ER, he is finally turning a corner today. Some things I learned:
Do Attention Heads in BERT/RoBERTa Track Syntactic Dependencies? We (w. @zhansheng, @Shikh_kgp, @sleepinyourhat) perform an analysis of attention heads of BERT, fine-tuned BERTs, and RoBERTa to answer this: https://t.co/xIpa4ecbUh
@PATHTrain People are losing their swipes from last one hour. Do you guys care to reimburse them? There is no display of the trains being suspended. Why don't you just disable the swiping gates if the trains are suspended?
HOB-33 line and JSQ-33 suspended because of car equipment problem at 9 St. NJT rail cross honoring PATH @ NWK & NYPS. Show farecard to NJT employee. [13]
Proportion of women in CS and Data Science at NYU:
Undergrad CS major: 34% and rising (National average is below 20%).
PhD in CS: 20% (slightly above national average).
MS in DS: 42%
PhD in DS: 47%! (Yay!)