I've been building Sentiri Code 360 so I'd have one place to work alongside coding agents. It's been my daily IDE for months, mostly on local models. From here on, I'm building it (and things with it) in the open.
@dschewchenko@gkurttech I think it depends on what it is, sometimes it's Postgres, sometimes its qdrant, other times it's my personal software tracker via mcp.
@prottushx Just part of the process mate, it's hard to let it go even at scale. It pained me losing a single user when we had 50,000. Some will tell you why, the majority wont. Just remember they signed up, they tried it, they gave you their time, that's a very cool thing.
@tudoriustin_ It's super early days for us on Strix, Qwen was our first model, we've moved onto Nemotron Bolt and Lightning, and their performance currently is lower than even I expected, but lots of tuning ahead. Will be interesting to see how performance moved with future ROCm updates.
@blue0orbit@Wbackdown Last measurement was - 78% of code drafts and 32% of prose drafts kept, and 0 of 248,320 scores differing after rollback.
I still have far more testing to do though, so take those numbers as they are, they could go down or up, just need to put more data through it.
Qwen 3.6 35b-a3b running at around 70-89 tok/s under gladius on AMD Strix Halo. Certainly, a different beast than GB10. but you can still get work done at a decent pace.
So yes, on Strix Halo the 35B MoE decodes at 41.8 tok/s plain and 89.6 tok/s with drafting, and the routing is identical either way. We verify it bit for bit: after drafting 16 tokens and rolling back the rejected ones, 0 of 248,320 output scores differ from a run that never drafted.
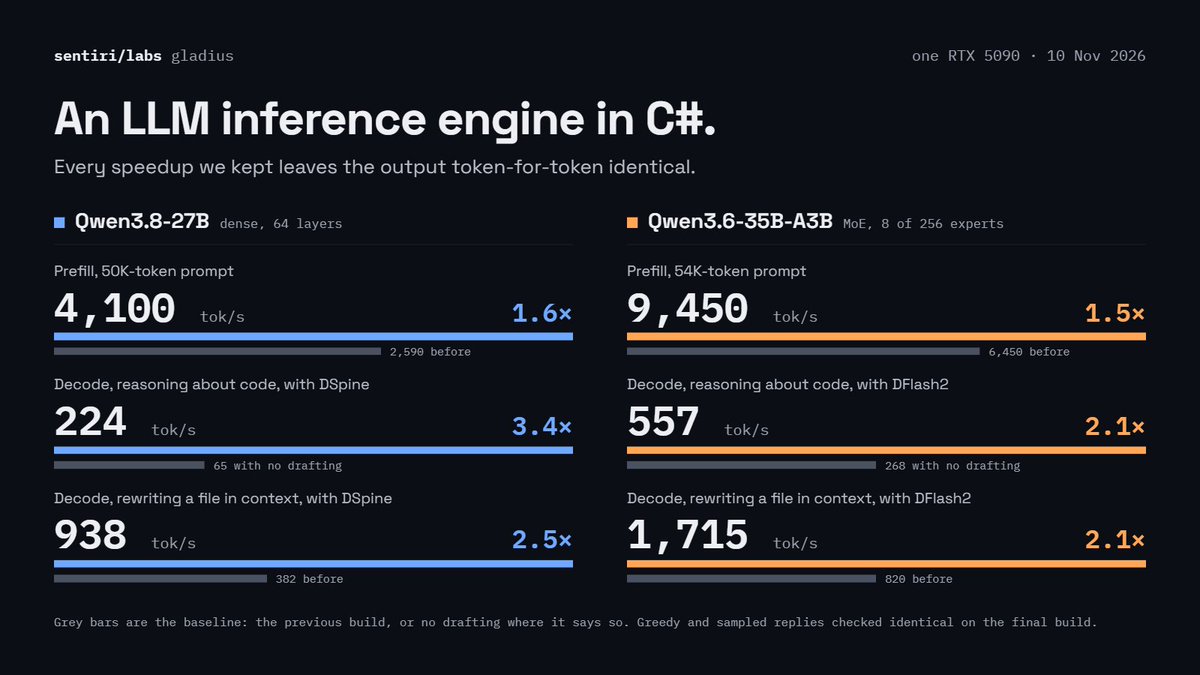
sentiri/labs gladius, our experimental C# inference engine got some massive performance improvements over the last week. We are not ready to release/open source yet, we will eventually. Our focus is accuracy over raw speed. DSpine is the reason for such an uplift on 27b, and DFlash2 for 35b.
https://t.co/PpnUTbPfpW
@jayleaton 100% and in the business world the token cost is already starting to bite. I have customers who are now looking into local AI, becuase they are paying frontier rates for things a smaller models can do.
@ashxhart Very interesting, you see mistakes carry all time, we built a ranking system but it's all manual promote/demote style. Might give this a crack.