Today, we’re making Praxis-1 available to everyone. Our state-of-the-art world action model turns video pretraining into control for real robots, and it ships with open weights under Apache 2.0, ready to run and fine-tune on your own hardware.
Software engineering is evolving in the age of AI. One way to conceptualize it:
We shift from building code, to building the machines that build the code. And in doing so, we won't evaluate the code, we will evaluate the machines.
Human attention transitions from PR-level change review to continuous system optimization.
If you’re comparing models by their price sheet, you’re missing half the math.
Jacob Loewenstein @spatialjlo from NVIDIA explains why token efficiency belongs at the top of your evaluation criteria, whether you’re adopting a model or training your own.
One of the standout moments from Open by Design NYC, where Jacob, Zach Wentz @zkwentz from Reflection, and Hassan El Mghari @nutlope from Together AI chatted with builders digging into open models, post-training, and inference.
Tired of waiting for your diffusion models?
🚢 We just shipped a major FastGen update:
- new models: H3, LTX-2.5, LingBot-World, Cosmos 3, FLUX.2
- new methods: PDD, AYF, AnyFlow, Causal Forcing
- new features: multimodal distillation, image editing, camera conditioning, KV cache management, ComfyUI
🔗 Try it out here: https://t.co/5lECuCstmy
(1/n) We’re sharing Nemotron-Labs-Diffusion-Uni: a unified diffusion language model for multimodal understanding and generation. It achieves SoTA understanding and generation performance by learning from autoregressive VLMs and continuous flow models via On-Policy Distillation
We're looking to hire DevRels for Dynamo!
Awesome parts about the job:
- Getting to be a community face for one of the most important domains in the world (Inference)
- High visibility
- Extremely motivated and fast-moving team
- Working in open source
- Lots of compute
/more
Today we’re releasing two decision models, elephant-1 (9B) and mammoth-1 (27B), trained by the @baselabs team, available for free for one week on our Model APIs.
mammoth-1 is #1 on the Jev Decision Index and elephant-1 is tied for #1 on the Artificial Analysis Decision Index.
It’s a new model, but more importantly, this is an open-source model you can access, deploy, and post-train on Baseten (or wherever you do your best work).
The free week ends 10/27/26 at 11:59 PM PT. Try it and let us know what you think.
Try mammoth-1 here: https://t.co/x8oDALMuyZ
Try elephant-1 here:
https://t.co/fmCGb3eGth
Model customization recipes are live on our website and in the cookbook repo.
Beam is now supported across RL and SFT stacks including @axolotl_ai, NeMo RL, NeMo AutoModel, Megatron Bridge (@NVIDIAAI), Miles (@radixark), SkyRL (@NovaSkyAI), and TRL (@huggingface).
Get cooking 🧑🍳
https://t.co/gRHcqEsa0s
Over the past two years of building @_inception_ai, one question has come up for me more than any other across countless conversations: Does the diffusion advantage scale?
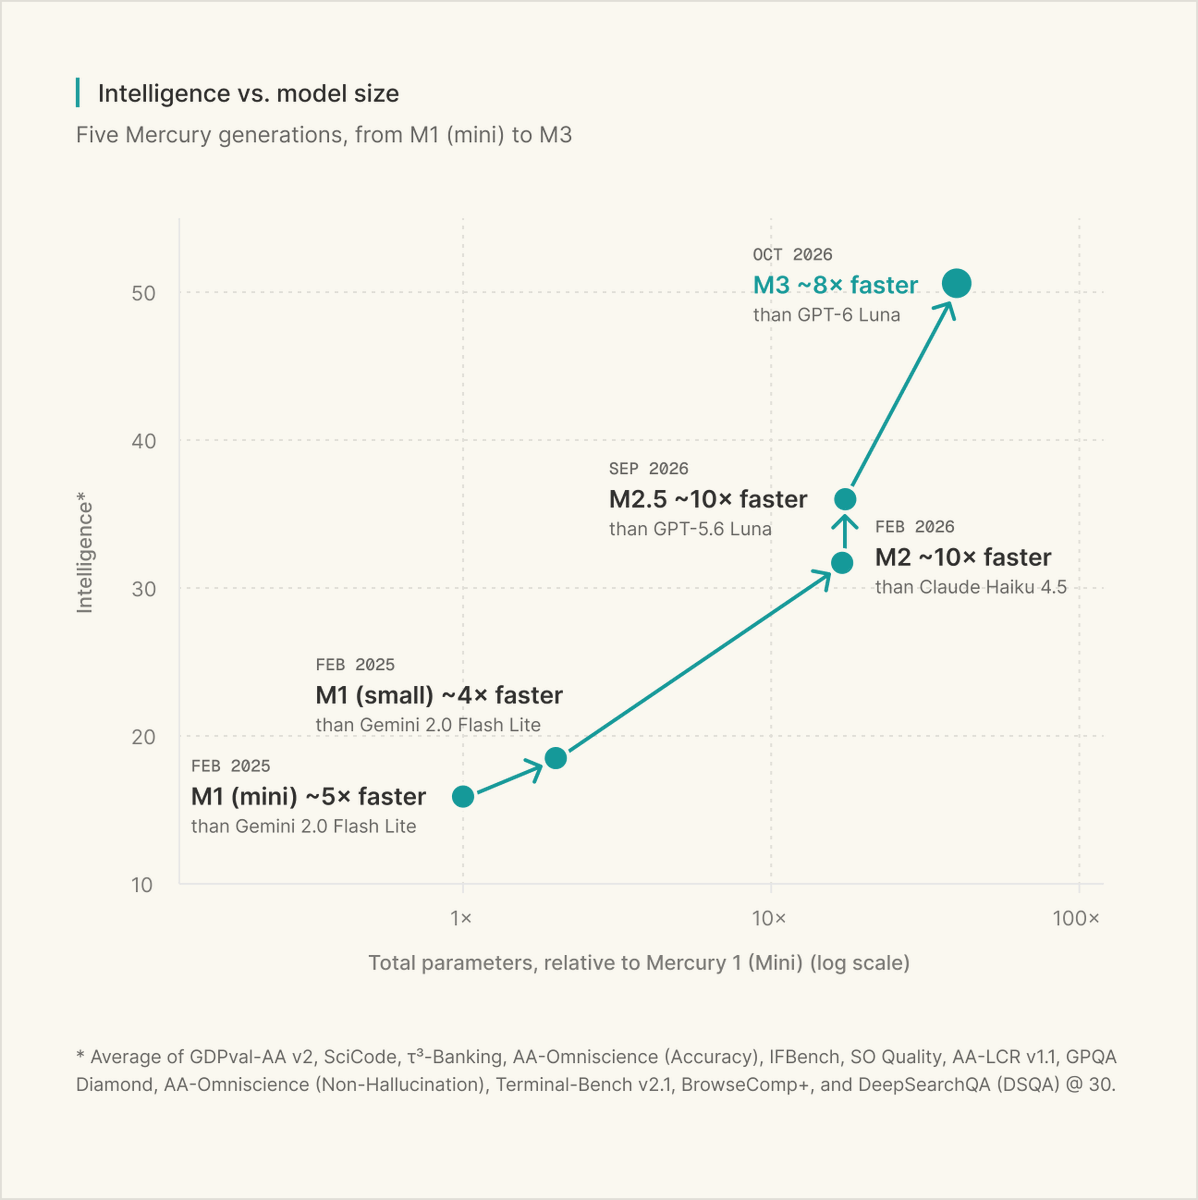
Today, we're answering that question with Mercury 3, our most capable diffusion LLM yet. Mercury 3 surpasses GPT-6-Luna and Claude 5.5 Haiku while delivering blazing-fast inference at 1000+ tokens/sec.
More importantly, the Mercury factory is up and running: Compared to Mercury 1, Mercury 3 is 40x larger and 3x more intelligent, all while maintaining the same industry-leading speed.
The diffusion advantage doesn't just scale. It compounds.
2/4 Mercury 3 demonstrates that text diffusion scales. At over 40x the size of Mercury 1, it’s vastly more intelligent while remaining just as fast. This is just the beginning: diffusion opens a new path to scaling AI, where intelligence can grow without a proportional increase in latency.
dLLMs remain one of the coolest and most slept on architecturally developers. Big leap fwd in intelligence and you can't get this kind of speed anywhere else w/o hardware acceleration!!!
1/4 Today, we’re releasing Mercury 3. Mercury 3 is by far our most powerful model and the most intelligent diffusion LLM ever released. It outperforms GPT-6 Luna and Haiku 5.5 on quality while running at 1000+ tok/sec.