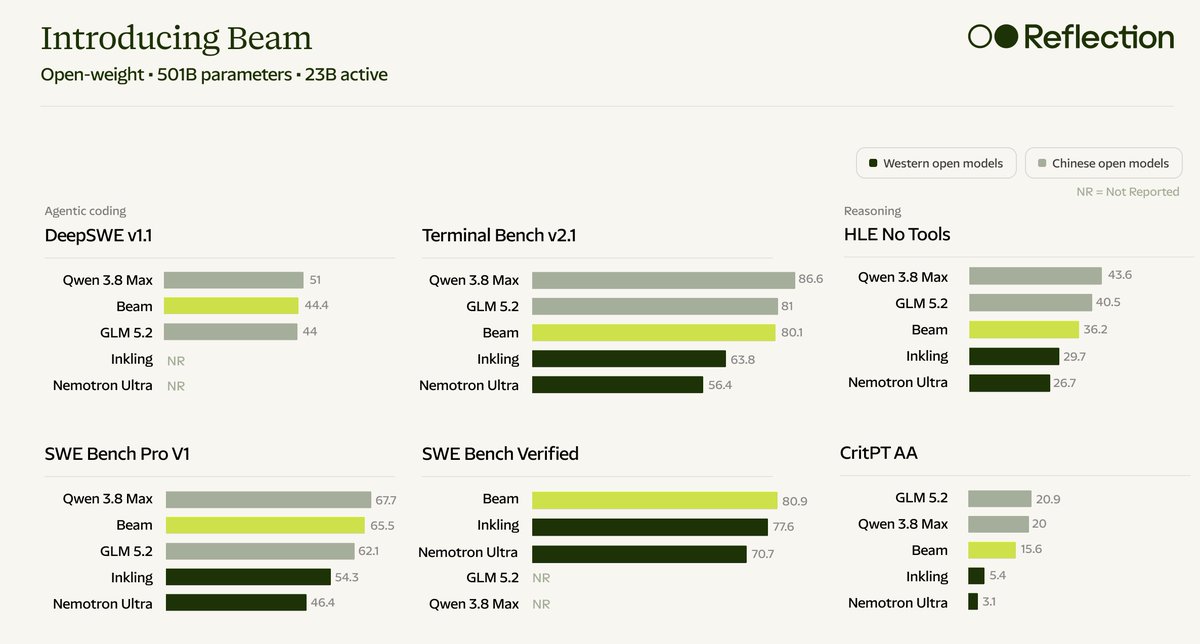
Introducing Beam: a highly efficient agentic open model with 501B total parameters and 23B active.
- Frontier reasoning efficiency
- Advances the Western open frontier on coding & agentic tasks
- Trained end-to-end from scratch
Full weights release this month.
Learn more about Beam: https://t.co/c3Qx2cpM8G
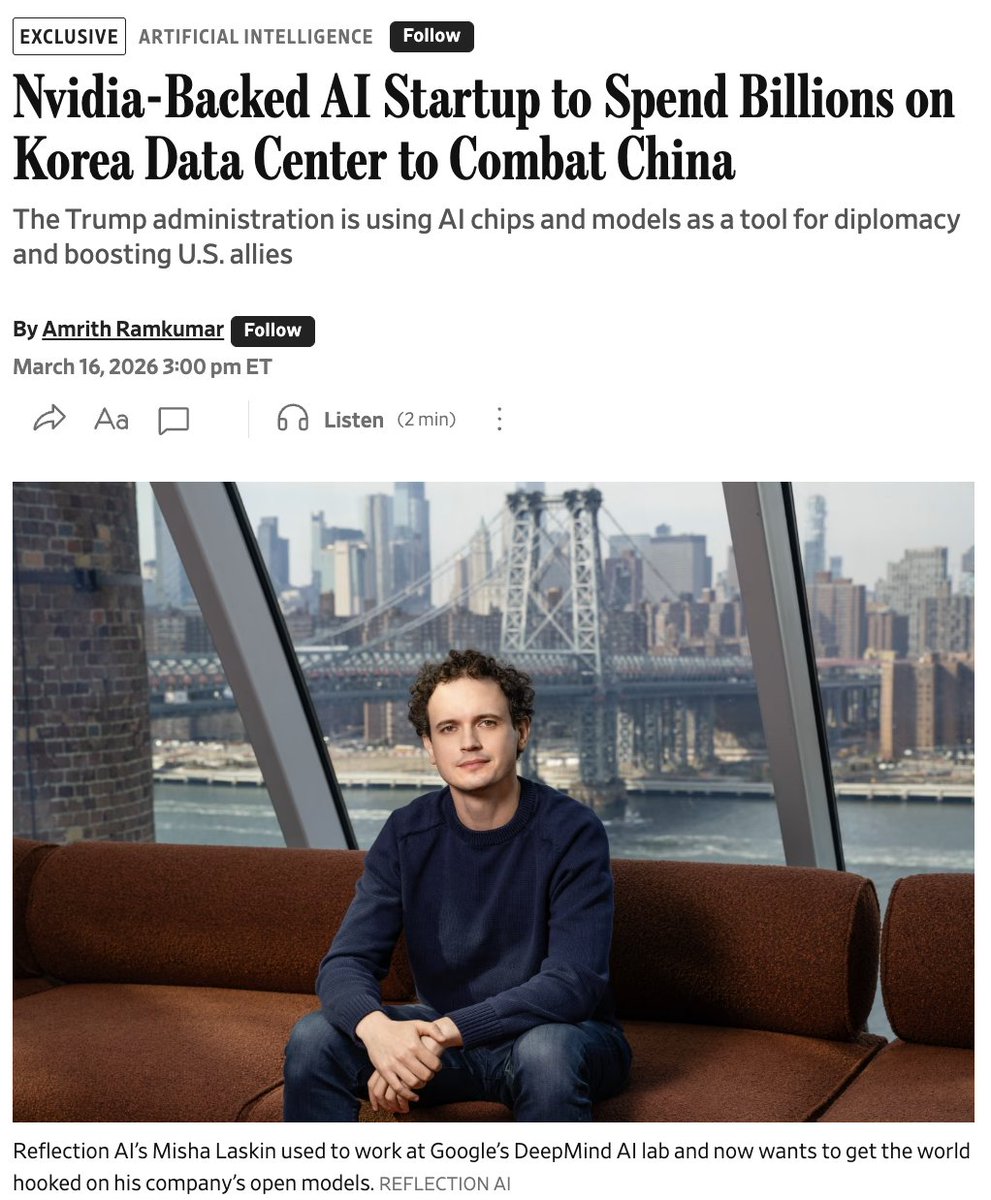
Reflection is partnering with Shinsegae Group to build a 250-megawatt sovereign AI factory for the Republic of Korea.
Open intelligence. Built on trust between allies. Owned by the nations that need it most.
The future of sovereign AI. Read more in the @WSJ.
Reflection is partnering with Shinsegae Group to build a 250-megawatt sovereign AI factory for the Republic of Korea.
Open intelligence. Built on trust between allies. Owned by the nations that need it most.
The future of sovereign AI. Read more in the @WSJ.
On-policy distillation with reverse KL as reward works great—IF you have access to teacher logits.
But what if you don't? What if you want to distill from multiple teachers?
Our solution: distill teacher guidance into rubrics, then do on-policy RL.
Check out our work: https://t.co/5kVYSSUGOB
New @Scale_AI paper!
The culprit behind reward hacking? We trace it to misspecification in high-reward tail.
Our fix: rubric-based rewards to tell “excellent” responses apart from “great.”
The result: Less hacking, stronger post-training! https://t.co/D6aJkZ8zZE
@sama A lone astronaut exploring a mysterious alien planet with a twilight sky, navigating bioluminescent forests, encountering creatures that are communicating through light