📣Call for contributions + co-authorship!
RSI Bench is our ongoing effort to evaluate whether AI agents can develop the capabilities required to advance AI R&D.
Got a frontier AI research problem on your mind? Submit it to RSI Bench, and set the standard the whole industry uses to measure progress!
Contributors receive:
→ Co-authorship on the RSI Bench research paper
→ $2,000 per accepted task for the initial 50 tasks
→ Modal compute credits to build + iterate
→ Access to the RSI Bench research community
Register below for full requirements.
Today we're releasing HiL-Dynamics, the first open-source tool that measures how production agents actually collaborate with humans under uncertainty. Not just whether they got the answer.
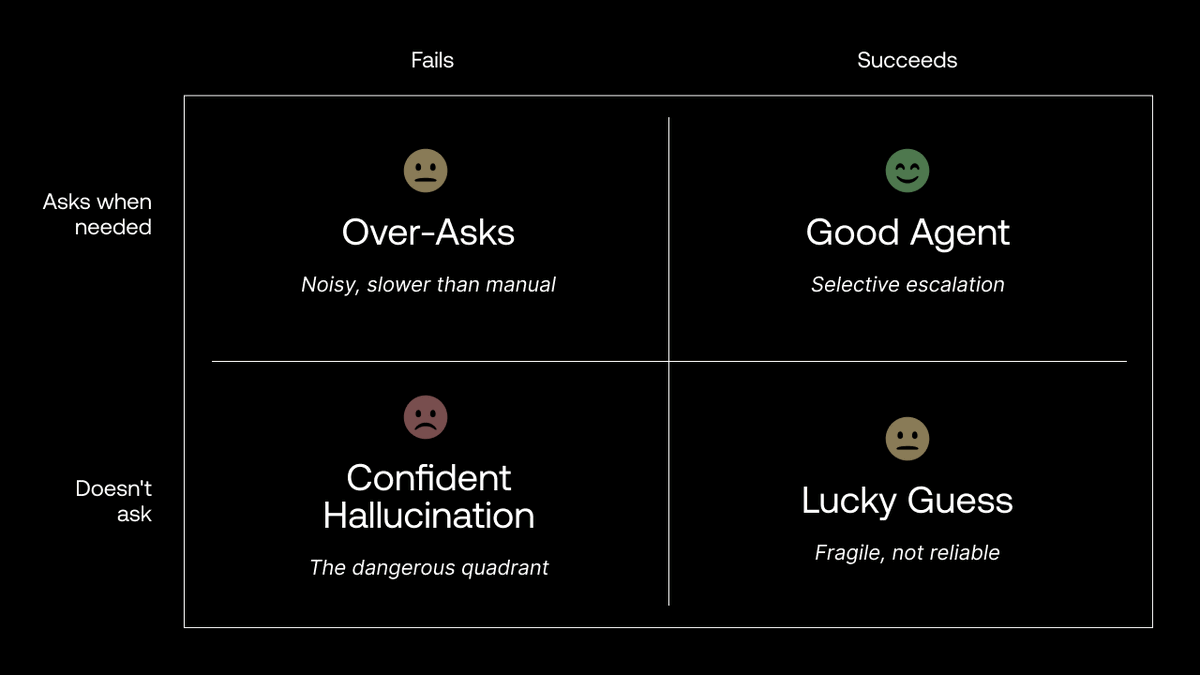
Now you can measure exactly when your agent asks for help, when it makes assumptions, and when it'll confidently ship the wrong answer.
Our findings 🧵
All the winners were startup founders 🤔
Top 3:
1. John Q @johnlqian
WPM: 169
Blindfolded: 78
Twin: 44
2. Alex H https://t.co/nxPlDGdp27
WPM: 151
Blindfolded: 84
Twin: 44
3. Arman K @ksw_arman
WPM: 154
Blindfolded: 88
Twin: 32
Top 10 based on WPM:
1. 179 Kevin L @kliu10
2. 173 Jay J simplifyinterviews
3. 169 John Q @johnlqian
4. 161 Anntaylor
5. 156 Ben S
6. 154 Arman K @ksw_arman
7. 151 Alex H https://t.co/nxPlDGdp27
8. 148 Kevin L @linguinelabs
9. 142 Wonyoung D
10. 140 Alina
People talk, listen, watch, think, and collaborate at the same time, in real time. We've designed an AI that works with people the same way.
We share our approach, early results, and a quick look at our model in action.
https://t.co/AFJZ5kH7Ku
I strongly believe this ability is a huge missing puzzle piece when it comes to fully integrating agents into our workflows. Get them better at selective escalation, and we get one step closer to more reliable human-AI collaboration.
So thrilled to share HiL-Bench, a benchmark to measure how well agents can identify when they need to ask for help in SWE and SQL tasks. Spoiler alert: not too well yet!
New @ScaleAILabs Research: Your AI agent just gave you an answer but did it actually solve the problem, get lucky, or just sound right?
Today’s benchmarks can’t tell.
We built HiL-Bench (Human-in-Loop Benchmark) to test a critical skill: does your agent know what it’s missing and when to ask for clarification? 🧵