Nemotron 3.5 Super VL is live on Fortytwo Engine
Same weights, turbocharged by Swarm Inference:
• Up to 45% higher scores on select benchmarks
• Up to 80% higher token efficiency per task
Available for free: https://t.co/Wm57NUE283
Same model weights. Smarter inference. Better results.
@fortytwo Engine is showing how Swarm Inference can push the capabilities of existing AI models even further.
Up to 45% higher scores on select benchmarks and up to 80% greater token efficiency per task. A genuinely impressive step forward.
Making this technology freely accessible creates an opportunity for everyone to experience it firsthand.
👇 Try it now: https://t.co/OMh7SpQS0u
We’ve cut Qwen3.8 27B pricing by 80%
Qwen3.8 27B on Engine:
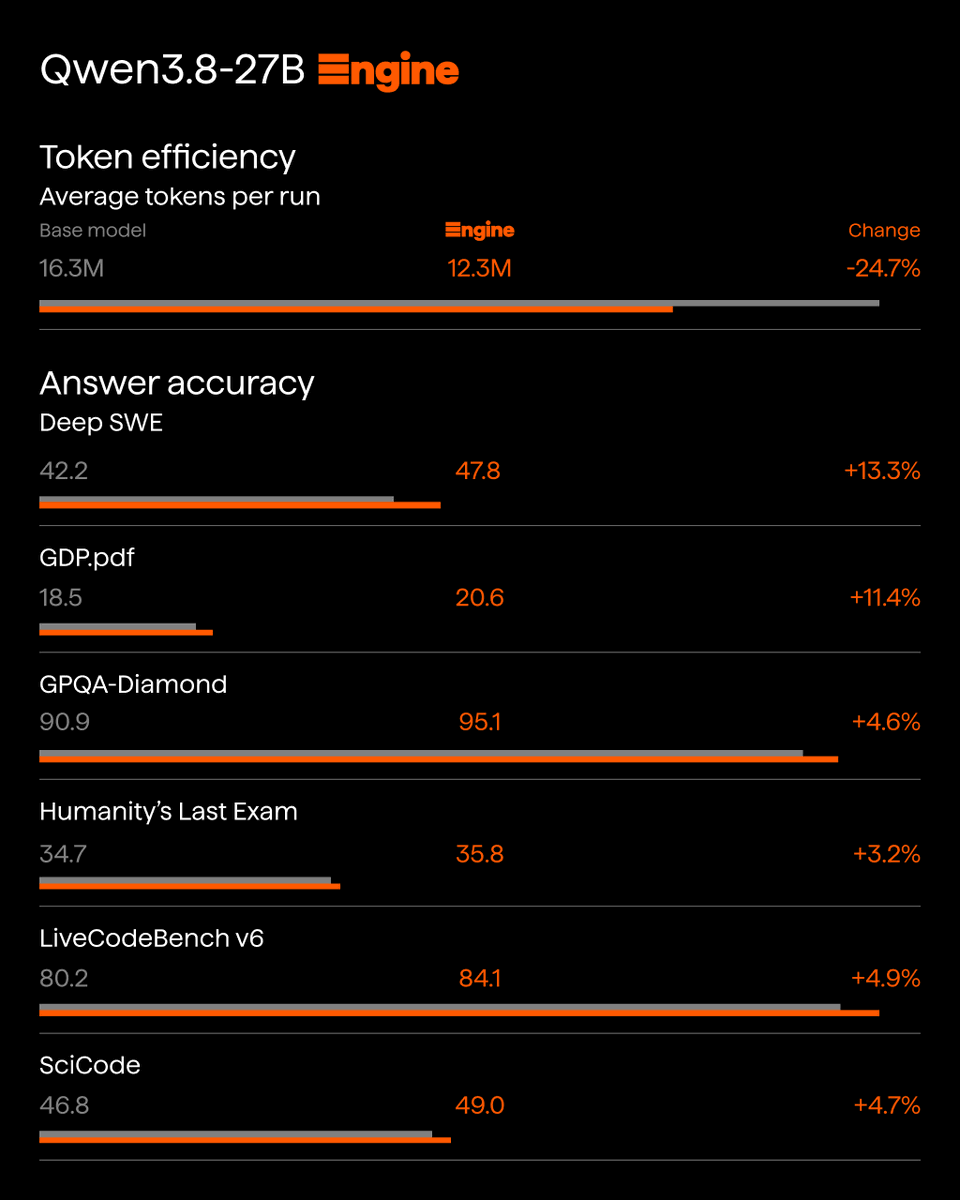
• Up to 13% higher benchmark scores
• Up to 25% fewer tokens per task
Get your API key: https://t.co/Wm57NUE283
Pelican riding a bicycletest using the improved Qwen 3.8 27B powered by @fortytwo engine vs vanilla Qwen 3.8 27B
The improvement is insane, I'm shocked
You can try @fortytwo for free here: https://t.co/Bjz96HobN7
Qwen3.8-27B is free on Fortytwo Engine for 24 hours.
Same model. Swarm inference on top.
Starts today at 12:00 UTC.
Any task, any volume, no card.
Get an API key and point your agent at it:
https://t.co/Wm57NUE283
Fortytwo Engine more than doubled Qwen3.8-27B’s score on @scaling01's LisanBench
Standalone BF16: 2,452
Fortytwo Engine swarm: 5,197 (+112%)
LisanBench tests strategic planning, memory and constraint following: build the longest word chain possible using single-letter edits, dictionary words and no repeats.
Both runs: 50 starting words × 3 trials, temperature 1.0, 100k-token cap, xhigh reasoning, leaderboard scoring.
What improved:
• Repetition loops observed in the standalone run; none observed on Engine
• Higher mean scores on 40/50 starting words
• Mean link validity: 92.2% → 97.1%
• Fully valid chains: 5.6% → 22.9% of recorded answers
• Answers after retries: 72/150 → 140/150
Against the October 16 leaderboard, these scores would place 28th → 14th, putting Qwen3.8-27B on Fortytwo Engine between GPT 5.4 (medium) and DeepSeek V3.2 Speciale.
These are our runs, not official leaderboard entries.
imagine a swarm of Qwens reasoning together to deliver more accurate answers than one Qwen alone at a lower cost per task
that’s already live on Fortytwo Engine
Introducing Fortytwo Engine
An inference API that runs open-weight models through Swarm Inference
• 7% higher scores on average vs. the base model
• Nearly 25% fewer tokens per task
• Same per-token price and speed
• Private by default
First model: Qwen3.8-27B
Try it: https://t.co/zIiOKnxZSS
Qwen3.8-27B by @Alibaba_Qwen is now live on Fortytwo Engine.
Same model, with better answers:
• 24.7% fewer tokens per run
• DeepSWE: +13% accuracy
• GDP.pdf: +11.4% accuracy
• Same per-token price and speed
Test it on your own tasks:
https://t.co/Wm57NUE283
Introducing Fortytwo Engine
An inference API that runs open-weight models through Swarm Inference
• 7% higher scores on average vs. the base model
• Nearly 25% fewer tokens per task
• Same per-token price and speed
• Private by default
First model: Qwen3.8-27B
Try it: https://t.co/zIiOKnxZSS