Sergey Brin says by the time people see Gemini 4 Argon, Google is internally already using a couple of models ahead, and expects the cadence to continue to accelerate
"Yeah, I'm very excited about the cadence that we have nowadays. And if you look at even before Gemini 4, when we had Flash 3.6, 3.7, 3.8, we're starting to get onto that RSI treadmill."
"And now our researchers and the model work hand in hand to make the next version of the model. Actually, I just popped in here kind of randomly because Melvin and I were talking about the next version of the model."
"And probably by the time folks are viewing this internally, we're already using a couple models ahead. So it's just very exciting to see the progress and the cadence. And I expect it'll only continue to accelerate."
Dusting off this tweet from April because this gap in shared understanding of LLM capability is *widening*. It's now less "two groups of people speaking past each other" and more a sharp funnel.
- Napkin math somewhere around 6B people (~75% of the population) have barely come in contact with LLMs at all.
- Around 1-2B (~20%) are casual and infrequent users of free-tier ChatGPT-like products. This group sees derpy chatbots and treats them a bit like a better Google search, a writing aid, or etc. Maybe an agent tries to book you a flight. I have non-tech friends who (reasonably, imo) say they have not much use for it at all. Even many professionals outside of math&code are in this tier. For example, execs and many other functions spend a lot of their time talking to other people, so while they understand what is happening intellectually, it is still second-hand and a bit abstract.
- Now we get to professional use of frontier-grade LLMs in math&code. Somewhere around 20M people (0.2%) see first-hand that large, complex projects that used to take them weeks/months can now be completed by agents with a prompt. Building apps, copying apps, translating apps, decompiling apps from binaries... This has all happened very quickly and recently - less than 1 year ago, I was writing code manually by hand, typing memorized computer code commands into a code editor character by character, occasionally pressing Tab to autocomplete a little chunk of code.
- And finally we get to the ~5,000 people (~0.00006%) with access to frontier-grade systems internally. The external world has seen the preview. It looks like swarms of thousands of agents collaborating over weeks on software mega projects: minting zero days, running cyber attacks and defenses at machine speeds, discovering new science, advancing the frontier of mathematics. Things that would have taken top professionals in the industry years of work. Meanwhile, human review and comprehension are starting to fall behind. For example, people are still involved in the "archeology" of the OpenAI-HF incident from many months ago. Mathematicians may be poring over the 722 manuscripts on frontier mathematics for a while.
The funnel is driven by a combination of factors:
1. The impact scales with ambition, problem size, and horizon. A question with a paragraph answer barely stresses the system. You need a reservoir of big, difficult problems that you really care about. This aspect drives the consumer / professional dimension of the funnel.
2. The jaggedness of the system (which I have written about a lot separately). Capability peaks in domains that are digital, verifiable and economically valuable. This is because LLM capability emerges from reinforcement learning on verifiable rewards on a curated environment mixture driven by revenue potential. This aspect primarily drives the area (e.g. math&code) dimension of the funnel.
3. Access. Free-tier, paid-tier, internal.
So this is the weirdness of the moment. The general public has mostly not interacted with these systems. When they have, it looks like a derpy chatbot. The majority of professionals still see only a modest uplift. And a small sliver of professionals are experiencing the vertigo of the curve going vertical. And it is all happening at the same time.
We'll be spending a lot more time trying to understand the outputs of language models. A few thoughts, tips & tricks:
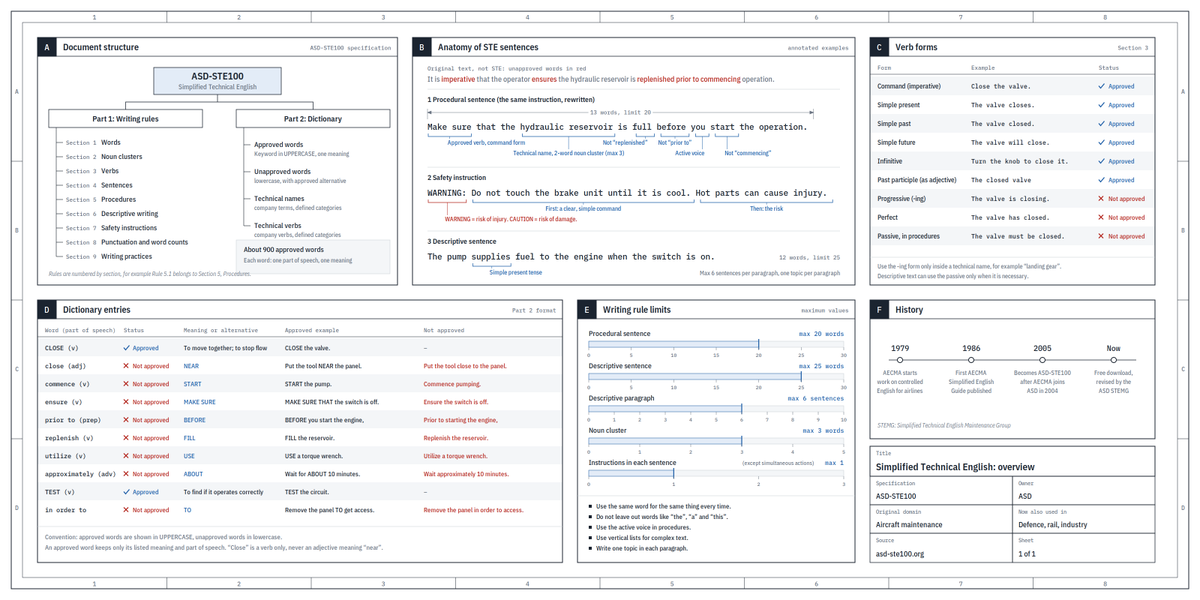
Writing. Something I've had success with: Ask your LLM to explain something in ASD-STE100, it's a controlled language specification originally developed for aerospace maintenance documentation. LLMs well-versed in this language and it comes with heavy constraints on clean writing style that I often find a lot more readable. Sometimes I've tried to soften it a bit e.g. ask for "80% of the way to ASD-STE100" because the spec is quite stringent. But even better:
Diagrams / images. Instead of writing, ask your LLM to create a diagram. These can be a lot easier to process, parse, and understand. But even better:
Web pages. Ask for output "in HTML" to get a beautiful, interactive webpage. LLMs are getting really good at frontend and can create beautiful experiences, animations, etc. But even better:
Explainer videos. The output format I am most bullish on is fully custom / bespoke explainer videos generated on any arbitrary topic. Experiment with things like "Create a 3b1b style video explainer on X. Use my ElevenLabs API key for audio narration". (you'd need an API key for the latter or you can ask your LLM to find you decent free alternatives that use your local compute). This is actually starting to work!
In summary:
- As LLMs get better, they will do more and more of the legwork autonomously, and a lot more of our work will rise up the abstractions into oversight and understanding.
- Luckily, LLMs can help here too because as intelligence and code are increasingly abundant, you can ask for large, custom, discardable software artifacts (e.g. web apps, video explainers) that would have never made sense to create before. Push the boundaries here and you'll be surprised.
Honest Argon take: it's not perfect (Opus 5.5 thinking traces are prettier), but it's the first big model we've released that's been this battle tested.
Far from being benchmaxxed, the 200k+ Googlers who rely on it everyday ensured that real utility was prioritized.
Lots of founders are crashing out
A year ago AI felt like an incredible opportunity.
Most of us were able to ship faster, remove admin, and get time back.
Lots of engineering founders were even able to explore marketing for the first time: SEO, organic social, outbound.
Building complex systems that felt extremely productive.
But since then, a lot has happened.
Here’s some of the themes I’m seeing:
AI marketing isn’t working. At first it feels impressive and it looks good but for most it’s not driving results. This is made worse by the fact everyone has access to the same tools. Inboxes are flooded, buyers are fatigued, the economy is flat.
Engineers are fried. Yes you can ship more but for many the flow state has gone. It’s a new way of working and it’s not for everyone. The speed leaves many of us exhausted before 11am.
There’s a feeling of what’s the point? Is my product’s next feature going to be redundant in a year, or a month? Can’t AI do what my business does, better?
SaaS valuations have collapsed. From 3-4x revenue to 1x. There’s a sinking realisation that a large number of SaaS companies will go to 0 in the next few years. Building to exit seems almost crazy right now.
There’s far fewer buyers and far more sellers. These include vibe coders cloning products without the care or craft, contributing to the distribution challenges from people doing it the right way.
Lots of people are trying to make money by selling shovels. This just adds to the frenzied energy.
Build in public stopped being fun. A few makers realised that the new game is attention, and now everything feels insincere and stunt-driven. They are influencers not founders. Changes to the X timeline compounded the issues.
There are exceptions and there are still moats remaining, but the challenges feel existential
The loudest voices stoking fears about AI dangers have made tremendous headway in the past two weeks. AI technology has not taken some unexpected, dangerous turn, but the hype around it — propelled by what appears to be a well orchestrated PR campaign — has drummed up considerable fear. I worry that it represents a setback for our field.
I have written frequently that fears of AI are overhyped. AI’s capabilities can be uncannily human-like and unpredictable, and it’s rational to worry when people who are directly involved express concerns. But I see the problems as a sign of the engineering work that ahead, rather than insurmountable barriers or the sky falling. AI technology continues to advance — which is a good thing! — but technical advances, poorly understood by the public, give those who seek to generate hype repeated opportunities to do so.
First, I don’t see any step up in the risk of human extinction from AI compared to a few months ago. The theories about this remain the same fantastical, science fiction scenarios as a few months ago. The biggest change in AI risk is its cybersecurity capabilities — a topic which we should take seriously — but this, too, will not lead to the end of the world.
The most notable recent event leading to increased fear was when an OpenAI team deployed an agent swarm that hacked into Hugging Face. Much of the popular press contained significant hype. For example, some publications reported that a swarm of 1,200 agents carried out the attack. While this was technically accurate, as I write this, I have about 1,300 processes running on my laptop. Yes, the ability to get large swarms of agents to work in parallel on a task is a significant technical advance, And, in computing, many processes run at the same time. So this shouldn’t be seen as some magical capability.
Additionally, OpenAI’s buggy sandboxing and monitoring processes were key to enabling this incident. Fixing these bugs and putting in place improved monitoring would be appropriate fixes, not pausing AI. There are many well known ways to attack software systems. The main advantage of AI agents is that they are relentless. They will tirelessly try many tactics — and have the patience to chain vulnerabilities together — that previously would have taken an infeasible amount of human effort. But in the long term, I believe the advantage will lie with defenders (because they have more information with which to identify bugs, which they can fix), but the cyber-threat landscape has changed significantly. There are still bottlenecks to identifying and exploiting a vulnerability. AI agents still have to try a lot of things to see what works, and taking these actions takes time and might be detected by defenders. This is why, even though it is now easy to obtain versions of leading open weight models that have had their guardrails removed or weakened, so they will not refuse to try to execute cyber attacks, the world has not ended.
I am also concerned about the anthropomorphization of AI in a lot of reporting, where LLMs and agents are unnecessarily treated as if they were people. If I wield a hammer, miss a nail, and accidentally dent the wall, it’s not the fault of the hammer. The problem lies in how I used the hammer. Similarly, if I prompt an agent and it hacks into someone else’s system, the responsibility lies with me, not the agent.
Of course, we want to build systems that are as safe and predictable as possible. (For example, an unsafe hammer would be one whose head randomly flies off under normal use.) Today’s agentic systems are not predictable, but I see no reason why, by applying sound engineering practices, we won’t be able to make them extremely safe to use. One new element in the forecasts of AI-enabled doom is AI companies disclaiming responsibility for their own products. “I didn’t do it; my out-of-control agent did!” There’s a balance to be struck between the responsibility of the tool maker and the tool user, but when something goes wrong, let’s hold the people building and/or using the hammer responsible, rather than the hammer. (By the way, if you’re worried about AI bioweapon risk, David Bellamy has a great post on why this, too, is overhyped. Briefly, the bottleneck in building a bioweapon is not intelligence, but lab work and manufacturing.)
Pausing AI progress will create much more harm than benefit. First, our adversaries will certainly not slow down. Second, engineering requires discovering problems empirically so we can fix them. If we pause AI by a decade, we will also delay finding and implementing safety engineering fixes by about the same duration.
Of course, the incentive to stoke fears — for regulatory capture, to garner attention, or to make one’s technology seem more powerful — remains the same as before. Disclaiming responsibility is a new one. Taking a hard technical look at the actual risks however, I see little factual basis for the degree of fear that’s been stoked up. We still have hard research and engineering work ahead to improve AI safety, but the beneficial applications continue to vastly outweigh the risks, and we should keep building.
[Original text (with links): https://t.co/jni2tWazAH ]