DSpark for Spark-X2.6-4B is here! ✨
Average BF16 speedup:
2.14x RTX 4090 (llama.cpp)
2.50x M5 Pro (MLX)
Download & ❤️ Like on @huggingface and @ModelScope2022!
https://t.co/KDNCbVFiyM
https://t.co/sYoBcXk5A5
1/4 Small model. Strong agent result. 🚀
Our Spark-X2.6-4B-GGUF scored 94.6/100 in a community-reported NanoBench run with Hermes Agent: 9/12 tasks solved.
Just 4B parameters. Thank you, userr99, for testing and sharing the result! Screenshot below 👇
update on the @SparkLLM ced retrofit: v1 lost a lot of long context retrieval (nolima went from 33% to 8%). turned out the split at layer 18 was the problem, the later attention layers need stuff that just isnt in the layer 18 state yet. moved the split to layer 24 and it comes back, 55% overall vs 47% for v1, stock is 59%
@Tylerwtzhang@vaiduakhu@jaro3th@noctus91 Just tried a few and WOW. It seems like a qwen3.6-9b we never got. Its more efficient than 9b, wastes less token and get more things done. Its perfect por personal assistant like hermes. Currently getting 82tks median with a rx 9070xt and using it at q8.
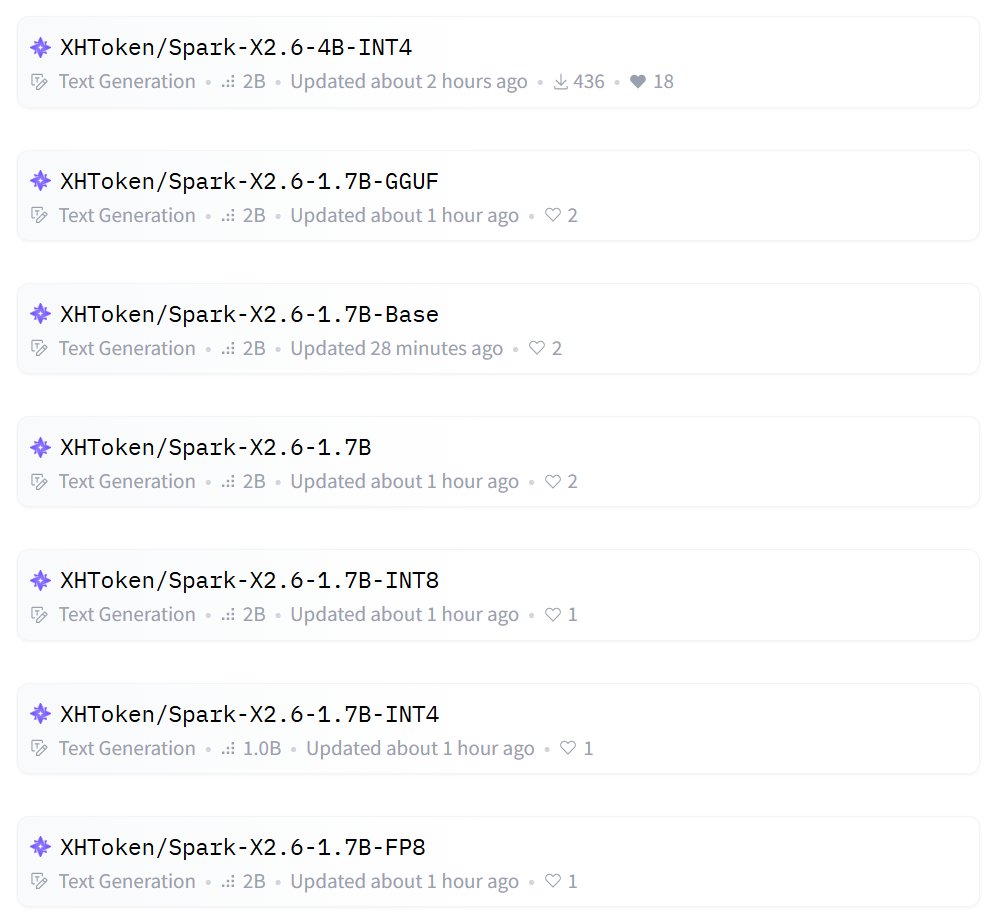
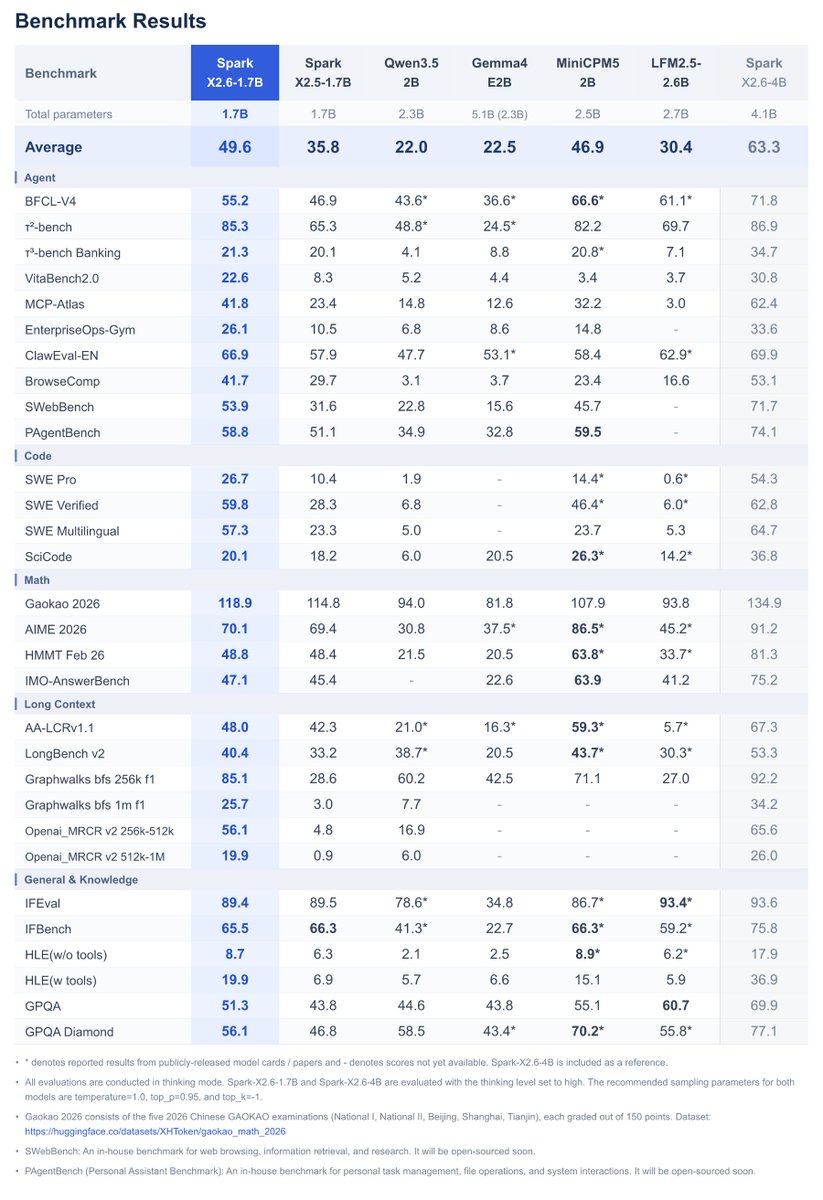
Spark-X2.6-1.7B: less than half the parameters of our 4B, close on two benchmarks:
SWE Verified: 59.8 vs 62.8
τ²-bench: 85.3 vs 86.9
Both at high thinking.
Try it & Like on HF!
https://t.co/kjB7OxCIZU
@huggingface@Ollama@ModelScope2022
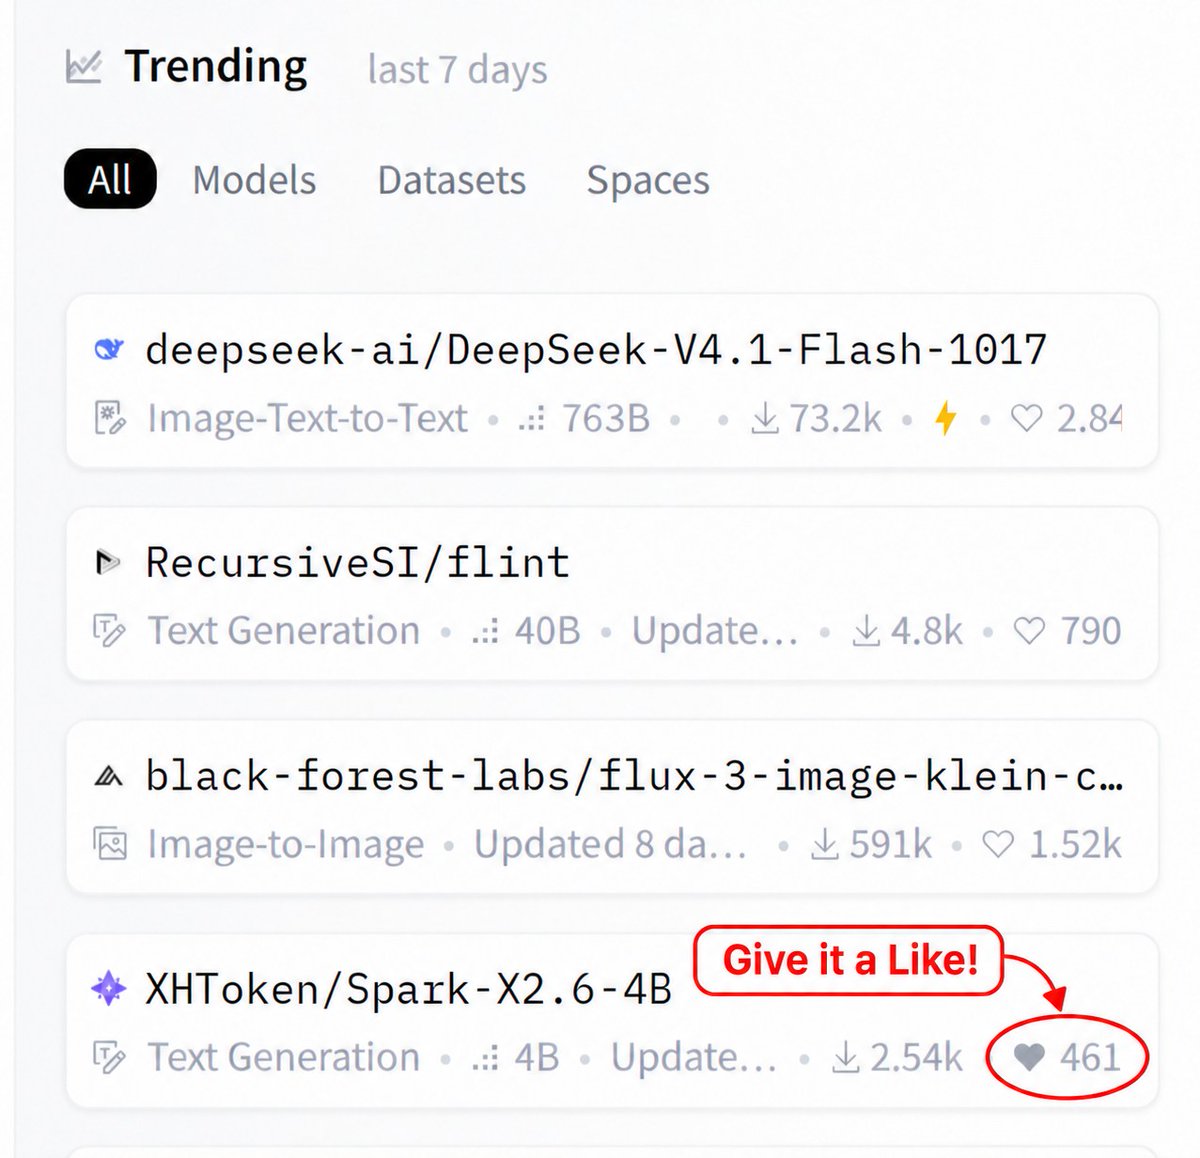
🎉 Spark-X2.6-4B reached #4 on Hugging Face Trending!
Snapshot: All · last 7 days, Oct 25, 2026.
Thanks for your support, hands-on reports & constructive feedback. If you find it useful, give it a ❤️ Like:
https://t.co/5GdI4SGeTo
When should the cloud execute for the edge agent, and when should it just advise?
We present a systematic study of edge-cloud collaboration in long-horizon agent execution. Using EC²-Bench, we evaluate four collaboration strategies across 128 executable tasks, jointly measuring task completion, resource cost, and privacy exposure.
Here are three key findings:
1️⃣ Small cloud budget, big gains.(cost-efficiency). With Qwen3.5-9B on-device and GLM-5.3 in the cloud, edge-only scores 39.12; the best collaboration reaches 60.46 — about 73% of cloud-only (82.70) — at only $8.73, roughly 15% of cloud-only's $56.42.
2️⃣ Performance converges, privacy doesn't. On Qwen3.7-Plus, best collaboration hits 76.84 vs 82.70 cloud-only; strategy gaps shrink to just 3.67 completion points, yet privacy exposure spans 66.23 percentage points — and the best-performing strategy leaks the most.
3️⃣ The mode flips with edge capability. Weak edges do best with an external router that lets the cloud execute (2B: Per-step Routing 39.97 vs self-delegation 15.86); stronger edges do best when the cloud only advises (9B Cloud Advisory 60.46).
Further experiments highlight two abilities that matter for effective self-directed collaboration: knowing when to ask for help, and actually acting on the cloud's advice.
📄 Paper: https://t.co/ESc7nA1Aeu
🌐 Project: https://t.co/J1A3ZjtgCj
💻 Code: https://t.co/xjAuYnCDT1
#EdgeCloudCollaboration #AIAgent #LLM #OnDeviceAI #AgentBenchmark #EC2Bench #OpenBMB #Tsinghua
🚀 Spark-X2.6-4B is now #5 on Hugging Face’s model trending list! @huggingface
Thanks for all the support! 🤗 Give it a try and let us know what you think.
👉 Try https://t.co/5Eu9C44XN1
#Spark#HuggingFace#OpenSourceAI
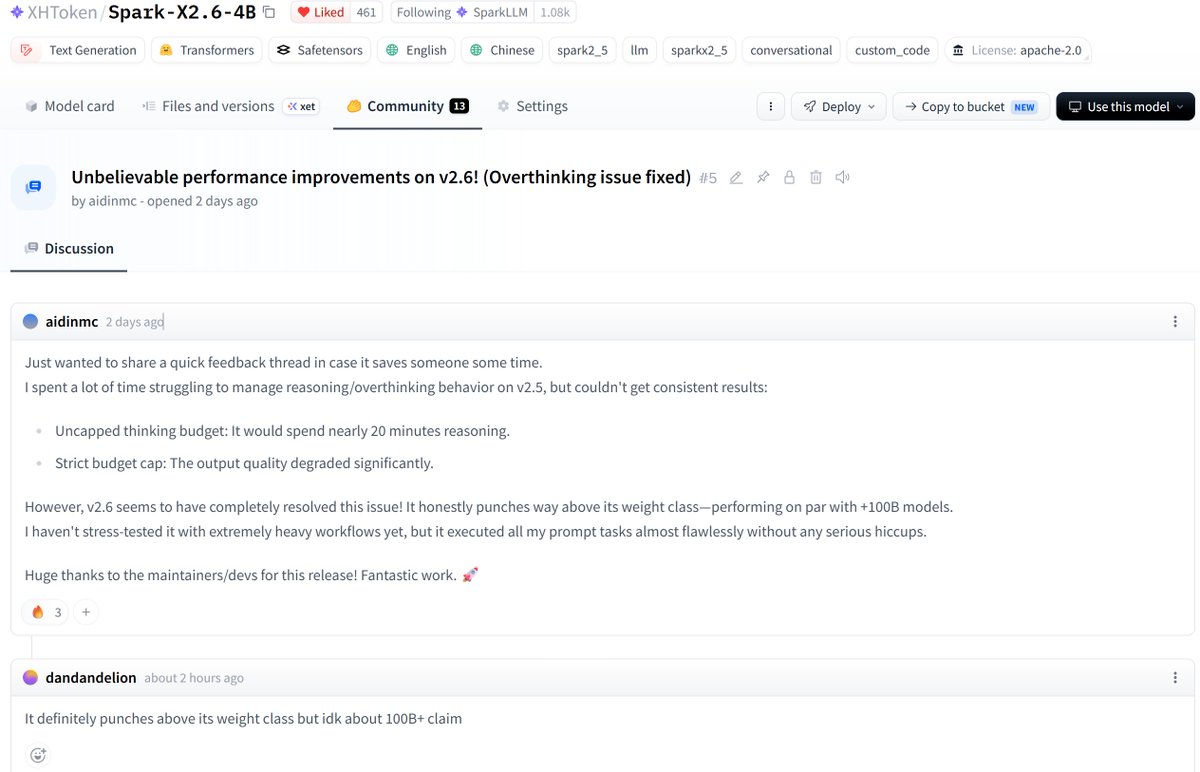
A 4B model is matching 9B models on several benchmarks. Spark-X2.6-4B: same arch as X2.5, gains all from post-training — coding, agents, 1M context, on-device. The small-model curve is steep. https://t.co/RndcMSt4uP
@SparkLLM@huggingface@ModelScope2022@ollama@vllm_project@sgl_project 🚨 Update🚨
We may have the best <16GB VRAM model over here. Impressive results and impressive speed.
⚠️The benchmark is about RAW performance. Thinking OFF, and MTP OFF.
Spark had difficult time with Terminal-Bench 2.0 (samples)
But Overall TOP #1 quality/speed for sure.
@NayteThaGreat Yeah going to test it myself on my own benchmarks. So far no small model has been able to beat Qwen3.5-9B. I’m getting ~70 tps so far on this new model