📰 Some News:
🥇DeepSeek Flash is leading #1 and #2 position most used API on openrouter.
Some free intresting API : GLM 5.3 and Flash.
🪧Keep updated on : https://t.co/6O9fpd7qVW
Hey,
You can now run frontier level model on you gaming PC. Of course not the full one, but these models out perfoms largely most of local model, even with smaller quants (IQ2 etc).
Thanks to @coldniko for Strata and @mhelcig for GSQ-RCO quants, Bravo👏
Run a 763B-parameter model locally. DeepSeek-V4.1-Flash-1017 on a 12GB GPU.
Frontier quality with GSQ-RCO quants, directly supported in the Strata inference engine.
Further info below. Much more to come. Follow for updates.
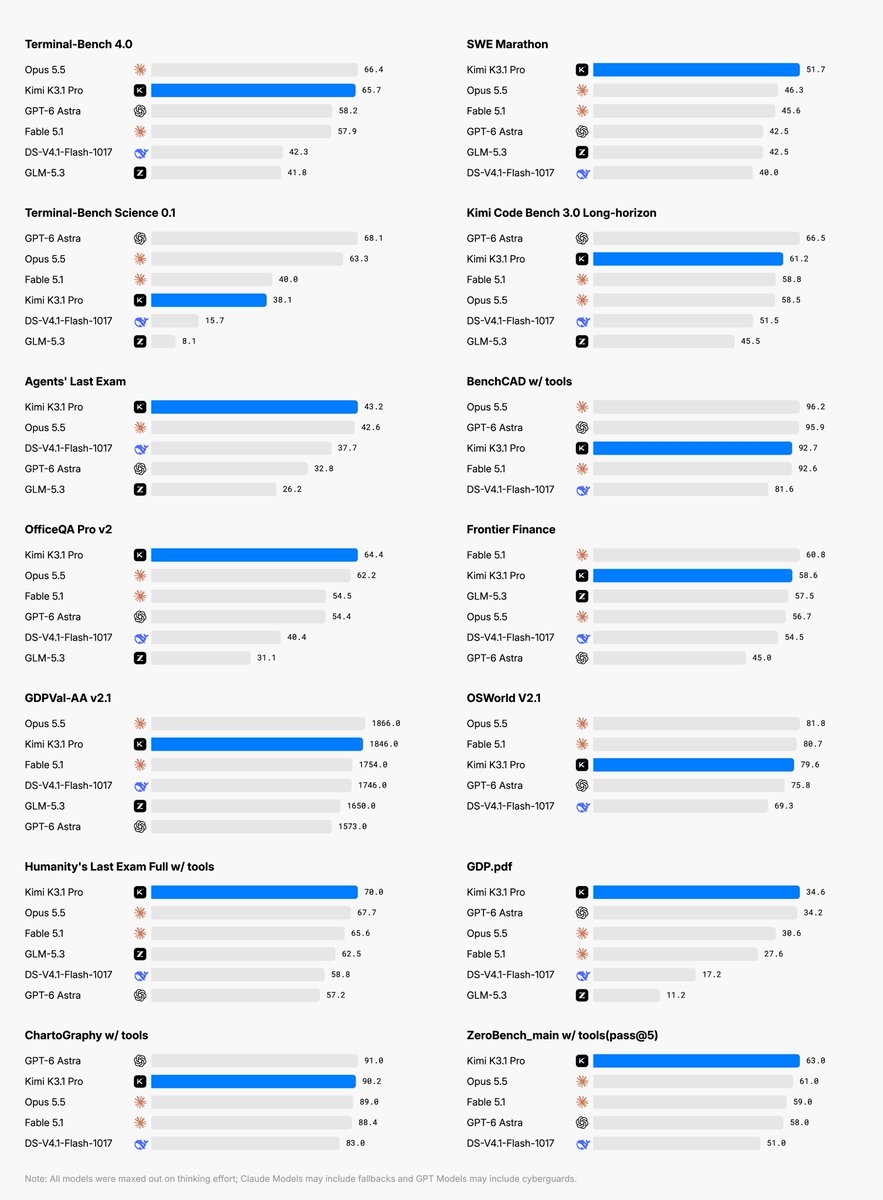
🆕 🌘K3.1 is here. Thats crazy, we now an open source frontier level model. Wish I can run it localy, may be one day.
The benchmarks look solid🧮.
Bravo @Kimi_Moonshot 👏
Introducing Kimi K3.1 Pro: our most capable 3T-class open-weight model.
🔹 1M-token context, 2.8T total / 104B active params (MoE), Multimodal.
🔹 Full-project coding: games in Unreal, Unity & Godot.
🔹 Excels at parametric 3D modeling in Blender & CAD.
🔹 More reliable at finance work: Accurate modeling with hallucination down by 65%.
🔹 Matching the strongest proprietary models across coding, agentic and knowledge benchmarks.
Kimi K3.1 Pro and K3.1 Pro Highspeed (2–3× faster) are now live on https://t.co/85jA71X9gw, Kimi Work, Kimi Code, and the Kimi API.
Open weights by Nov 4, 2026.
🔗 API: https://t.co/XCrgjXAqMw
🔗 Tech blog: https://t.co/5iPP0MBej6
@MiaAI_lab I think we have real candidate for qwen3.6:35b
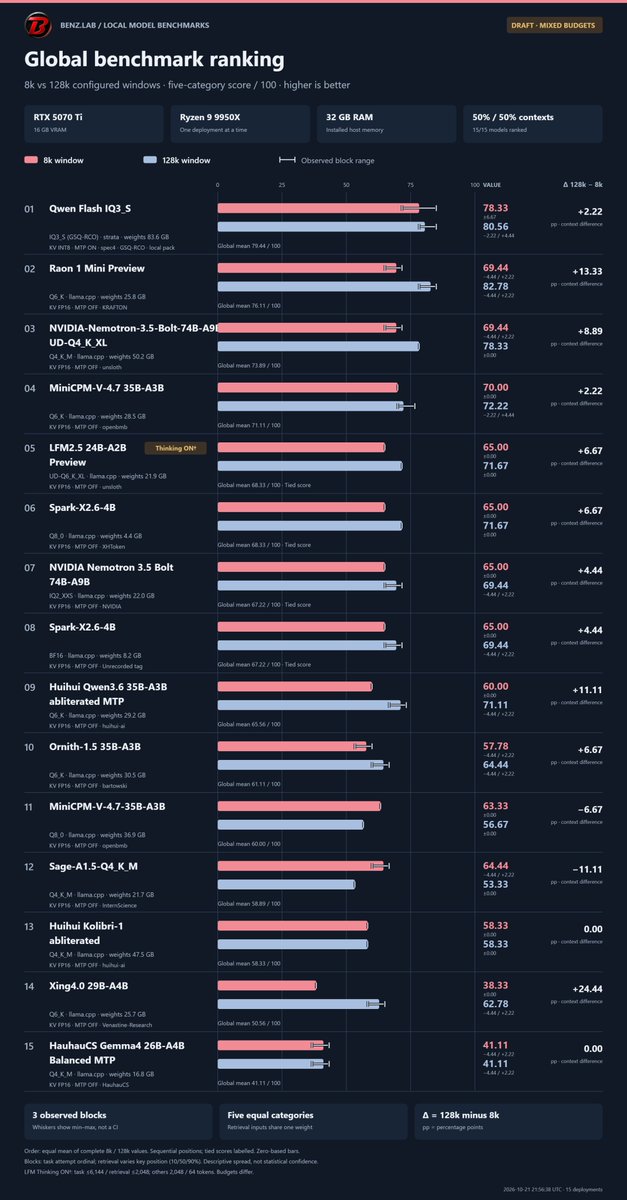
1. Raon 1 Mini Preview from @Krafton_AI
2. MiniCPM-V-4.7:35B-A3B from @OpenBMB
3. LFM2.5 24B-A2B from @liquidai
4. Spark-X2.6-4B really suprised me best speed/quality and impressive performance from @SparkLLM
@Kangwook_Lee Ok, we may have finaly the real heir to Qwen3.6:35b
Impressive RAW performance. 100% at SWE bench samples. With descent speed at high context, Q6 qant.
@TeksEdge And it delivers. Best model tested on my bench (for this size category). got 100% at SWE Bench, even Qwen3.8-Flash-IQ3_S didn't hit that score.
@Kangwook_Lee Now, thats an impressive model.
Rank #1 in SWE bench, it got 100% first model I tested to get that socre.
Rank #1 at high context 128k ctx.
Descent speed ~35 tok/s for a Q6_K quant, even at 128k.
All of that raw performance, no MTP, no Thinking.
Well done 👏