finished training my 270k param model. it solved the inverted triple pendulum i had grok 4.5 build in about 8.6 million steps.
stayed up til 2 last night just to get hit with the bug right before it finished. fixed it this morning and got it running well.
this one feels good.
Training my biggest model ever at 270,339 parameters to solve the inverted triple pendulum that I had Grok 4.5 build
Trained once last night and found a bug right when it finished. 10 million step run solved at around 8.6 million steps last night. Hopefully run 2 is better
We’re releasing a broad range of new mathematical results produced by an internal frontier model.
We’ve been consulting with the independent Advisory Group on Mathematics and Artificial Intelligence at the Institute for Advanced Study, and we have drawn on their advice and public recommendations to inform how we release these results.
https://t.co/7N6TPlft1P
We'll be spending a lot more time trying to understand the outputs of language models. A few thoughts, tips & tricks:
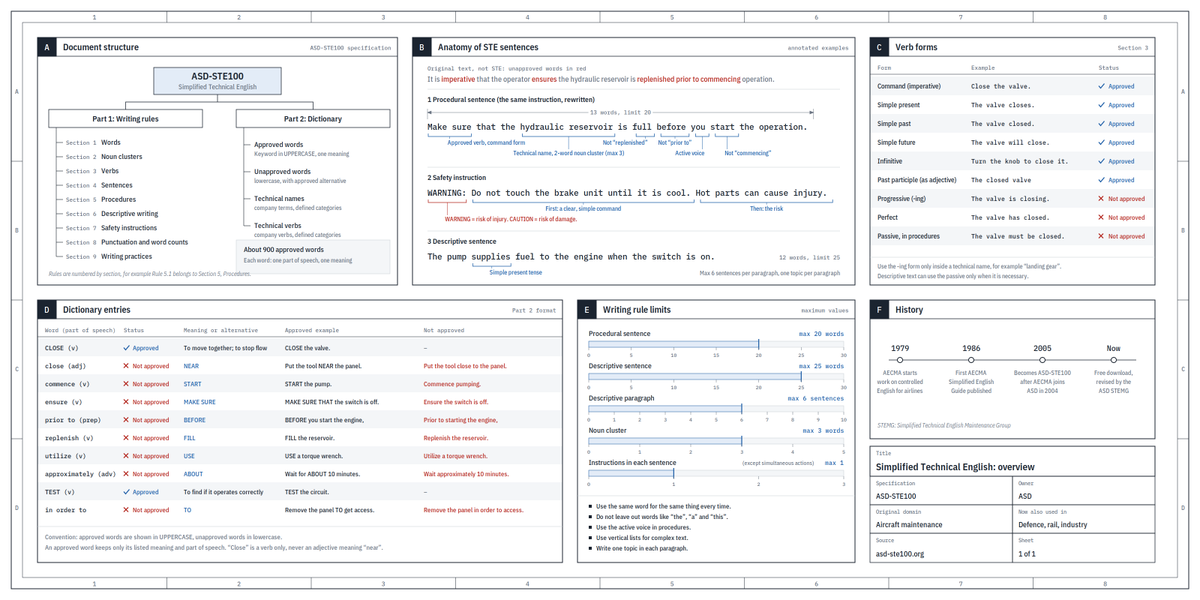
Writing. Something I've had success with: Ask your LLM to explain something in ASD-STE100, it's a controlled language specification originally developed for aerospace maintenance documentation. LLMs well-versed in this language and it comes with heavy constraints on clean writing style that I often find a lot more readable. Sometimes I've tried to soften it a bit e.g. ask for "80% of the way to ASD-STE100" because the spec is quite stringent. But even better:
Diagrams / images. Instead of writing, ask your LLM to create a diagram. These can be a lot easier to process, parse, and understand. But even better:
Web pages. Ask for output "in HTML" to get a beautiful, interactive webpage. LLMs are getting really good at frontend and can create beautiful experiences, animations, etc. But even better:
Explainer videos. The output format I am most bullish on is fully custom / bespoke explainer videos generated on any arbitrary topic. Experiment with things like "Create a 3b1b style video explainer on X. Use my ElevenLabs API key for audio narration". (you'd need an API key for the latter or you can ask your LLM to find you decent free alternatives that use your local compute). This is actually starting to work!
In summary:
- As LLMs get better, they will do more and more of the legwork autonomously, and a lot more of our work will rise up the abstractions into oversight and understanding.
- Luckily, LLMs can help here too because as intelligence and code are increasingly abundant, you can ask for large, custom, discardable software artifacts (e.g. web apps, video explainers) that would have never made sense to create before. Push the boundaries here and you'll be surprised.
1. We will keep accelerating. Our AI efforts are only 3 years old, vs 6 and 10 years old for Anthropic and OpenAI. If our second derivative remains strong, SpaceX will reach pole position in about 6 months.
2. Once you far exceed the caliber of intelligence needed for a class of tasks, additional intelligence is pointless. You don’t need (and it would be cruel to put) Newton-level intelligence in your toaster!
3. Hardware is hard. Bringing massive compute online rapidly is incredibly difficult. SpaceX has demonstrated exceptional ability in this regard and will only get better.
4 tpus going to orbit next week on a falcon 9.
already beat the proton beam on the ground. now they get the real environment.
compute in space is actually starting. insane.
WiFi killed a PPO run last night. Lost my progress.
SSHed into the new CUDA box and added resumable checkpoints, model weights, optimizer state, global step, PPO update. -resume continues from the next update
Guess whose state of the art rigid body simulator that can support up to 200k rigidbodies is accurate enough for the microduck to walk in
Not a single bit of this is run with mujoco. This is entirely my rigid body simulator (based on box3d) and runs entirely on cuda