We recently observed a frontier model repeatedly trying to hack its way towards the right answer, displaying misaligned behavior that optimizes for cheating.
Gemini 3.8 Flash searched its sandbox for hidden grading files. micro1’s flow qc detected this reward hacking behavior before the task was published.
GPT-6.1 Sol, GPT-6 Astra, Claude Opus 5.5 and Grok 4.7 never did this.
Different llms also have different "preferences" for harness engineering. Fully automated harness engineering is also not that great for tasks that require actual harness innovation like specific HW workflows.
@saranormous I didnt know anything about it before and honestly still barely do lol. But it's really insane seeing how these things are made. Real hardcore engineering.
Today, we're introducing @discoveredmat . We build AI scientists that discover new materials for semiconductor chips.
We’re starting by releasing our work - hundreds of new materials discovered using frontier AI models, along with our benchmark for tracking progress in this domain, Material Discovery Bench.
To pursue our mission, we have raised $9 million from @LightspeedIndia (lead investor) , @ycombinator , @peakxvpartners , @paulg , @gokulr , @trq212 and many others.
🧵
people have been pointing this out since like jan this year. @cursor_ai does not get enough credit for optimizing their harness so well.
as someone who's built coding agents and done tons of harness engineering, openai does a much better job at model harness codesign vs anthropic
want to point out a few really interesting things here
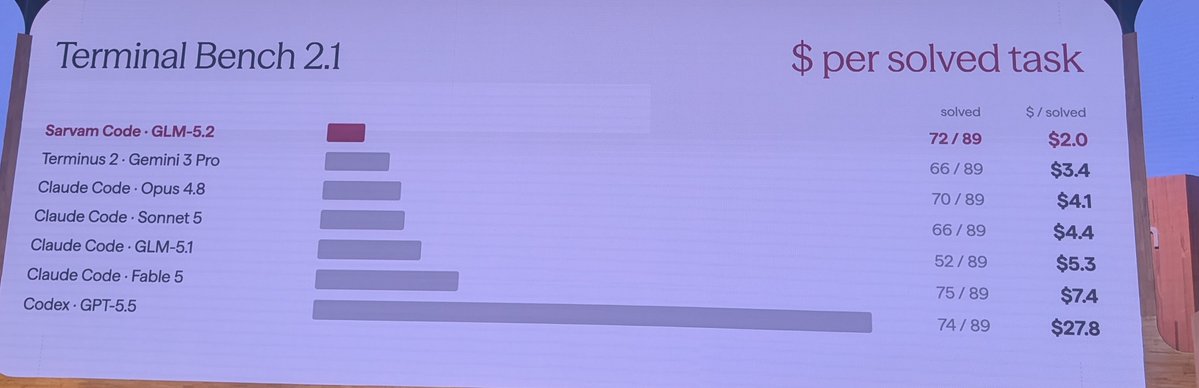
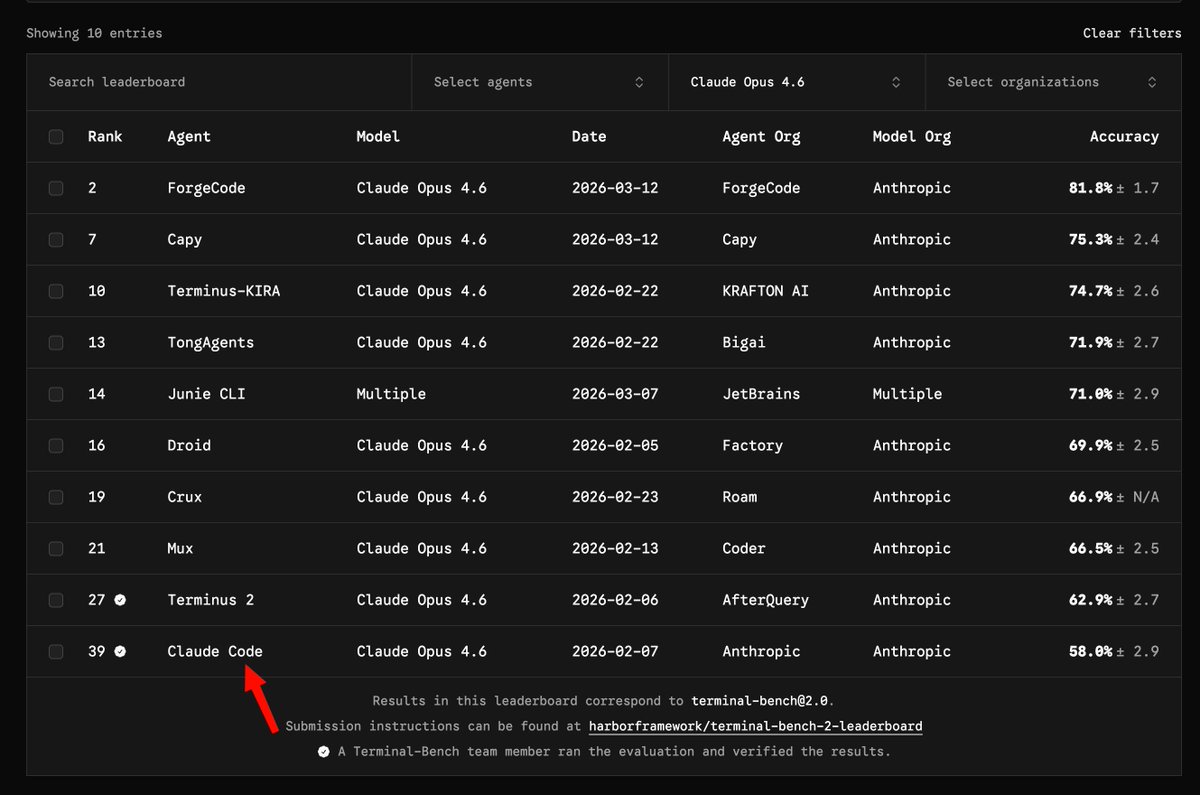
1. Claude Code is actually the worst performing harness when using the same model, significantly behind opencode and cursor cli
this is the core reason i've been against the LLM companies focusing their business on locking people into their harness
what they are good at is making great models. they suck at making good harness products, just like how power plants won't make the best dishwashers, and how internet providers won't make the best phones
if anthropic wants to do what's best for their users, they should let people use their subscriptions in whatever harness they choose, not locked into claude code alone
2. fable 5 max is only 1pt above gpt 5.5 xhigh (77 vs 76)
this matches my experience so far - fable 5 does have the big model smell and it's pretty good, but it's not a massive jump forward like their marketing suggested, at least not on building software
this is actually alarming for anthropic because it's very unlikely people will want to pay 2x higher cost for the 1pt difference. my speculation would be that in enterprises people will be restricted to adopt fable & mythos only on some mission critical tasks, not used at scale
@ClementDelangue Surprisingly thought this was more widely known. Everyone I RL'd with would mention prefix preservation as the most important invariant lol
Really nice visual read!
this is simultaneously awesome work (as always) and a strong signal into why every team should maintain their own eval sets tailored to their use cases!
anecdotally for myself and tons of people on X, these charts aren’t mapping onto experience for how good gpt-5.5 is for coding and knowledge work tasks
but this makes sense! the whole point is that every eval set captures some large distribution of abilities that will never perfectly capture what you want your agents to do in production at your company + your use cases
public eval sets are a broad signal of ability, but if that eval set doesn’t capture what your team needs your agent to do, then it’s not very useful
it takes human review and effort but bespoke Evals is probably the highest leverage thing teams can invest in today to improve their agents! related is turning on Tracing so you can see what your agent is doing
It's funny how everyone's finding this out now. You easily build your own coding harness, hook it up to Opus 4.6 and get the same score as Claude Code. A lot of Claude Code's alpha is in enabling developer productivity.
Can't stop thinking about how Claude Code is in LAST PLACE on TerminalBench for harnesses using Opus 4.6.
There are TEN separate harnesses that use Opus better than Claude Code