Base model quality drives RL post-training, but existing guarantees fail to translate a good init into efficient learning. Our theory captures this and thus turns the heuristics behind modern RL objectives into actionable principles for algorithm design. https://t.co/kYT9tUbJX7
I really don’t know whats in the water fed to younger folks @OpenAI where they develop such great disdain for academics??
I see this so so often. Being so myopic is not beneficial to anyone.
It’s done! Marin’s Mochi 535B-A23B finished its main pretraining phase this morning. 18T tokens! Long context this weekend, SFT over the next week or so. Hoping to release checkpoints next week. Some EU paperwork first. https://t.co/VZeGY2yXCl
Introducing NyoomFloat12, a hardware-friendly lossless 12-bit quant from BF16 (accepted to #neurips2026)!
In BF16 LLMs four of the bits that are the same for 99.7% of the weights. So you can compress BF16 -> 12-bit with minimal overhead.
Check out @__sylvie_l__'s thread! 1/
Heading to #EMNLP2026 in Budapest 🇭🇺? Check out our Oral paper, UReason: Benchmarking Reasoning-to-Generation Alignment in Unified Multimodal Models!
🤔 UMMs unify understanding and generation. But are their text and images truly aligned?
💡 Our finding: UMMs usually get the reasoning right, but the image often doesn't follow it. Even more surprising: if we drop the reasoning and give the model only the final prompt it wrote itself, every model we tested does better, by a large margin.
📍 Oral Session 2 · Oct 25, 11:00–12:30 · Room G13-14
👇
Hi all, I have a new result I'm excited to share. It turns out that *all existing implementations* of softmax and cross-entropy (that's JAX, PyTorch, textbooks, etc) have a subtle bug --- two bugs, actually. A simple rewrite fixes both, and eliminates "slingshots" when grokking:
Rumor has it frontier labs are using looped LMs to scale quality without scaling parameters. But KV-cache memory still grows with every loop. Is that necessary?
No! Our method BeNice! unlocks near-lossless sharing of the final KV-cache across loops: more depth, same KV memory.
This lossless KV-sharing isn’t guaranteed out of the box with looped models. 👀👇for our method BeNice! to teach your model that sharing is caring!
Literary works are often translated into the same language multiple times, and each translation interprets the original in its own way.
How can we use these different translations to train better literary MT systems? Can synthetic references be as good as human ones?
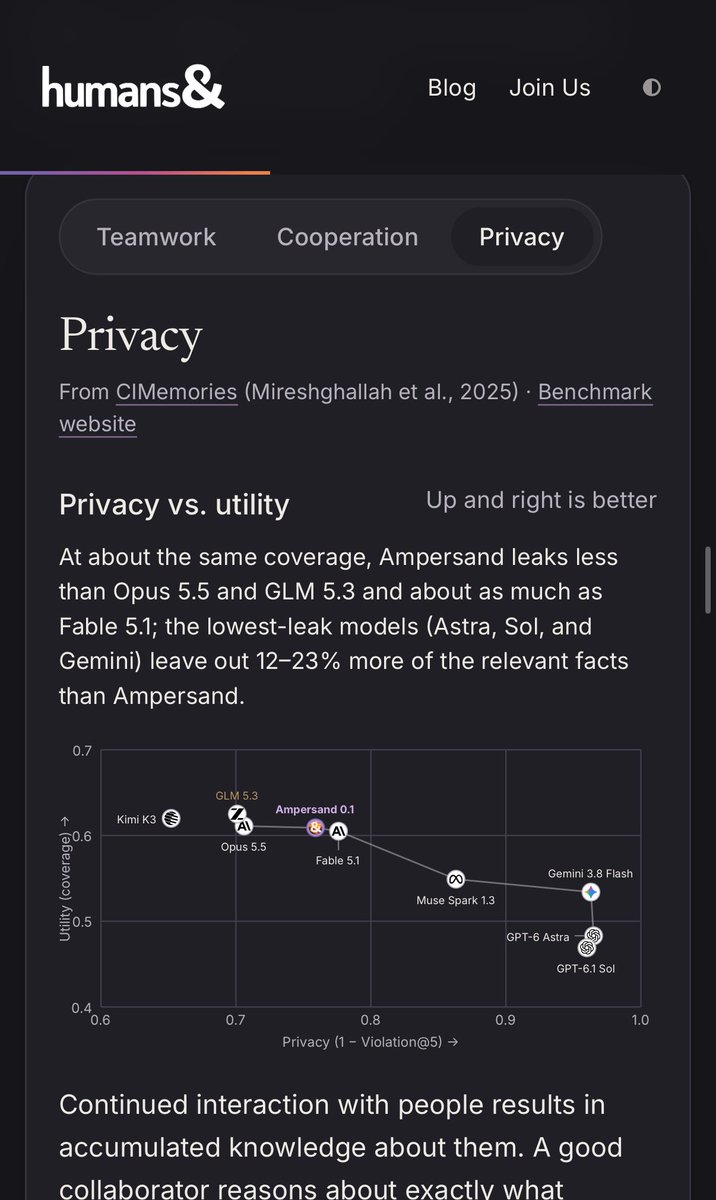
Today we release our first collaborator model @humansand! Ampersand is the first model with privacy built in (unlike most other models where privacy is an afterthought), co-designed in tandem with our product (more soon!!).
We designed our environment and simulations such that the post-training’s optimization pressure incentivizes decisions that abide by contextual privacy norms, through long horizon outs.
🚨Did you know that your coding agent is writing your code in an insecure way, leaving exploitable vulnerabilities unpatched?
@dqwang122 trained agents to be better at *secure* vibe coding
Check the preprint and thread 👇
Excited to share that our Strokes of Sonic Tradition project has been awarded a Humanities and AI Virtual Institute (HAVI) grant from Schmidt Sciences!
We will use AI to decode ancient guqin music by bridging the surviving notations and living practices.
https://t.co/rlX8VecUzc
Optimizers are usually benchmarked at one batch size, and scaling rules extend them to different batch sizes. We show: (1) frameworks to derive these rules are not as general as they claim to be, and (2) the best optimizer depends on the batch size. https://t.co/GyTvOOBJ3l
(1/7) I'd like to provide some additional context for the remarks that can be found in this interview.
(2/7) My discomfort with the attention being paid to existential risk---and with the ongoing dominance of the public discussion of such risks by a few so-called thought leaders---is that there's an elephant in the room that is being missed. That elephant is the effect of all of this discussion on young people, and indeed the effect---beginning with social media a decade ago---of information technology on young lives broadly speaking.
(3/7) I recently read an interview by Jill Lepore in which she reports on discussions that she had recently with a group of college students: "They had just three things to say. One, social media completely destroyed their childhoods. Two, AI is destroying their college education and their likely prospects for employment. And three, what the hell are we all doing?" To add a fourth bullet that I've heard in similar discussions: "I'm not going to have children, because the existential risk is just too high."
(4/7) Please contemplate such a statement, those of you who think that it's OK that the public, widely diffused, discussion coming from seemingly authoritative figures is so adamant about existential risk.
(5/7) Let me add that I have little interest in a debate about what "superintelligence" might mean, or whether we're currently seeing the emergence of superintelligence. For what it's worth, I would certainly agree that the solution of extremely challenging math problems (for example) exhibits a very impressive form of intelligence, although I would want to argue that such intelligence is impossible to dissociate from the collective of humans that provided data to the machine learning system (which itself has become a kind of collective).
(6/7) Such philosophical debates are entertaining and even important, but when they then head in the direction of "when such superintelligence emerges, there's a good chance that it will want to kill all humans", I say "science fiction". Again, I don't think that it's bad to consider such thoughts, but I strongly believe that it's bad for society, and especially young people, for such thoughts, unaccompanied by any serious real-world analysis, to become a dominant form of discourse of the era.
(7/7) We are damaging human lives, and the consequences of that damage will no doubt be a major theme of the next several decades.
Michael I. Jordan, machine learning demigod, UC Berkeley
... the young people who work at these companies operate in a world [Silicon Valley, Berkeley, etc.] where these kinds of discussions are commonplace. Many of them aren’t really engineers; they come from the humanities, philosophy, or other disciplines. They’re 25 years old, they’re naive, they don’t do engineering work, they’ve never worked at large companies where real products are developed for real people, with discipline. And they get together, a bit like in Parisian cafés in the 1920s, to talk about these grand science-fiction ideas. When these young people resign, they know they’re going to attract attention. It allows them to feel virtuous and to be seen as very important figures. They claim to be giving up money, but in reality, they already have their stock options. So all of this is a grand moralizing performance that doesn’t serve the real objective it claims to pursue. There’s a great deal of naiveté here, which goes hand in hand with a certain cynicism…
https://t.co/GwP9zcz7vZ
We’re Marin, the details are pretty much always available!
https://t.co/zxTopIC124
This time we’re deploying Triton router top-k and short conv, leaner ragged a2a transport, fused expert backward, and XLA scheduling fixes