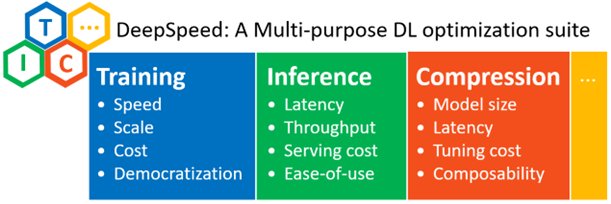
🎤 Meet keynote speaker Zhipeng Wang (@PKUWZP), Senior Staff Software Engineer at @Google and DeepSpeed maintainer. https://t.co/yTawLTBbd6
At #PyTorchCon North America, he’ll share advances helping DeepSpeed train large models efficiently across diverse hardware.
October 20-21 | San Jose
Register:
https://t.co/1z0jDhdUZm
@ezyang@StasBekman Edward, thanks for the write up. My offloading experience aligns with the key points. However, the doc affirms cuda-specific, and user control limitations. I agree that current torch works for most use cases.
@StasBekman@ezyang Edward, I found some documentation that suggests deleting the tensor will force unpinning. Is that correct?
We would also prefer to use PyTorch API directly. Thanks!
The meeting link for tomorrow's DeepSpeed developer meetings is now available:
Aug. 7, 9:00 a.m. PT — DeepCompile efficiency & robustness
Aug. 7, 10:00 a.m. PT — Expert Parallelism enhancements
Everyone interested is welcome to join!
https://t.co/pbOJR8APE2
@siddharth_3773@StasBekman It is neat to see how to preserve vmem mappings across the phy mem release/reclaim. I have a question.
For offloading (and reloading), it seems you would need to use enable_cpu_backup mode
https://t.co/Q4EU1KXs3y
The PyTorch Foundation continues to grow as a multi-project home dedicated to supporting collaboration across every stage of the AI lifecycle.
We are excited to launch a new quarterly blog series where each hosted project - PyTorch, @vllm_project@DeepSpeedAI@raydistributed, Helion and Safetensors - shares its latest updates, technical progress, and roadmap. From core framework optimizations and hardware enablement to overall ecosystem health, our hosted projects achieved a lot over the past quarter.
Read the complete update to learn more 👉 https://t.co/fF6wiMKymw..*
We will host our monthly Office Hour for DeepSpeed users on July 28th, 9AM PT. Feel free to join and discuss any topics ranging from issues to roadmaps. Zoom link: https://t.co/3JY7GPs8Ub
PSA for @DeepSpeedAI users - a long outstanding precision-related critical bug has been identified and fixed in https://t.co/ZmMldAdWww and a new release has been made.
The issue was about mixed precision mode downcasting buffers that had to be in fp32 - massively impacting correctness due to large static buffers - e.g. RoPE in Qwen3 models when using long sequence lengths 32K+.
Hopefully this fix brings Deepspeed to a close parity with FSDP2 which has been an issue since a long time.
You can still have the old behavior but you'd now need to manually configure it - by default the model's buffers will now remain in the original precision.
Please install deepspeed==0.19.2 which will do the right thing.
Thanks to Tunji Ruwase and Claude Opus 4.8 via Cursor for identifying and fixing the problem.
We now have native support for all ZeRO stages 1/2/3 for Muon Optimizers, providing superior performance on LLM pre-training and post-training. Feel free to try it out, kudos to @PKUWZP Guokai Ma, Peng Du and Chi for the contribution!
DeepSpeed now supports the Muon Optimizer.
Optimized specifically for internal 2D weights within neural networks, Muon is gaining traction for its significant memory savings and strong convergence metrics during LLM training.
In our latest blog post, the DeepSpeed team shares a deep dive into their integration setup, implementation of hybrid optimizer strategies, and early benchmark results. @PKUWZP
Read the full technical breakdown here 👉 https://t.co/t7JxOqkM6S
Reminder to join our DeepSpeed Office Hours on Tuesday, May 26 at 12:00 PM America/New_York. We'll cover general questions, Q2 roadmap progress, and requests for Q3. Everyone is welcome!
Zoom:
https://t.co/3JY7GPs8Ub
Don't miss @DeepSpeedAI virtual office hours on May 26 at 12:00 PM America/New_York to ask questions of @toh_tana member of DeepSpeed TSC & get the latest recent key updates, including AutoSP (sequence parallel), AutoEP (expert parallel), and AutoTP (tensor parallel).
@ten3br1s@PyTorch Thanks for the feedback. We don't know of multi-node issues. Our original deepcompile blog had multi-node results: https://t.co/g5OUWuJqHE
We will investigate if you could please open a ticket or provide more details.
Want to train LLMs on longer contexts without re-engineering your entire systems stack?
Introducing AutoSP — the first compiler-based solution that automatically optimizes LLM training for long contexts. Under the hood, AutoSP applies a series of compiler passes that trigger sequence parallelism, paired with a curated activation-checkpointing scheme tailored for long-context training. It's integrated directly into DeepSpeed, so enabling long-context training is just a config change away.
No more rewiring your stack to push context lengths. Read the blog to learn more 🖇️ https://t.co/TMjWfsO8fy
✍ @AhanGupta13, Zhihao W., Neel Dani, @toh_tana, Tunji Ruwase, @_Minjia_Zhang_
#PyTorch #DeepSpeed #AutoSP #OpenSourceAI
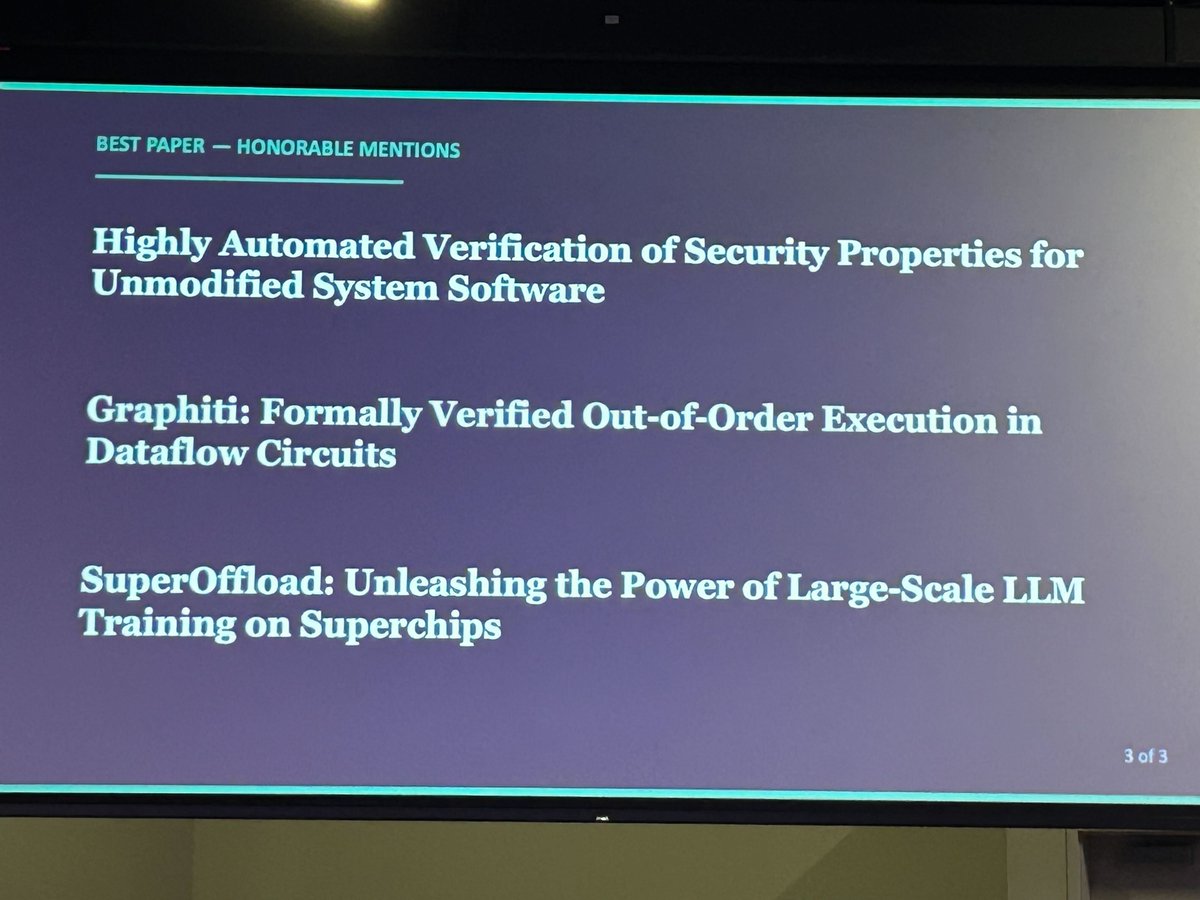
Excited to share that our work SuperOffload received an Honorable Mention for the ASPLOS 2026 Best Paper Award 🎉
Proud of the team for pushing forward system design for large-scale AI. Xinyu gave a great talk presenting the work. In addition, it was also wonderful to spend time with collaborators and the broader community.