Learn how to productionize large language models using distributed post-training and inference optimization techniques. Participants will explore advanced LLM post-training techniques, including agentic reinforcement learning with SkyRL.
Hands-on topics include:
- Intro to LLM post-training
- Intro to RLVR (with GRPO)
- Recent development of LLM post-training:
- On-policy distillation (OPD) and Multi-teacher On-policy distillation (MOPD)
- Case study: Post-training a terminal agent
- Building evals
- Building custom environments
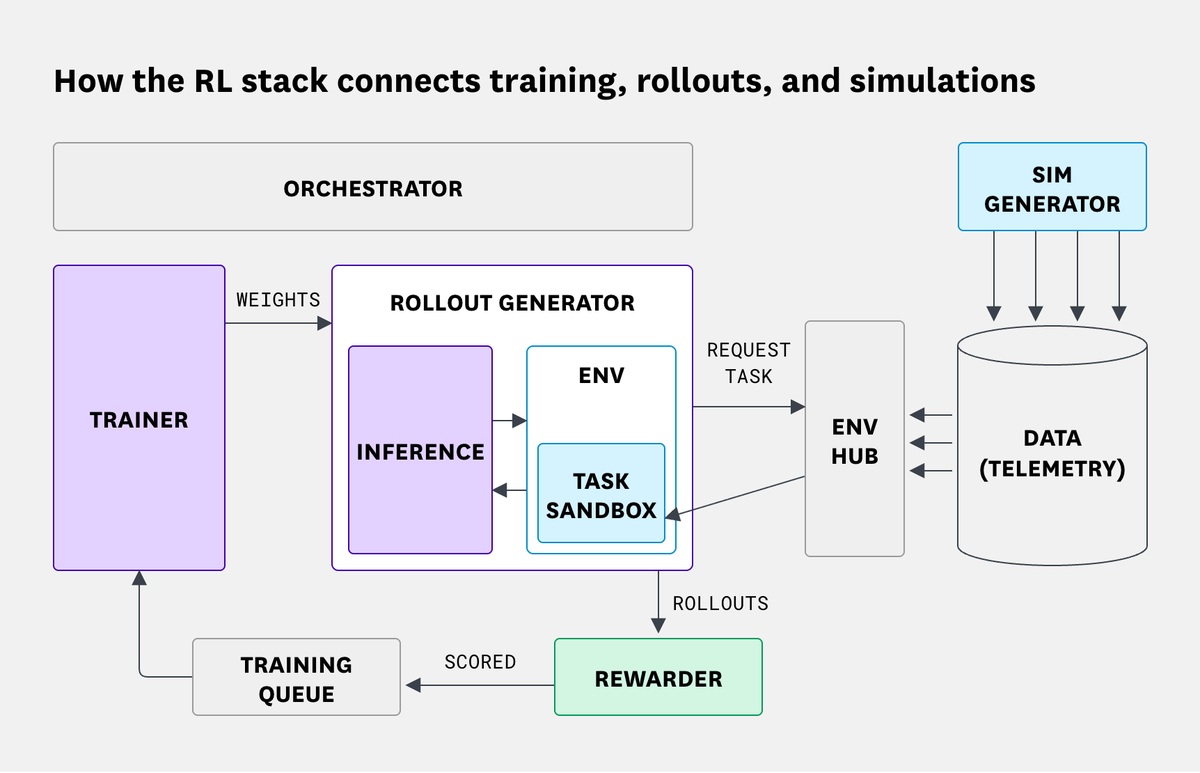
- RL systems
- Demo walkthrough
- Intro to SkyRL
- Full Async RL with SkyRL
- Performance monitoring and tuning for RL rollouts
Register: https://t.co/jSyIouwg97
When one region runs short on GPU capacity, @ChefRobotics jobs on Anyscale try others automatically until one comes through, instead of risking days without H100 access.
See how the team scales robot training: https://t.co/R0N0TIM49t
Super excited to share some of the work I’ve been doing on supporting 1M token context training on SkyRL for GLM 5.3 Flash, 64x higher than the out of the box Megatron baseline! 🚀
This work was done in collaboration with the amazing folks at @LilaSciences! 🤩
Getting there took key algorithmic and systems optimizations in four main areas:
1) DeepSeek Sparse Attention: run DSA on a sparse kernel; chunk and shard its quadratic indexer.
2) Activation recompute and offloading: recompute activations in backward and offload saved inputs to CPU.
3) Context parallelism: split each sequence across GPUs, with new CP support for KDA and a fix for DSA.
4) Avoiding unnecessary precision upcasts: keep FP32 copies out of memory and off the network.
For more details on our implementations and our results, check out our full technical blog here: https://t.co/Dna0CGNeJt!
This work benefited from the contributions of many people along the way. Big thanks to @pcmoritz, @erictang000, @sumanthrh, @CyrusHakha, @richliaw from @anyscalecompute and Keith Truongcao, Tushar Khot, Vivek Subramanian, Semih Kara from Lila Sciences for all the help and guidance!
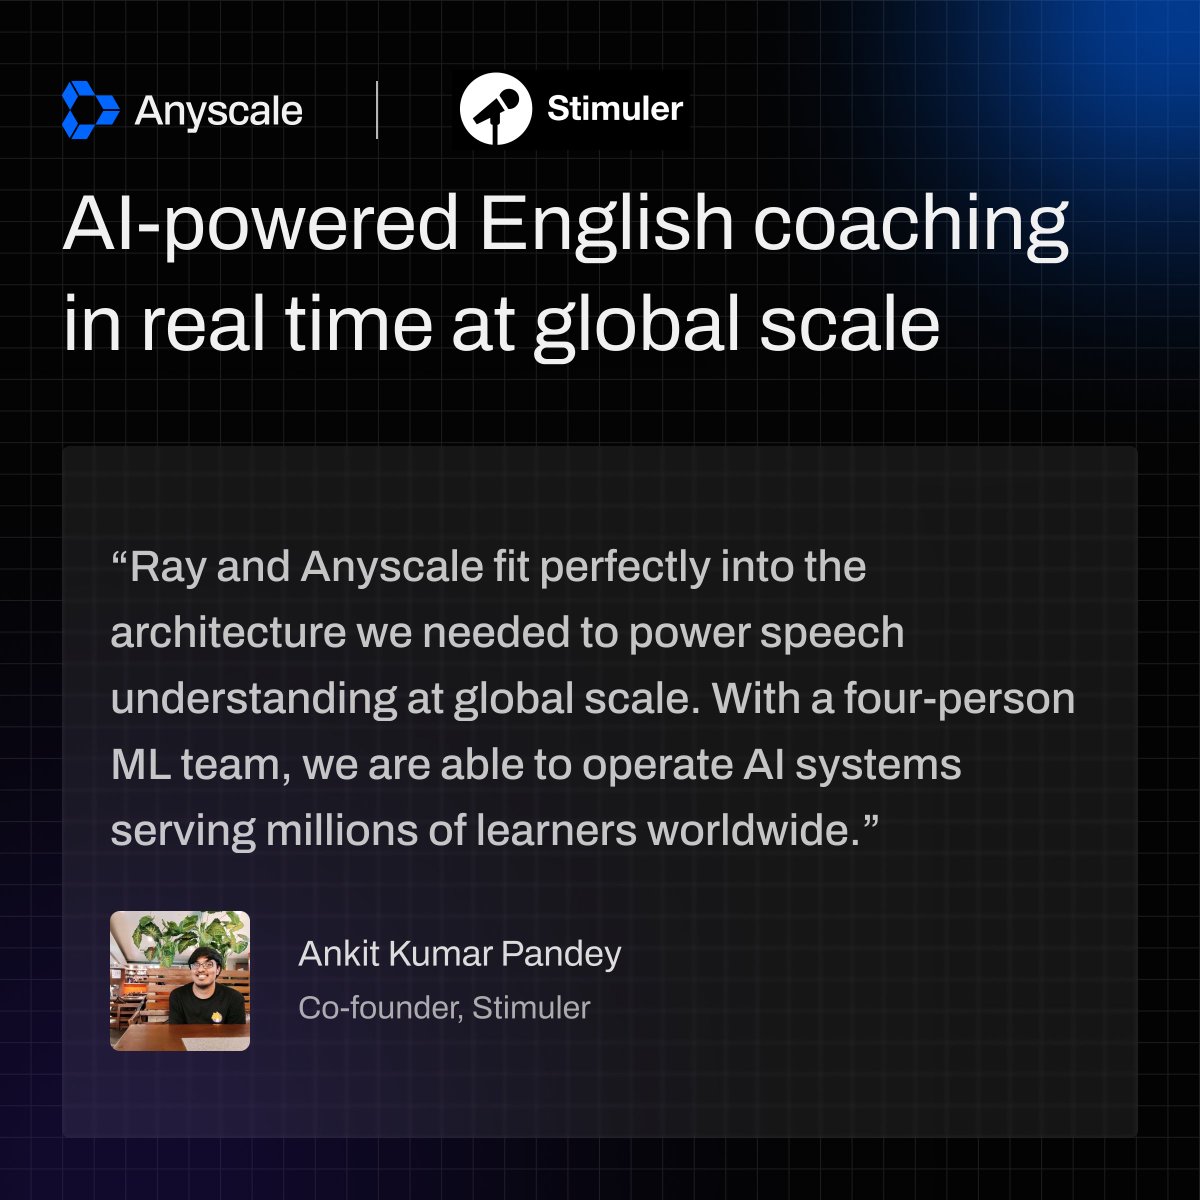
@StimulerApp runs 4 AI models simultaneously for every English coaching session.
Speech understanding. Assessment. Proficiency tracking. Speech generation.
Each fires at a different rate. Each needs its own compute. One three-person ML team runs it all.
900K+ speeches a day on Ray and Anyscale
Case study: https://t.co/mtJ4ZrKG3x
In this session, @Marwan1112, AI Engineer at Anyscale, will walk through:
- Building Ray Serve applications with deployments, composition, and load-aware request routing
- Deploying and scaling LLM endpoints with Ray Serve LLM on engines like @vllm_project and @sgl_project
- Optimizing the inference engine with the KV cache, paged attention, prefix caching, and continuous batching
- Scaling frontier models with KV-cache-aware routing, prefill/decode disaggregation, and wide expert parallelism for mixture-of-experts (MoE) models
- Deploying Custom LLMs on Anyscale and Integrating Them with Agentic Platforms (Claude Code, Cursor, Codex)
- Comparing costs across self-hosted GPUs, subscriptions, and token-based API billing.
Register: https://t.co/uKeb1R6hQ5
Kubernetes doesn’t know what a Ray cluster is. So teams keep hand writing the same Deployments, Services, and recovery scripts to run Ray on it.
KubeRay fixes that: autoscaling, fault tolerance, and zero downtime upgrades for Ray, built into Kubernetes.
https://t.co/lsCVNvdCEM
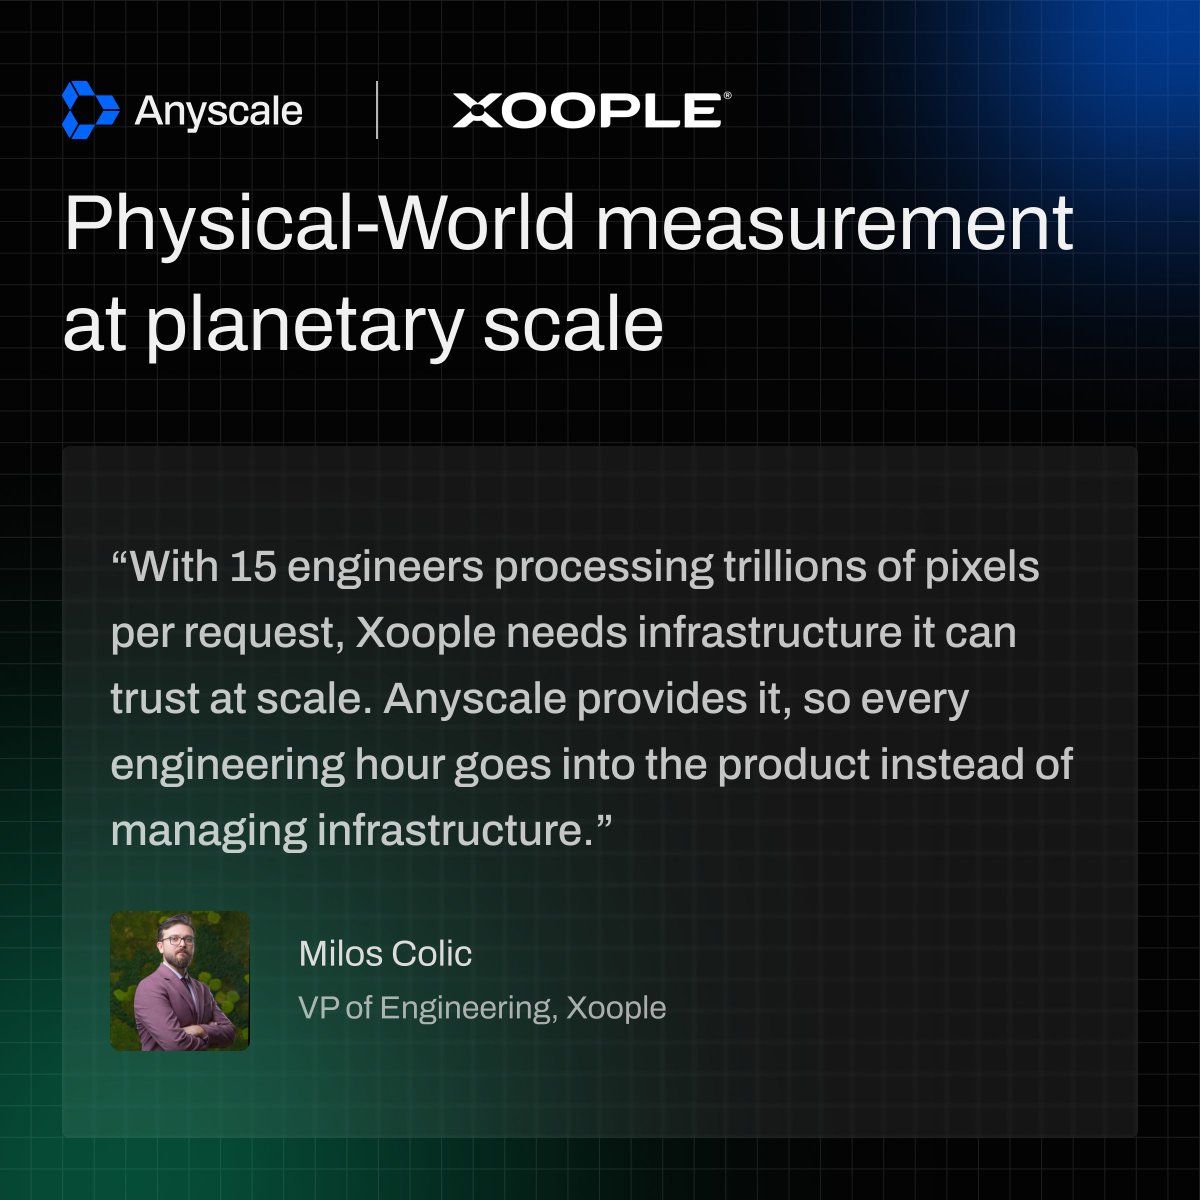
@Xoople processes 500,000 km² of satellite imagery in under 5 minutes on 12 A10 GPUs with Anyscale on @Azure.
A single request can fan out to 2 trillion pixels. 15 engineers without a dedicated infra team.
Read the case study: https://t.co/3ULVVpv2Au.
Heading to @PyTorch Conference next week?
☕ Come hang at the Coffee Club with the teams behind Ray and vLLM, two key projects under the PyTorch Foundation. Hosted by Anyscale, @Inferact and @Nscale.
Request your spot here:
https://t.co/SpcPP9d3g3
Open Source AI Week kicks off tomorrow 🎉
📍 The Midway, SF, 6pm 👇
https://t.co/pBRKNrUEoU
Join us alongside other key players in AI helping organizations adopt and scale their use of open-source.
We post-train GLM-5.3 Flash in a sandbox that reproduces the Bits Investigation tools over archived scenario data.
Our async RL stack is based on #SkyRL, with efficiency and reliability enhancements in our internal fork. Training and inference run concurrently, with a staleness budget for off-policy updates.
datadog ai research used SkyRL to post-train GLM 5.3 Flash to perform at the pareto frontier for their SRE eval
@bthecohen and team were some of the earliest users of SkyRL at scale, really cool to see these results finally out! great tech report as well
Datadog post-trained GLM-5.3 Flash via RL on real-incident sims. Matches frontier SRE performance at much lower cost.
Their RL stack is built on top of SkyRL! Check out the technical report https://t.co/NdU5WngeVh
@ChefRobotics trains the Vision-Language-Action models behind its food assembly robots 10x faster on Anyscale, with 92% scaling efficiency across multi GPU runs on 16 A100s.
Read the story: https://t.co/J6B07IbV9f
@Coinbase is building an agent-first ML platform where AI agents watch model performance and trigger retraining on their own.
Aman Choudhary on how Ray on Anyscale helps them run up to 1 billion inferences a day
https://t.co/hBV79x6afa
We’re joining Open Together with @huggingface and friends this Friday to support everyone building AI with open-source
SF, Oct 16, 6pm 👇
https://t.co/WSgYf8x5cK
Our upcoming webinar will cover how to design scalable distributed inference systems for production AI applications, from classic ML models to large language models.
Learn how Ray Serve delivers high-throughput, low-latency serving, and how to evaluate the performance tradeoffs in autoscaling, batching, routing, and inference-engine optimization.
Topics include:
- Building Ray Serve applications with deployments, composition, and load-aware request routing
- Deploying and scaling LLM endpoints with Ray Serve LLM on engines like @vllm_project and @sgl_project
- Optimizing the inference engine with the KV cache, paged attention, prefix caching, and continuous batching
- Scaling frontier models with KV-cache-aware routing, prefill/decode disaggregation, and wide expert parallelism for mixture-of-experts (MoE) models
- Deploying Custom LLMs on Anyscale and Integrating Them with Agentic Platforms (Claude Code, Cursor, Codex)
- Comparing costs across self-hosted GPUs, subscriptions, and token-based API billing.
Register: https://t.co/NIFhcVRYlS