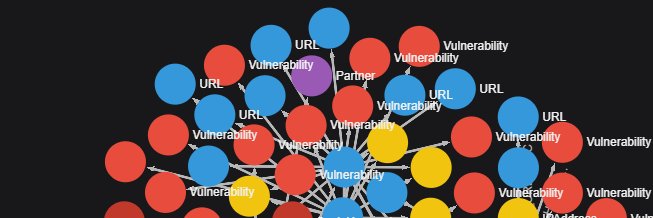
Every AI hackbot fails in production. Nobody wants to talk about why.
It's never the exploitation. It's auth, session handling, rate limits, scale. The session dies at hour three, the agent never notices, and it spends all night attacking a login page it was locked out of.
Pentest Copilot Enterprise, out of private beta today. Self serve, dedicated tenant, or on prem.
@buccocapital Amazon won’t be able to tell whether the buyer is a human or an AI acting on their behalf if access is via the user’s IP address & cookies
if anyone has tried to get codex to solve captchas, it's practically impossible. if you reverse codex you can see OpenAI has gone above and beyond to make solving captchas impossible. If i am asking it do it, why is it that i get a refusal here?
@JubbaOnJeans@championswimmer I wonder if the govt's push for a separate app for every single service still makes sense.
A unified app + exposed api would do wonders. + a citizen agent that @raskarmit is working on would basically make the country viksit bharat
@8teAPi - smart people will continue frontier research at 10x scale/ambition with AI
- smart people will understand fundamentals/explore the process REGARDLESS OF KNOWING SOLUTION
- we honestly don't need so many phds
@harshilmathur@typesafeai You're right in that you need a perfect eval before you make the switch. In practice I'd be extremely unsure if that becomes the case. rn for simpler tasks, I have a reasoning I can use to debug wrong decisions. With a prob distribution output thats lost, trusting model fully.
hybrid jev/llm implementations don’t make much sense. for example, in a state space search, suppose you rely entirely on jev and invoke the llm only after several steps for validation. if the llm reveals that you’re not on the optimal path, you have to backtrack, wasting work and potentially making less progress at a higher cost than if you had used an llm call at every step(which can also reason/look-ahead giving you a wayy better path).
only use jev if its evals are perfect on your internal benchmark (which means your task was kinda easy all along, you're just switching for the speed - which is very legit)
Okay, everyone wants us to give the unbiased facts.
Jev compaction here has a lot of problems. The biggest problems:
- When I ran it on our public compaction eval (that you can run too), it resulted in a programmatic rule, that you dont need any Jev or other model for - it simply removed all tool calls from the chat history
- This means you could do it for free, first of all, but second of all, it means you run into a viscious cycle.
Every compaction, there are less and less tool calls to remove from the chat history, meaning it compacts less and less tokens, until there is no room for compaction, and you hit a hard stop, and can't compact anymore.
- And, if you are cycling like this, every compaction breaks your cache, so you're paying 10x the price on input tokens, and keeping more input tokens each round means a higher baseline cost after compaction as well.
Here's the full reproducible eval that you can run against Hermes Agent between the two (Hermes' vs Jev's):
https://t.co/0vJV5u10Cn