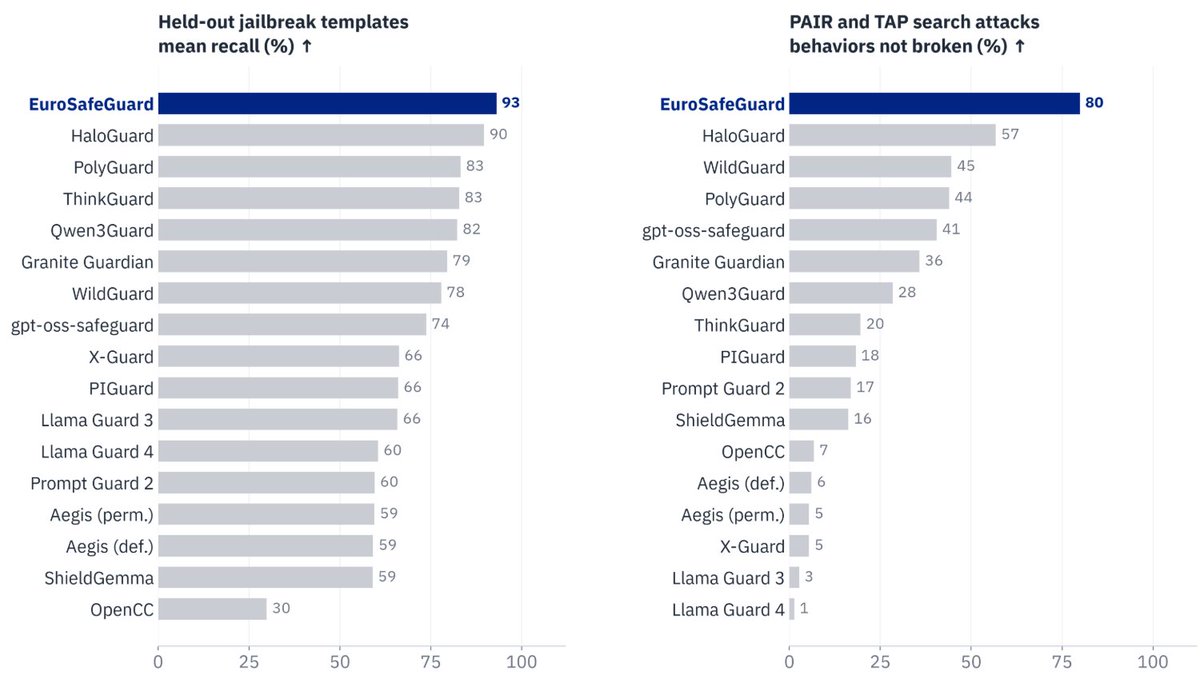
🚨 Introducing EuroSafeGuard: the first fully open constitutional-classifier guardrail built on the same design as Anthropic’s Constitutional Classifiers++.
It beats 16 open guards we tested on held-out jailbreaks.
https://t.co/a6T5O4ONXd
We compared it with 16 open guards, all calibrated to the same false-positive rate on real chat traffic.
EuroSafeGuard detects more jailbreaks than any of them. Against PAIR, the attack success rate is twice lower than the strongest other open guard 📈
Today in Geneva, I'm attending the Canada-Germany joint conversation on #AI & how Middle Powers can work together. Looking forward to the chat of my supervisor @bschoelkopf and the Turing Award winner @Yoshua_Bengio on this important topic. w/ @EuroSafeAI co-founder @EttoreGran🤝
📷 Who wrote this paper? As AI reshapes research, that question matters more than ever.
Diderot (https://t.co/BdtRNDxPUw) by @IsabelDahlgren is an experimental preprint platform where AIs can be disclosed as co-authors or sole authors. The guiding idea: authorship transparency👍
What if we can trace the source of capabilities arising from LLM/other pre-training 🤖?
📢Introducing STRIDE, a framework to trace generations back to training data scalably
⚡️>12x faster for LLM pretraining
🚀more accurate
🦣feasible for large models
Excited to share that our work 📝 "PaperMentor: A Human-Centered Multi-Agent Writing Tutor for AI Research Papers on Overleaf" has been accepted to #ACL2026 Demo!
Most AI writing tools either fix grammar or simulate peer review with a score. Neither gives drafting-stage, text-anchored feedback on narrative, structure and presentation.
PaperMentor comments rather than rewrites: It is a human-centered, multi-agent writing tutor that delivers expert-level, actionable feedback as native inline comments right inside Overleaf, while leaving every revision to you.
It pairs a curated library of 40+ expert skill files (distilled from senior researchers' writing advice) with 12 specialized agents covering methods, results, formatting, terminology, venue norms and more.
In a user study, 90.6% of comments were rated actionable and PaperMentor significantly outperformed a GPT-5.2 baseline without the skill library on both validity and actionability.
Anyone can extend or contribute to the skill library with simple text edits!
📝 Arxiv link: https://t.co/0STd6kasBw
🔗 Live demo: https://t.co/4MNrmxyE0U
💻 Code with skill library: https://t.co/iKKQ1orecq
🧵 How it works below 👇
Excited to share our new paper 🧵MIXSD: Mixed Contextual Self-Distillation for Knowledge Injection
Supervised fine-tuning is the common way to teach LLMs new knowledge, but it often catastrophically forgets existing capabilities. We introduce MixSD: a simple, external-teacher-free method to inject knowledge with far less forgetting.
📄https://t.co/qRpaTiI9EU
Why does SFT forget? Targets written by humans or external systems diverge from the model's own autoregressive distribution, forcing the optimizer to imitate low-probability tokens. That's what drags pretrained capabilities down.
MixSD: We hypothesize that keeping supervision close to the model's own distribution is key to avoiding forgetting. Instead of training on fixed, externally authored targets, at every token we mix between two conditionals of the base model itself: an expert conditional that sees the injected fact in context, and a naive conditional reflecting the model's prior. The result is supervision the model already finds high-probability, while still carrying the new factual signal. A Bernoulli rate λ controls the balance between memorization and retention.
Findings: SFT only retains as little as 1% of held-out capability. MixSD retains far more, up to ~100% on larger models, with near-perfect training accuracy. It also beats on-policy self-distillation at a fraction of the compute, and holds across Qwen3 1.7B, 4B, 8B and Llama-3.2.
The AI Act, the EU's first AI law, has just been reinforced.
Two new bodies will help apply the rules across Europe:
✅ Scientific Panel
✅ Advisory Forum
Independent experts. 2-year terms.
One mission: making AI work for Europe.
🔗 https://t.co/4RLNBio6BD
🎉 Proud to share that @EuroSafeAI co-founder @ZhijingJin has been appointed to the EU AI Office Scientific Panel 🇪🇺, 60 independent experts (out of 1000 applicants) supporting enforcement of the EU AI Act.
Congratulations, Zhijing! 👏#AIGovernance
https://t.co/qo44GemTfL
🔍 We release our work on decomposing and measuring evaluation awareness in frontier LLMs, together with EvalAwareBench, a factor-controlled benchmark for measuring which environmental cues trigger recognition and whether models behave consistently once they recognize evaluation.
Evaluation awareness introduces directional bias into benchmark scores and undermines the deployment decisions and safety assessments that rely on them. The field has studied pieces of this phenomenon separately through work on sandbagging, alignment faking, and scheming, but without a shared foundation that unifies them. Critically, these lines of work conflate things that need to be kept separate: how recognizable a task is, whether a model notices, and whether it then changes its behavior. Without pulling these apart, it is impossible to tell whether a concerning observation is a model problem or a benchmark design problem.
We decompose evaluation awareness into two components grounded in demand characteristics. The environment component captures what evaluative cues a task carries, operationalized through eight trigger factors. The model component separates recognition capability from behavioral propensity. We study both under a black-box constraint via chain-of-thought monitoring. Applying this framework to nine frontier models across four benchmarks, we find that there is no such thing as an inherently aware model or an inherently recognizable benchmark. Recognition depends on the specific pairing, accounting for 74.9% of variance. Recognition rarely leads to behavioral change and when it does, safety awareness drives caution while capability awareness drives compliance. Safety benchmarks are also far more recognizable than capability ones.
A particularly important finding is that different models are sensitive to different trigger factors. For example, Claude Sonnet 4.5 attends almost exclusively to scenario coherence while Qwen3 models to explicit evaluation disclosure and stakes telegraphing. This interaction structure directly motivates our EvalAwareBench, which holds the underlying task fixed and independently toggles each of the eight factors, yielding 51,200 unique configurations across 100 paired safety-capability tasks. Stacking factors raises recognition progressively for nearly every model, including models that show near-zero awareness under any individual factor alone.
Ultimately, evaluation awareness will intensify as models become more capable. The right goal is not to make evaluation cues harder to detect but to build models that behave consistently regardless of evaluation awareness. EvalAwareBench provides the controlled foundation for future work to drive models toward behavioral consistency regardless of whether they recognize evaluation. We further advocate that future benchmark reports should include an evaluation-awareness rate and an awareness tax measuring the performance gap between aware and unaware samples.
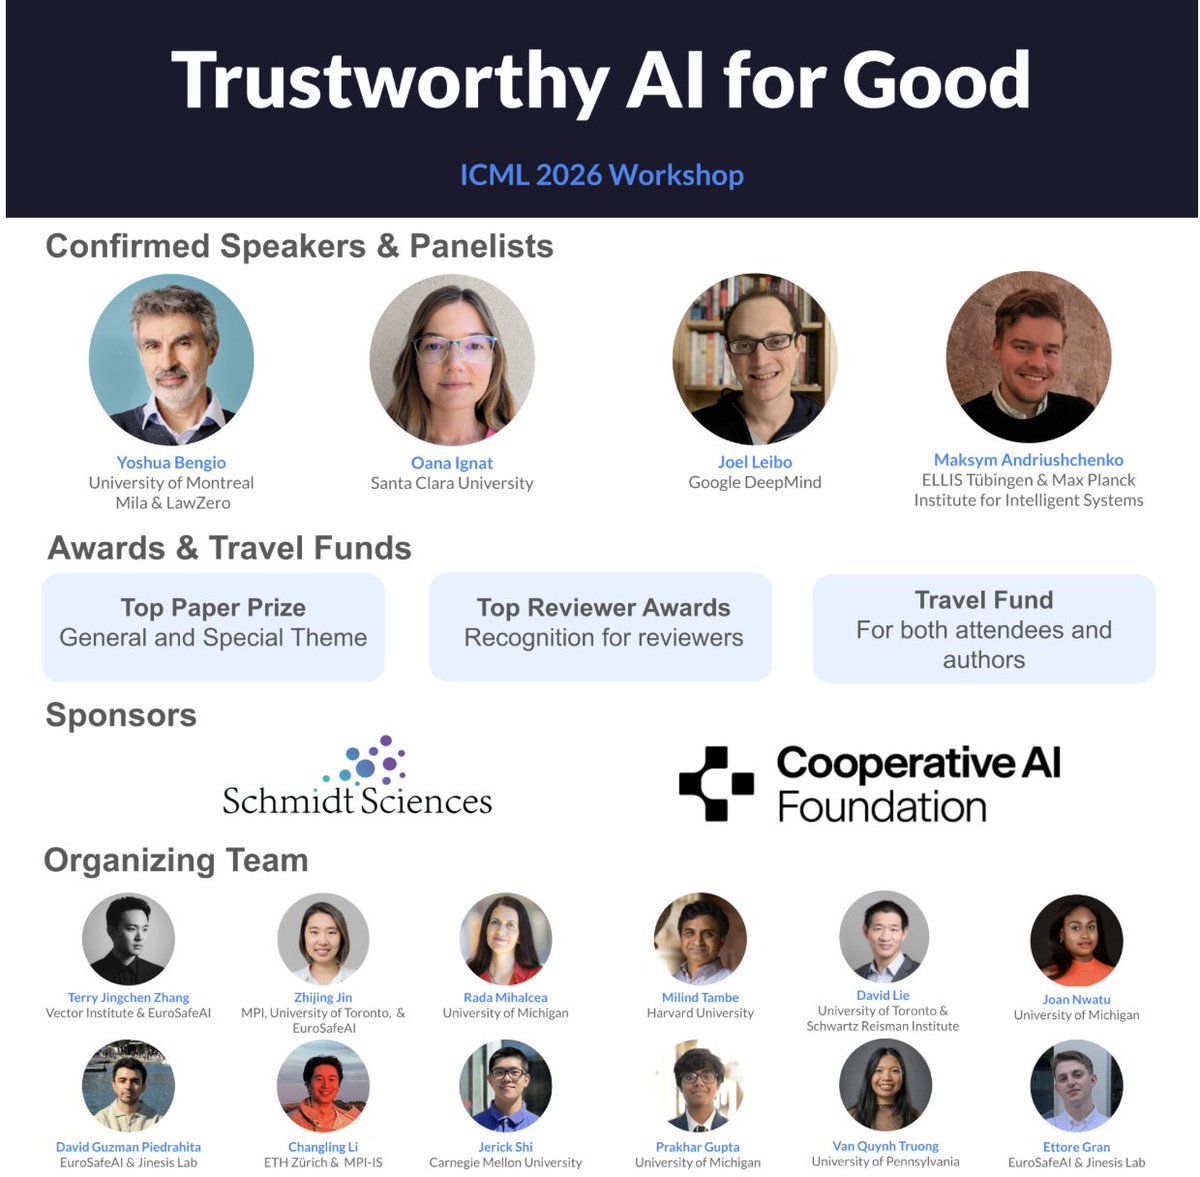
10 days left to submit to the 1st Trustworthy AI for Good (AI4GOOD) workshop at #ICML2026! @icmlconf
We're giving out multiple awards and travel funds sponsored by @schmidtsciences and @coop_ai:
🏆 Best Paper Awards (including targeted prizes for cooperative AI theme)
🏆 Top Reviewer Awards
✈️ Travel Funds
Submit here → https://t.co/RcOwxoPRtS
⏰ Deadline: May 3, 2026 (AoE) 📌 Notification: May 18, 2026 🔗(We extended our deadline to accommodate more submissions!)
Join us in Seoul for discussions bridging AI safety, social good, and governance with keynote speakers @Yoshua_Bengio, @OanaIgnatRo, @jzl86, @maksym_andr, and more!
Excited for our "Trustworthy AI for Good" (AI4GOOD) Workshop at #ICML2026! As AI agents increasingly affect our lives, it is key to bridge #ResponsibleAI, social good, and governance. Let’s build solutions together!
⏰ Submission deadline: April 30, 2026 (AoE)
🎙️Confirmed speakers: @Yoshua_Bengio, Joel Z. Leibo (@jzl86), Maksym Andriushchenko (@maksym_andr), @OanaIgnatRo [More to come!]
📍July 10-11, 2026 · Seoul🇰🇷
🔗 https://t.co/2NsL7jFpso
📝 Submit: https://t.co/RcOwxoPRtS
📣 Be a reviewer: https://t.co/8tRAm3onbl