Huge congrats to @cognition for taking the #1 spot on #SREGym! 🎉
It’s been incredible to have a front-row seat to the progress in AI SRE. Shoutout to @anhangz, @yunpark93, and @jake_rachleff for an amazing release pushing the frontier of autonomous incident response.
One step closer to a world where humans don't have to be on call. 🚀
SREGym 1.1 is out now, with 2.0 on the way to push the frontier even further.
📊 Follow the progress: https://t.co/o7vnYQJeTn
📝 More on Devin Oncall: https://t.co/IC1xi7OmJx
Introducing Devin Oncall: Devin automatically investigates alerts and bugs, helping your team diagnose and resolve production incidents.
Devin Oncall already handles thousands of alerts every day for some of the world’s largest companies. Let it become your SRE today.
WoWWW This is dope! The Outlook/365 outage represents some of the most complicated failures in distributed cloud services and being able to turn it into a benchmark problem for eval is AMAZING!
Great job, @HacksonClark and the #SREGym team!
Always love seeing new SRE models and agents (congrats on the launch)!
One thing that would help the community is testing on open, reproducible benchmarks alongside internal evals. When results can be independently verified, great work gets the recognition it deserves.
Colleagues at @cognition@datadoghq@NOFireAI@RadarK8s and many others have set great examples by evaluating on public benchmarks like #SREGym. Would love to see how SRE-1 perform on #SREGym — excited to follow along!
Did your email go down last week? This latest Microsoft outage was rather wild. It's starting to feel like the world is imploding. The central premise of #SREGym is to see if AI can stop such outages.
As a sneak peak of SREGym 2.0, we've recreated the Outlook outage. Check it out: https://t.co/Tp6E4nsSKD it's currently very challenging for frontier models.
What other outages would you like to see?
Stay tuned, we have something coming after Thanksgiving 🦃
The pre PIR of the Outlook/Microsoft outage has much more clarify. Thank you @Microsoft !
The outage is indeed a very hard one; many unfortunate events occurred at the same window.
A latent bug exhausting CPU/memory under specific load condition was deployed worldwide, with no impact for 3 months. The bug was triggered by a surge in load, caused by an unrelated failover of Teams and another unrelated loss of 14% of server capacity. The system is then badly overloaded; 80% of servers were unresponsive. Then, the isolation mechanism between fault domains didn't work (it was vague in the PIR), causing cascading failures till a global outage.
Then, the (likely automatic) recovery unsurprisingly hit the classic thundering herd effect.
In this case, root-cause analysis is on the critical path and it took more than 15 hours to figure out the latent bug and revert it (it's really a very nasty bug!)
The long recovery time is quite understandable. Given such a global outage, it has to be paced carefully.
I downloaded the report at,
https://t.co/KgMp7URZwf
We’re releasing Multi Agent Coordination Bench, a benchmark of twelve natively multi-agent long-horizon tasks that measure the coordination capabilities of frontier models.
We find that current frontier agents coordinate poorly. A team of eight agents beats a single agent, but the gain comes from having more agents, not from coordination. Of Opus 5.5, GPT-6.1 Sol and Gemini 4 Argon, only Opus shows signs of a gain from coordinating.
I'm asked by the media about what's behind the wave of global outages from #Microsoft, #FAA, #Chase, #UA, etc. To me, what they have in common is that these outages barely had anything new or interesting – the root causes are so textbook and mundane, and their manifestations are unfortunate, but not unexpected. None was about cyberattack. I can hardly claim a black swan.
We may have to realize that our daily life still relies on "boring" traditional systems (CPU, OS, telecom network, and mail server). Hard problems like resource management, metastable behavior, overload protection, and even software bugs are still largely unsolved, and unlikely to disappear, even with stronger AI/LLM.
Speaking of AI, I'm in fact curious about the role AI played in these outages:
* Are the bugs in AI-generated code?
* Did AI help diagnose and mitigate these failures?
* Did AI investment push away engineers who could better handle these failures?
We may never know the answers.
While we are looking forward to AI-driven systems, self-evolving agents, world models, etc., we may not want to stop investing in fundamental systems research and hardcore system engineering.
// I'm also asked a lot about formal methods. I love it, but there's no silver bullet.
The pre PIR of the Outlook/Microsoft outage has much more clarify. Thank you @Microsoft !
The outage is indeed a very hard one; many unfortunate events occurred at the same window.
A latent bug exhausting CPU/memory under specific load condition was deployed worldwide, with no impact for 3 months. The bug was triggered by a surge in load, caused by an unrelated failover of Teams and another unrelated loss of 14% of server capacity. The system is then badly overloaded; 80% of servers were unresponsive. Then, the isolation mechanism between fault domains didn't work (it was vague in the PIR), causing cascading failures till a global outage.
Then, the (likely automatic) recovery unsurprisingly hit the classic thundering herd effect.
In this case, root-cause analysis is on the critical path and it took more than 15 hours to figure out the latent bug and revert it (it's really a very nasty bug!)
The long recovery time is quite understandable. Given such a global outage, it has to be paced carefully.
I downloaded the report at,
https://t.co/KgMp7URZwf
1/5
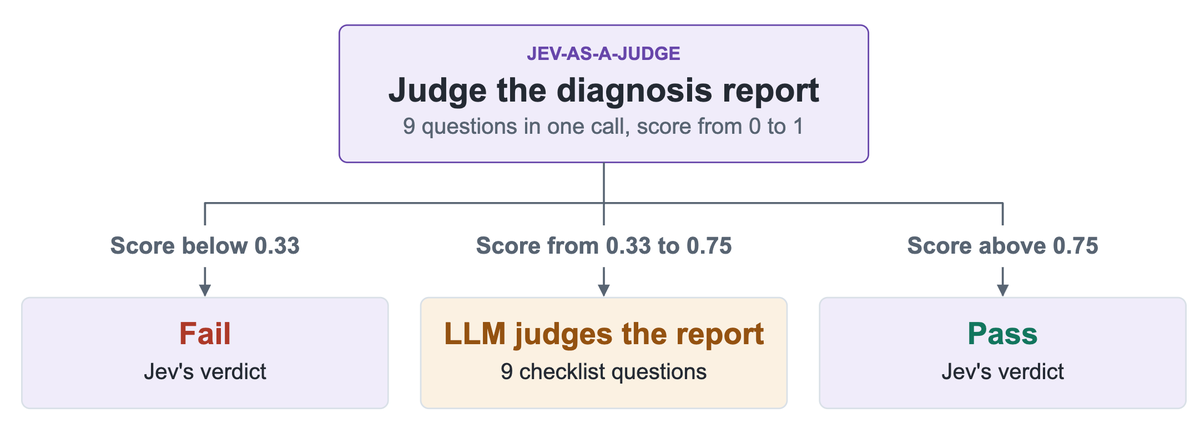
In our previous two studies, we explored how decision models like Jev could diagnose SRE incidents, and how LLM review could improve their results.
This time, we shifted our focus from diagnosing SRE incidents to evaluating diagnosis reports with Jev-as-a-Judge
. @YukunHeZS and co are doing #Jev for SRE on steroids.
This time, it's "Jev-as-a-Judge for SRE" where they followed the practice of using decision models for evals by @HamelHusain and @doesdatmaksense and wrote a cool Jev-as-a-Judge for SRE.
On #SREGym, it costs only 1/510 of our original LLM-based judge using GPT Astra, with a 91% agreement rate. Integrating Jev and Astra, the judge achieved a 98.7% agreement rate, with a quarter of the cost using LLM only. Good stuff!
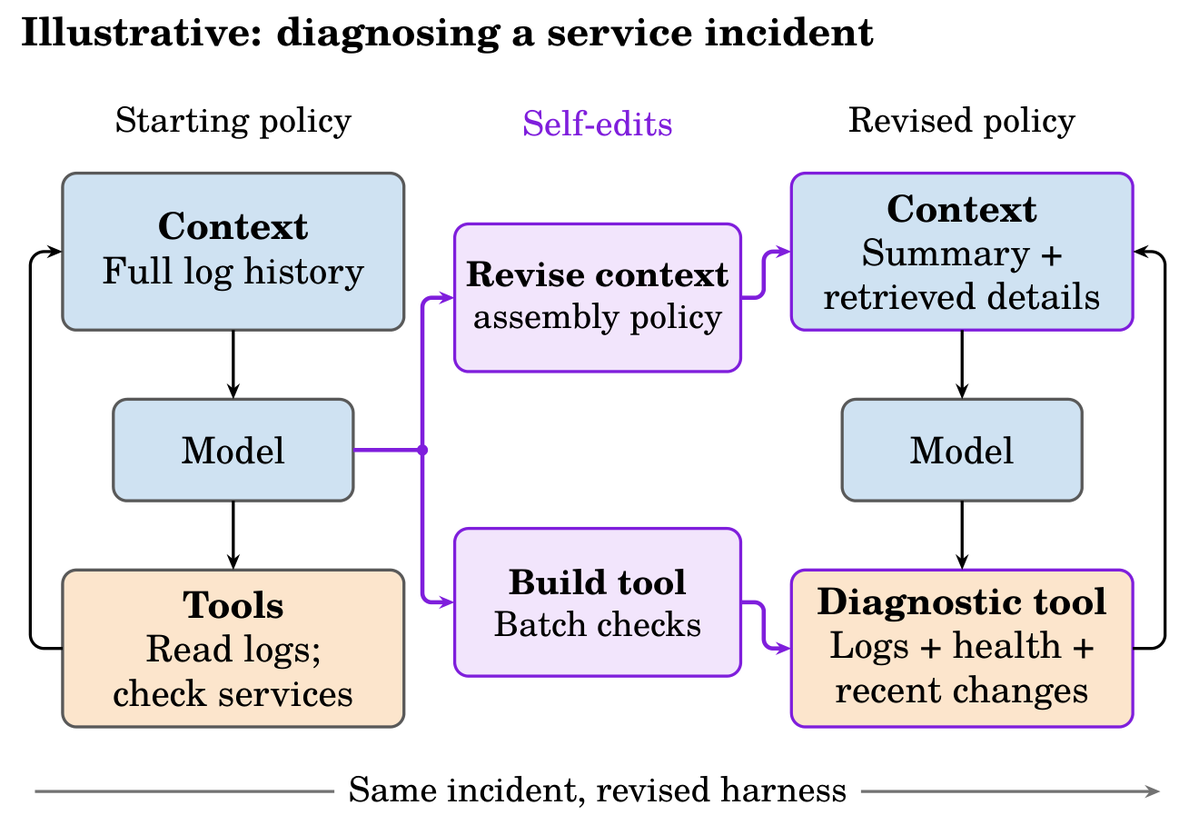
Agent harnesses are usually hand-tuned, or optimized offline against benchmarks. What if an agent could improve its own harness *while doing the work*?
Introducing Exo, a harness architecture for runtime self-improvement 🧵
(paper: https://t.co/0PZQms3Jo0)
I gave a talk on my work last week on Exo, an architecture for self-improving systems. it's my best attempt at crystallizing both the motivation and key properties we need for safe runtime self-improvement
very fun working on this w/ @martin_casado and @ankrgyl over the summer
Great work by @AlexKrentsel and co!
35% reduction of diagnosis time on #SREGym with significantly lower model cost.
Love the principle and architecture,
> Inspired by OS work on separating policy from mechanism, particularly ExoKernels, we expose primitive interfaces that leave as much policy as possible in the evolvable layer.
> Evals shouldn't just validate your architecture, they should try to break it.
This's the best compliment #SREGym could get. Glad it helped. Your work is awesome. Congrats!
And thanks for all the contributions to SREGym. We loved your PRs!
cc: @HacksonClark@SaadMRP
@bradenjhancock@dlwh@SnorkelAI In the same vein, I really love this paper: https://t.co/N9tqEx2Uxq I wonder how much we're leaving on the table by discarding benchmarks as saturated when a certain pass rate is hit, but other metrics to optimize on (like efficiency) are ignored.
You don't need an AI SRE.
We took kubectl away from Claude Code and gave it only @RadarK8s MCP tools.
It's now #1 on SREGym: 95.2% of 90 live Kubernetes faults diagnosed and fixed. #2 is at 72.2%. Writeup:
https://t.co/6vFCmSnfAJ
41s to a diagnosis, on a quarter of the tokens.
Thanks @tianyin_xu@HacksonClark@SaadMRP and everyone else building #SREGym in the open.
At KubeCon next week? Come see it at booth 365.