What’s beyond turn-based language models? 🤔
I believe future AI agents will become increasingly multimodal and interactive, excelling not only at task completion but also at proactive, real-time interaction with people across modalities.
We’re excited to push this frontier, first by enabling closed-loop evaluation and training of visual interaction agents, using simulated worlds and users across cooking, household, and mobile-use tasks.
Visual interaction models need a first exam in closed-loop assistance!
Unlike reference-based evaluations on prerecorded videos, ours evaluates assistance through user behavior and task outcomes, using controllable simulated users with diverse personas and scheduled out-of-plan events.
Using this environment, we not only establish a benchmark, but also train an interaction model through simulation RL, improving both task success and interaction quality!
Paper: https://t.co/4ShKBGrEQj
Project page: https://t.co/e9z2VzVLi9
Code: https://t.co/vz1BTq9g3w
Heading to #CoRL2026 in Austin! 🤖 Sharing three recent works on Robotics and 3D Vision from UW RAIVN Lab @RAIVNLab
🧊 GAM — 3D perception matters for robot learning and robustness. Instead of building on a VLA or WAM backbone, we train policies on WildDet3D, a pretrained 3D detector, achieving stronger robustness to visual changes than most VLA/WAM baselines we evaluated
https://t.co/1YM093UOqK
🦾 MolmoAct2 — Connecting embodied reasoning to continuous robot actions for real-world deployment, with open models, data, and training code
https://t.co/rWQ7Ynis68
📦 Reflex — Visually grounded whole-body control that lets a humanoid catch human-thrown boxes with about one second to react, using onboard RGB-D sensing
https://t.co/yntAEnDKBP
📍 Find us at CoRL — all times Austin local / CST
Nov 9 · MolmoAct2
• Main-conference Spotlight S1: 09:00–09:30 · Hilton Austin
• Poster #28: 17:00–18:30 · JW Marriott, Lone Star, 3rd floor
Nov 12
🏆 MolmoAct2 · TAG/G2A Best Paper Presentation
15:10–15:30 · JW Marriott, Room 208
🎤 Reflex · RoboLetics Presentation
09:50–10:30 · Hilton Austin, Salon D
🎤 Reflex · SimBench2Real Presentation
12:05–12:25 · JW Marriott, Room 212
Grateful to all my collaborators, and looking forward to the discussions in Austin! 👋
#CoRL2026 #RobotLearning #EmbodiedAI #Robotics #3DVision #3DPerception #VisionLanguageAction #RobotFoundationModels #HumanoidRobotics #Sim2Real #PhysicalAI
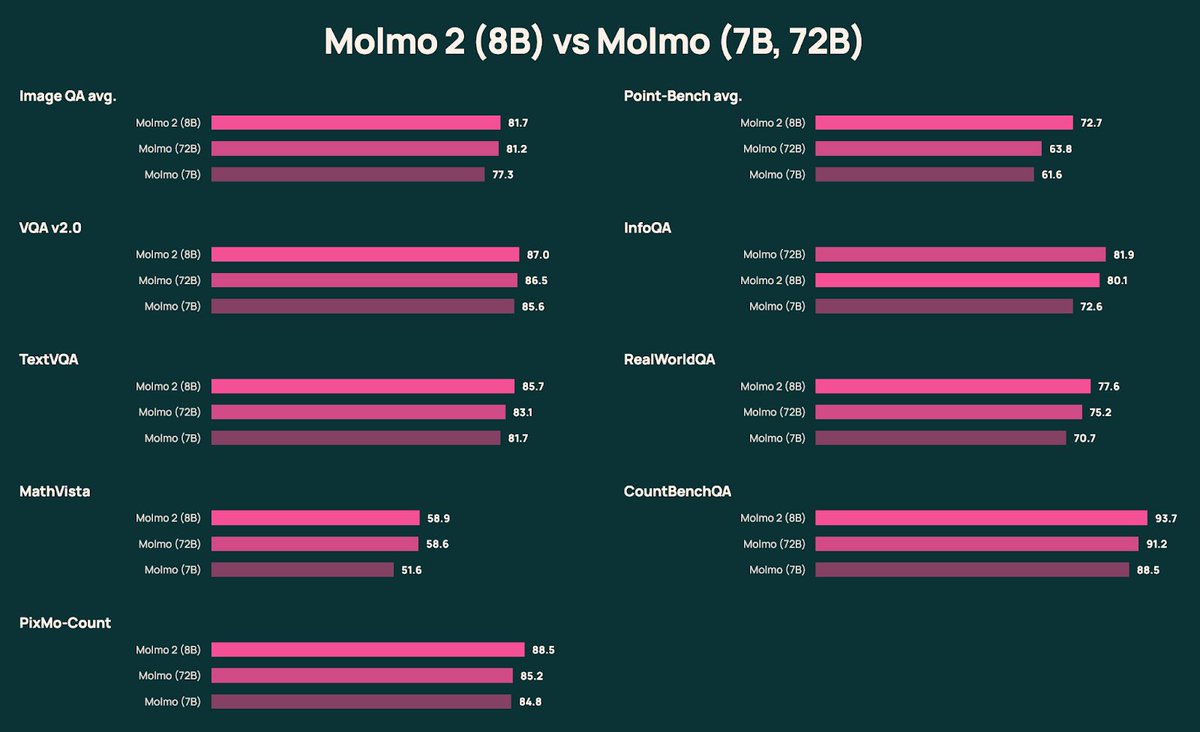
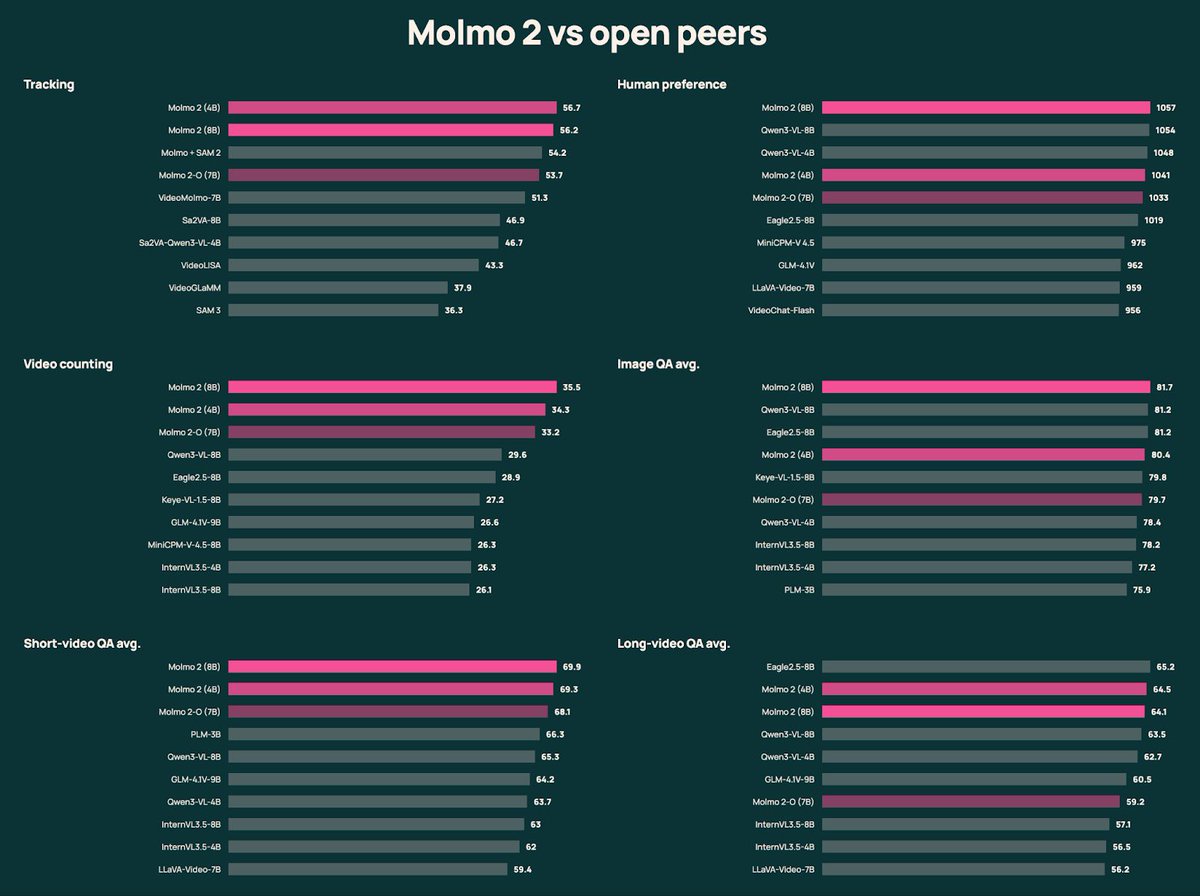
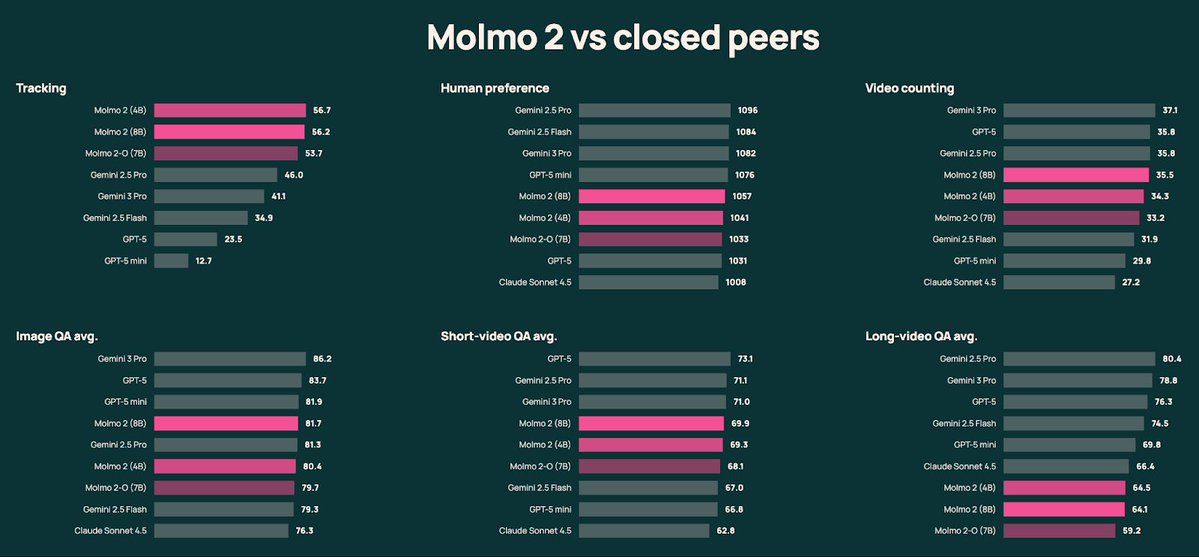
Last year Molmo set SOTA on image benchmarks + pioneered image pointing. Millions of downloads later, Molmo 2 brings Molmo’s grounded multimodal capabilities to video 🎥—and leads many open models on challenging industry video benchmarks. 🧵
📢Applications are open for summer'25 internships at the PRIOR (computer vision) team
@allen_ai:
Come join us in building large-scale models for:
📸 Open-source Vision-Language Models
💻 Multimodal Web Agents
🤖 Embodied AI + Robotics
🌎 Planet Monitoring
Apply by December 11, 2024!
This (& graduation) happened last week & I am a (fake) Dr. now!
I owe it all to my advisors, mentors, collaborators, friends, and family! -- I wrote a 6-page acknowledgment in my thesis without realizing😅
Thanks for all the fish @uwcse, @RAIVNLab, @uw_wail & @GoogleDeepMind🪆
Excited to introduce GPT-4o.
Language, vision, and sound -- all together and all in real time.
This thing has been so much fun to work on. It's been even more fun to play with -- with moments of magic where things feel totally fluid and I forget I'm video chatting with an AI.
🎉 Very Excited to present our recent work on “Selective🔍 Visual Representations for Embodied-AI🤖” next week at ICLR in Vienna🇦🇹!!
📣📣Important update! Our code and pretrained models are now available through our project website 🌐: https://t.co/LpojdZrFZn🚀
👋Come to my poster, say hi, and learn more about our findings! (Poster #111, Session 8, on Friday, May 10th at 4:30 PM)
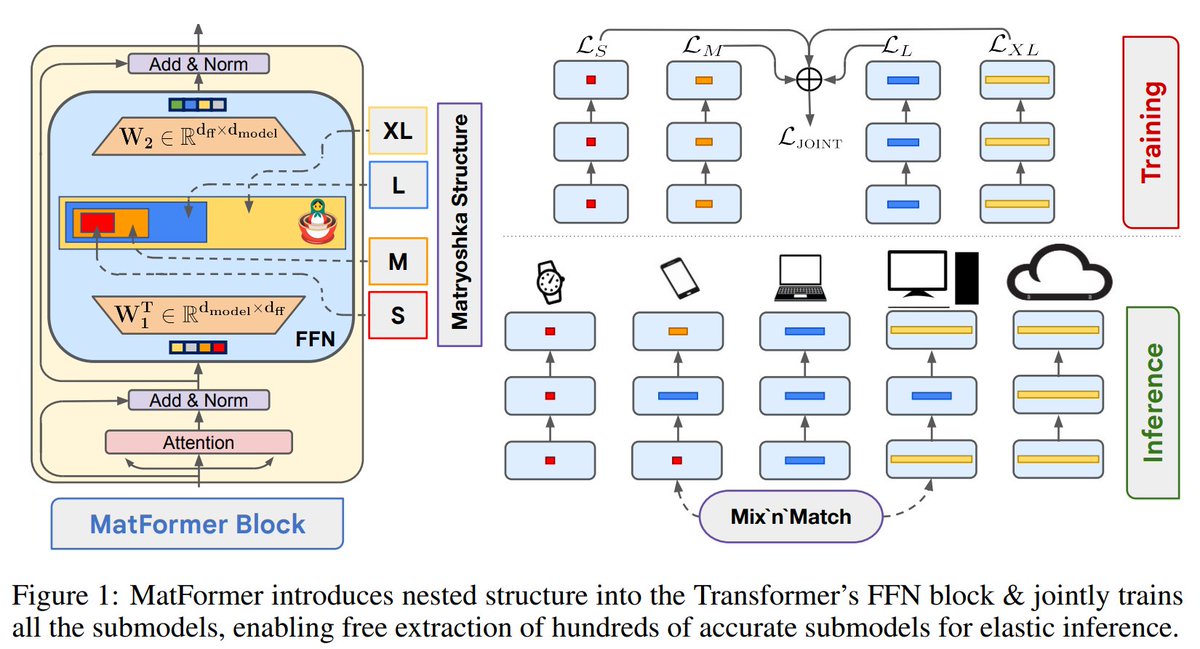
Check out🪆MatFormer🪆co-led by @adityakusupati: it’s a simple yet powerful general-purpose architecture with flexibility and elasticity built within. It works across modalities and enables super cool things at web-scale tasks🔥🔥
Announcing MatFormer - a nested🪆(Matryoshka) Transformer that offers elasticity across deployment constraints.
MatFormer is an architecture that lets us use 100s of accurate smaller models that we never actually trained for!
https://t.co/wzR7To7HZu 1/9
🚨Is it possible to devise an intuitive approach for crowdsourcing trainable data for robots without requiring a physical robot🤖?
Can we democratize robot learning for all?🧑🤝🧑
Check out our latest #CoRL2023 paper->
AR2-D2: Training a Robot Without a Robot
Have vision-language models achieved human-level compositional reasoning? Our research suggests: not quite yet.
We’re excited to present CREPE – a large-scale Compositional REPresentation Evaluation benchmark for vision-language models – as a 🌟highlight🌟at #CVPR2023.
🧵1/7
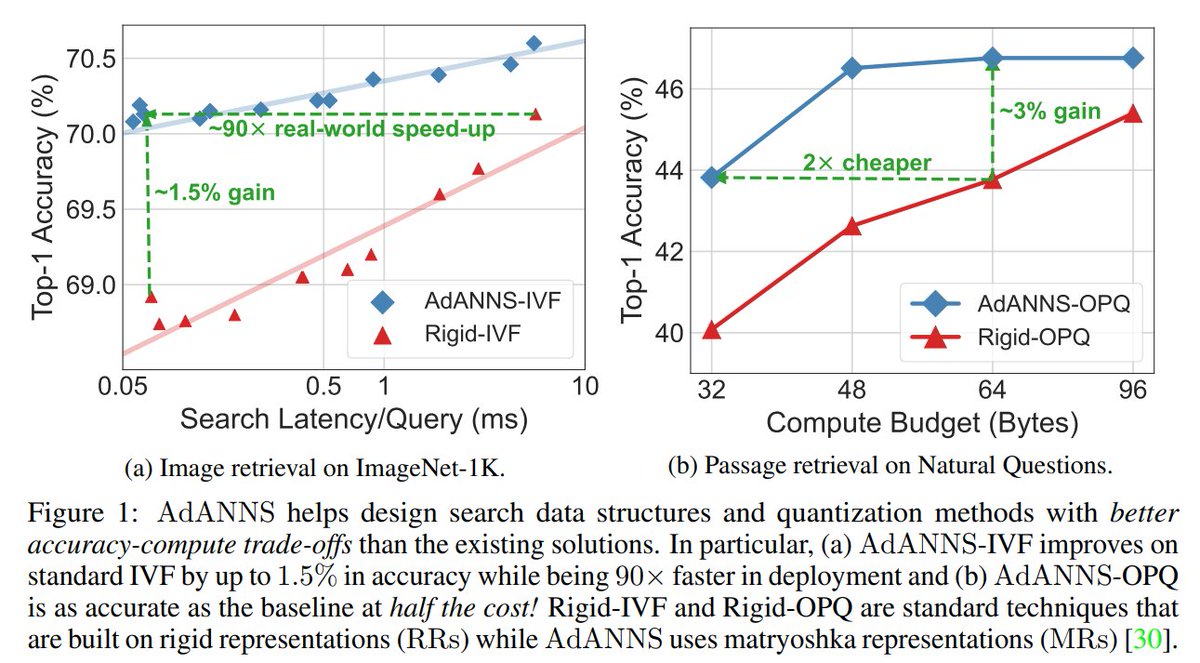
Introducing💃AdANNS: A Framework for Adaptive Semantic Search🕺
TL;DR: Up to 90× faster nearest neighbor retrieval and 2× lower memory cost for web-scale search.
Applies to vector search at scale & improves all "retrieval" augmented models!
https://t.co/yEnrr4oCwa
[1/8]
Introducing💃AdANNS: A Framework for Adaptive Semantic Search🕺
TL;DR: Up to 90× faster nearest neighbor retrieval and 2× lower memory cost for web-scale search.
Applies to vector search at scale & improves all "retrieval" augmented models!
https://t.co/yEnrr4oCwa
[1/8]