the fifth should be replaced with “不要比烂”.
think not what you've done better than someone else, but what other labs have done better than you.
oai and a\ are still leading the real frontier, glm can match opus with a <1T model, dpsk has incredibly high inference efficiency, we have very much work to do!
The"Tool" era of AI is ending. The "Agentic" era is here—but something is missing. 🧩
Individual agents are silos. Fragmented logic, rented intelligence, and isolated souls.
We’ve been building brains, but we forgot the Flow.
Introducing Anvita Flow: The Onchain Agentic Collaboration Network. 🌊
Over the next 4 days, we are going to ask 4 questions that will redefine how you see AGI, ownership, and human connection.
Are you ready to stop the silos and start the flow?
#AnvitaFlow #AgenticEconomy #Web3 #AI #RethinkingAGI
🚨SGLang Summer Fest Bonus Drop🚨
Proud to share a joint effort from Mooncake by
@Kimi_Moonshot, @Oracle , and SGLang: Kimi K2 trillion-scale deployment—running on 128 H200 GPUs sponsored by @NVIDIAAIDev DGX Cloud. OME + SGLang = MoE inference at production scale.👇
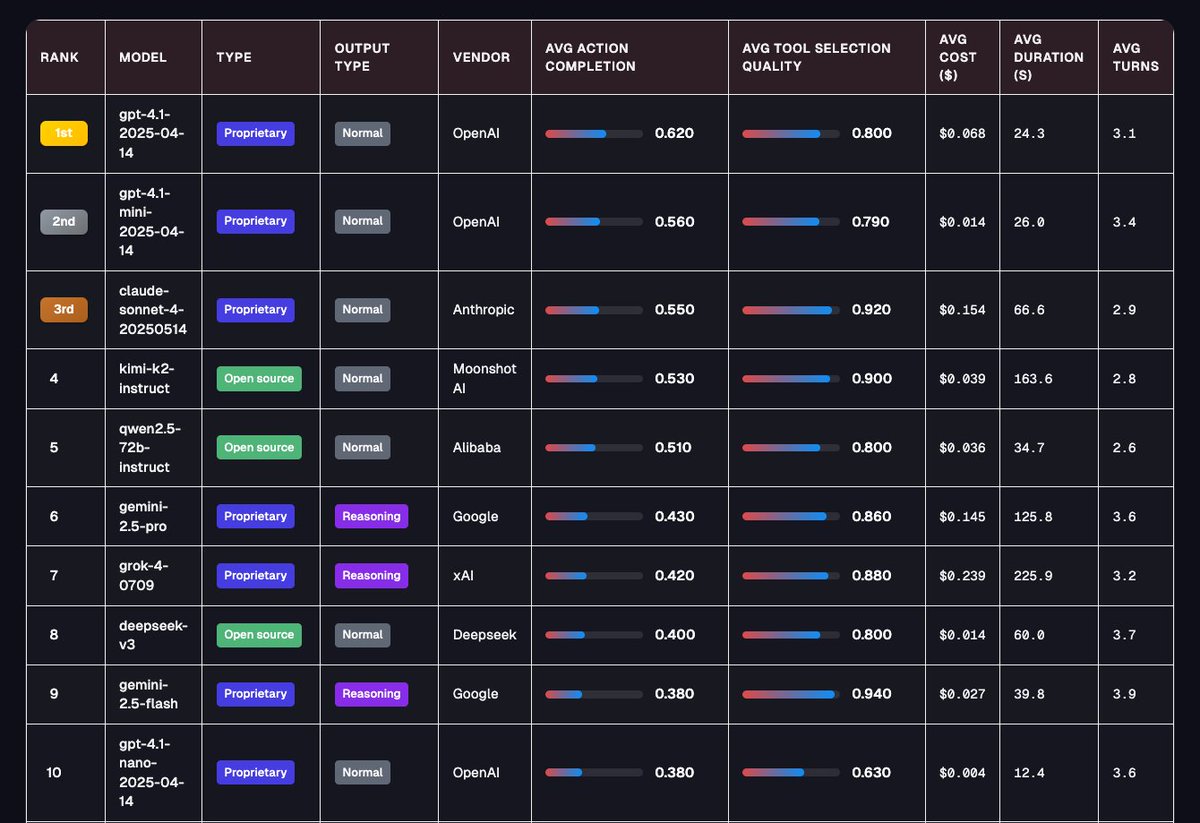
Agent Leaderboard v2 is here!
> GPT-4.1 leads
> Gemini-2.5-flash excels at tool selection
> Kimi K2 is the top open-source model
> Grok 4 falls short
> Reasoning models lag behind
> No single model dominates all domains
More below:
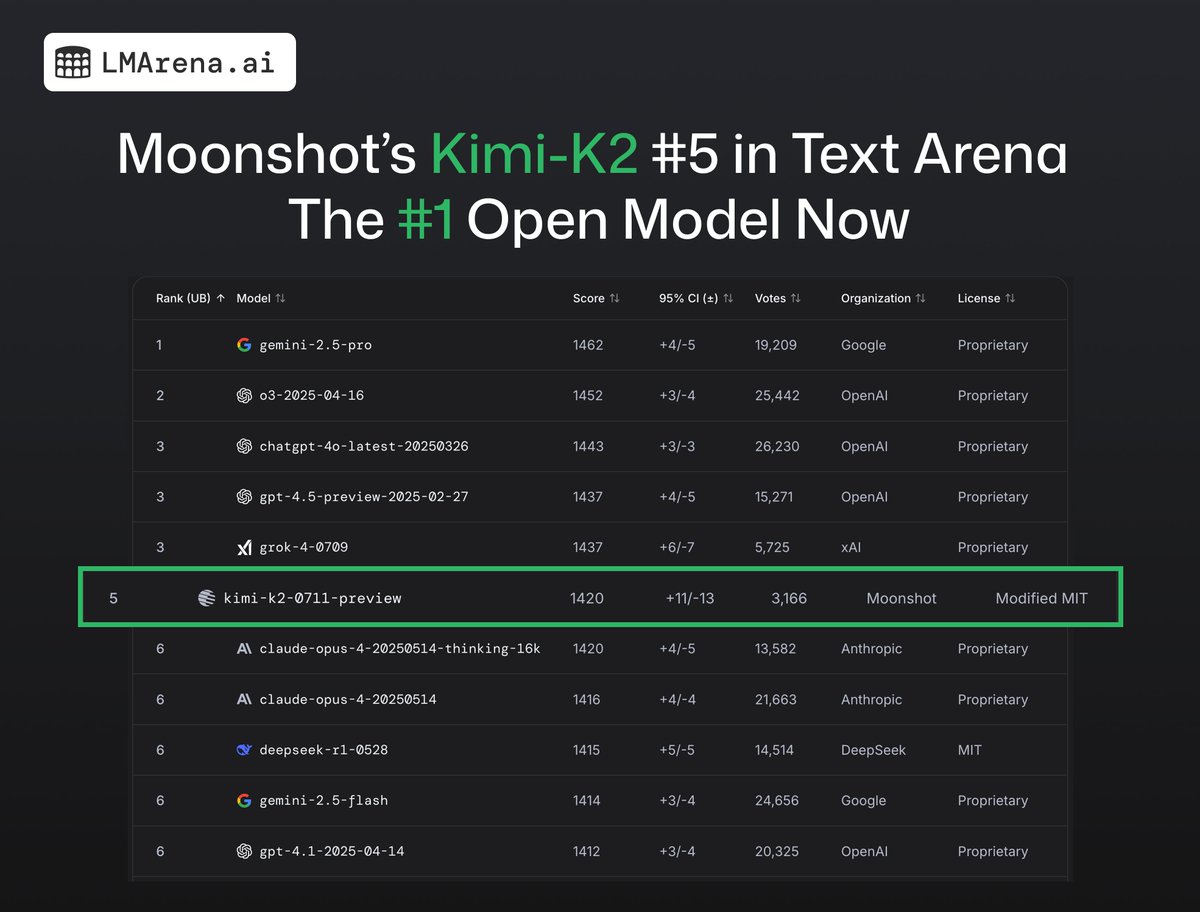
🚨 BREAKING: @Kimi_Moonshot’s Kimi-K2 is now the #1 open model in the Arena!
With over 3K community votes, it ranks #5 overall, overtaking DeepSeek as the top open model.
Huge congrats to the Moonshot team on this impressive milestone! The leaderboard now features 7 different providers in the top 15 - the most competitive it’s ever been.
More insights in the thread 🧵
🔥 Kimi K2 is not a reasoning model but you can use it like one
🎯 here's how:
1. give it access to the 'Sequential Thinking' MCP (link below)
2. put it in an agent loop
3. tell it to think sequentially before answering
it's so cheap that it won't cost you that much.
use a fast inference provider like Groq and it'll be super fast too
💥 BOOM. you've got a reasoning-like model.
(yes I understand that this is not quite the same as an internal CoT but regardless should make it smarter)
If you use the official API, there are tons of input tokens will hit cache when using coding agents. My rough estimation is like around 85% tokens are hit in typical agentic usage, that will cut the cost dramatically compared to third party providers for Kimi K2.
Kimi-K2 is definitely the first strong open-weight competitor to Claude Sonnet.
65.4% on SWE-Bench Verified in OpenHands, just 2.6 points shy of Claude Sonnet 4 with the same 100 iterations.
API cost is 4x cheaper, together with all benefits of open weights.
Kimi K2 at 185 t/s (or even higher, nearly 220 in my short tests) is probably the best use of Groq to date, and can make K2 immediately more compelling than Sonnet 4. Impressive that they've managed to fit this 1T monster on their chips.