LLM attach memorization is brittle, as it only works against attacks the LLM already knows
excessive reliance on attach memorization is why LLMs do well on benchmarks, but so poorly against human attackers who can rephrase and adapt attacks until one works
Its very interesting to note the pace of application features from the foundational model companies. As the cost of the marginal token approaches zero, the value is not in selling tokens. It is very clearly in moving up the stack and owning the application layer.
The first victim will not be established SaaS but AI Natives that spend heavily on the labs now - legal, sales, customer service AI Natives tbc. This is the lowest hanging fruit and the roadmap is clear from the traces and spans the model companies have from these companies already.
The next are the "connective tissue" applications that make using the models a foundational part of a workflow.
Take the google doc editing flows in OpenAI. Take the google drive/doc integration into chats.
Both are very good.
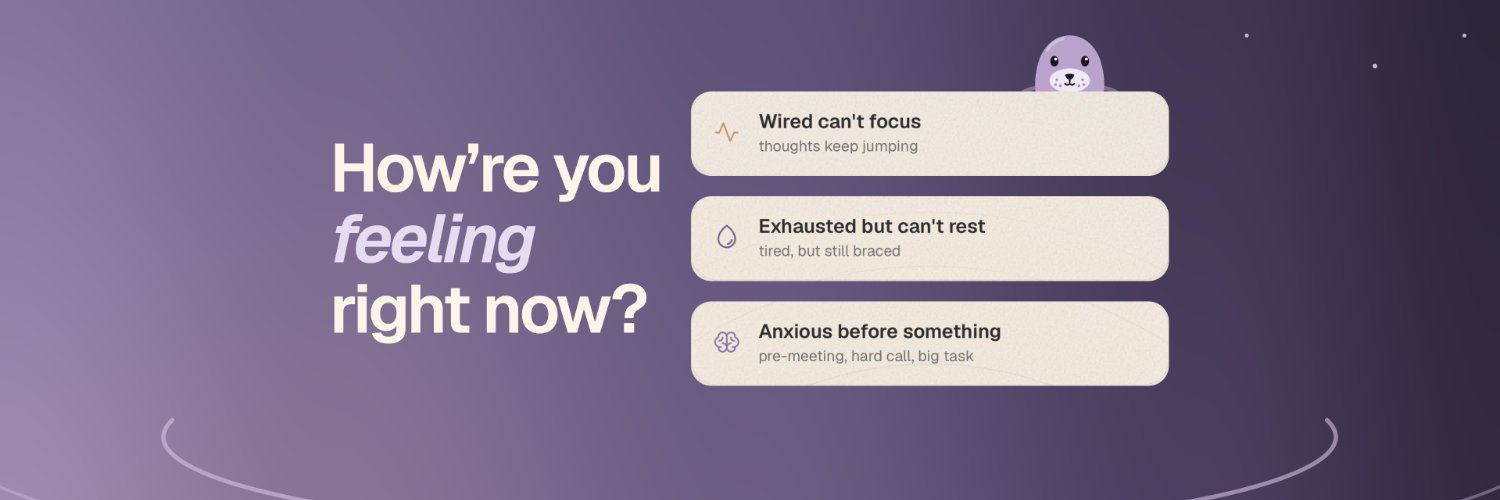
We sorted flowe into five places.
Today. Focus. Resets. Journey. Ada.
flowe grew one feature at a time. This release puts everything in order. It's live on the web and on your Mac. The link is in our profile.
Watch Episode 1 of our Odyssey series made with Grok Imagine.
Let us know in the comments if you'd like a full breakdown of how it was done!
Creative collaboration with @WonderStudiosX and director Dev Walker @glumlot_
AI should increase your capacity to think, not compete for control of your attention
my controversial opinion: "the most productive AI workflow might be the one where you stay in control”
@ThePrimeagen last week the big labs went to the White House and signed something something that made them responsible for model misbehaviour and such, not saying that’s the cause but very plausible!
there seem to be two camps when it comes to giving AI access to personal data.
one believes big tech already has most of our data anyway, so we might as well get some value from it.
the other sees it as a massive privacy risk and wants nothing to do with it.
i think there’s a more interesting middle ground here.
remember, these AI systems are increasingly building memory, learning our preferences, understanding our behavior, and adapting their responses to who they’re interacting with.
and as agents become more capable, that understanding will increasingly influence the decisions they make on our behalf.
so perhaps the better question isn’t simply “should i give AI access to this data?”
it’s “am i comfortable with an AI knowing this about me, remembering it, and potentially using it to make decisions for me in the future?”
and if i’m not, does the value i’d get from sharing it justify that tradeoff?
not all data deserves the same level of privacy, and not every useful interaction requires permanent memory or unrestricted access.
i think the real conversation we should be having is less about whether AI should have our data, and more about how much influence we’re willing to let that data have over our lives.
@gauravvohra man… I couldn’t even get through the on-boarding before abandoning ship;
as someone who uses LLMs daily and builds agents for all sorts of things, I struggle to find anything special about it, all hype, no results.