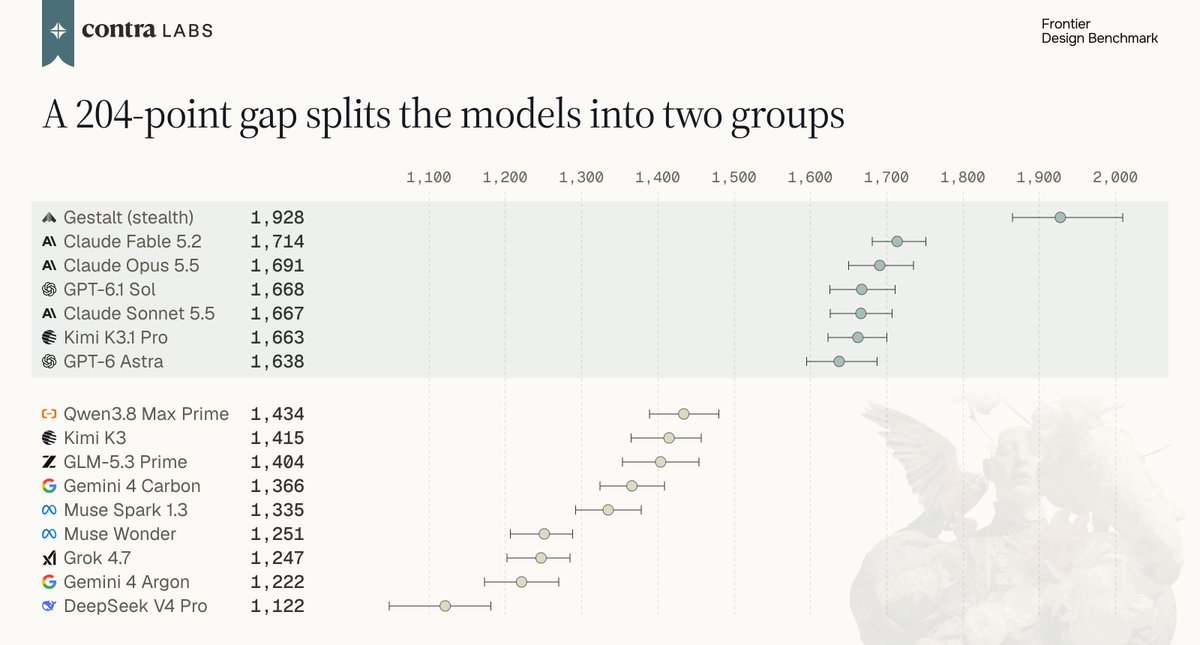
Claude is really, really good at design 👀
On the Frontier Design Benchmark, professional designers voted blind on real client briefs. Of the 15 models we ran:
#1 Claude Fable 5.2
#2 Claude Opus 5.5
#4 Claude Sonnet 5.5
@AnthropicAI's Fable is within 26 Elo of the human designs.
ok some back story of why we built this benchmark:
1. i love design. designers can benefit so much from actually useful ai models. most models will get there within a few months.
i want to know which model is best to use for design, that’s why we are creating a gallery so I (and you) can see myself (yourself)
2. i want to see models evaluated on realistic, complex design tasks, not just landing pages. in frontier design, we now have handful of web app/mobile app prompts, but we will expand to more types of product/non-product design
4. i don’t believe “taste” is such a mysterious thing that models cannot learn. we curated a list of rubrics based on practical design principles to use as evaluation criteria. our analysis found that these rubrics’ grading is highly correlated with expert preference on model outputs. we will do some post training experiments on these rubrics
5. ai models have so many slop patterns! our team curated a list of slop patterns (with some serious data analysis pipeline to back it up). models improve and slop patterns change, so we will keep iterating on these
a really interesting part: we were able to identify some model specific slop patterns: claude likes to use right arrows ➡️ while gpt tends to use the super narrow top right arrow ↗️. stay tuned and we will share as we go!
6. i tried so many design skills and mcps but not sure which ones actually work. we will be working on this, and there’s gonna be some trajectory inspection involved
if you have any topic you are interested in please lmk!
design will look very different very soon. we do this for nothing but the love of design 💖
Congratulations to the @AnthropicAI team on a huge day. I’ve been an avid user of all things Claude (or as I call her, Claudina) and am on the edge of my seat for the next post-IPO release.
And a special shoutout to my brother, @cnulty, for all he and his team do to communicate the value that Anthropic brings.
Future is bright!
Contra is one of the best examples I've seen of "pulling the thread" in startups.
No pivots, just consistently seeking greater resonance.
6+ years in and absolutely crushing. Love to see it.
As models continue to hill climb on design outputs, human will continue to raise the ceiling.
We wanted a better way to measure this that's not just crowdsourced opinions. We took real world, marketplace briefs and tested them against humans and models. Outputs were measured by real professional designer preference, a validated design critique rubric (grounded in how real designers, design), and AI slop detectors.
The results are both visually appealing and mentally stimulating (check it out -> https://t.co/XGAZCFxQSN)
The takeaway? Humans still beat models at the frontier (with a plot twist, see thread).
The AI industry has a benchmarking problem.
We're letting random people on the internet decide which models are best
even for capabilities like design...
So we built something different.
Introducing The Frontier Design Benchmark from @contralabs
https://t.co/Eiw47GSxEk
A last minute addition, soared to the top of the leaderboards, becoming the only model to beat humans (while still retaining a very strong position on the design critique and AI slop detectors).
This model raises the floor of what humans, and designers, can expect from the model. But as we know, creativity has no bounds. Excited to see what's built on this new model once it's released.
Since July I've personally felt agent advanced so much in design and acquiring taste, but has it reached superhuman level?
This benchmark answers that! We spent a lot of effort to make sure methodologies are rigorous and you should check this out
The future of robotics is agentic.
I distilled GPT 6 Astra into a tiny 4B parameter model and it learned to drive a robot arm!
Before: It couldn't finish a single task, and at one point decided the bowl right in front of it didn't exist.
After: 0 -> 22.5% on scenes it was never trained on 🧵