- Kling is better than Sora
- FLUX is better than DALL-E
- Sonnet is better than GPT-4o
NO ONE would have predicted this a year ago! Everyone would have blindly bet on OAI or Google!
It’s super amazing to see startups succeed and take on 1000 pound gorillas!
This is why businesses with strong network effects are (and should be) built and valued differently.
This is literature standalone cash-flow during our worst phase. From negative FCF to 3.8% FCF margin to 32% FCF margin in 7 months.
WTF even is this sorcery...
The Human Eval Leaderboard Is Gamed! Please Stop Using It 🙏
3.5 Sonnet is MUCH BETTER than GPT-4o-mini. A simple vibe check will confirm it
Any leaderboard that says otherwise is gamed and doesn't work!
It's misinformation to claim that Mini is better than 3.5. Similar Gemini/Gemma or whatever else scoring high on this leaderboard shouldn't be so high up.
The gaming is done by style hacking the responses. You can add lists/bullets and format the responses to trick the human brain into voting for your model.
Both Google and OAI indulge in this type of style hacking to score high on this benchmark.
Benchmark gaming is a rampant problem in AI; it's important to update our benchmarks and, more importantly, focus on the real goal! - AGI
The @aiDotEngineer World's Fair in SF this week 🔥
https://t.co/9AhHrNiVUo
Reminded of slide #1 from my most recent talk:
"Just in case you were wondering…
No, this is not a normal moment in AI"
NOW is the best time to build a startup in India!
Towards this, @nitinsharma1 & I are committing $10M from @AntlerIndia into exceptional idea-stage founders in the coming 6 months.
$500K per company X 20 investments - We will work with you in your ambiguous -1 to 0 phase and get you >$1Mn in total within 6-9 months of starting up!
If you are building, write "Build" in the comments and we'll message you.
If you know someone who has an idea, tag them below.
If you're just curious, join the AMA next week for all the details! (link in the first comment)
Help spread the world and make India a startup nation.
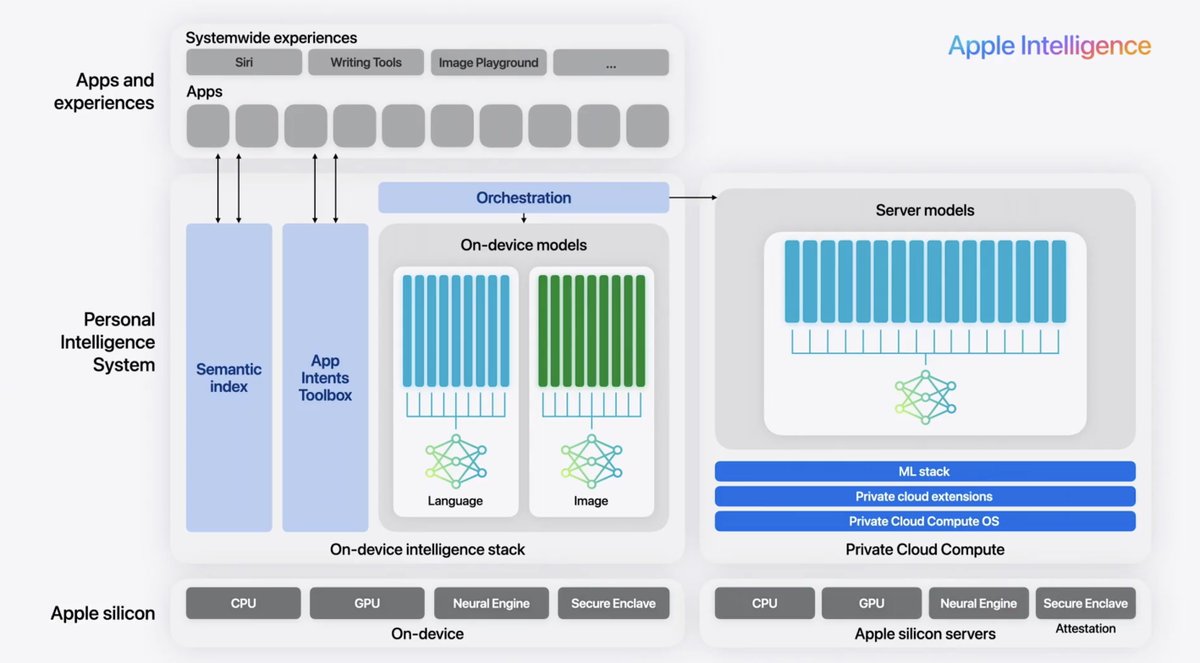
Marketing speak to terms you already know:
semantic index -> embeddings
app intents -> function calling
on device language model -> 3B fine tuned LLM w/ included LoRA adapters
on device image model -> diffusion model w/ included LoRA adapters
orchestration -> Siri
Neural Engine -> Apple's GPU
While there are some similarities with 'The Era of 1-bit LLMs' paper -here are the key differences between the two papers
📌 The core concept in the "The Era of 1-bit LLM" paper is to quantize the weights of a standard Transformer LLM architecture to 1.58 bits (ternary {-1, 0, 1} values) while using 8-bit activations. The paper introduces a variant called BitNet b1.58 which is based on the BitNet architecture that replaces nn.Linear layers with BitLinear layers using ternary weights. However, it still relies on the standard Transformer architecture components like self-attention which involve matrix multiplications.
📌 The MatMul-free LM architecture is a more radical departure from standard Transformers, as it completely removes MatMuls by using a recurrent-based token mixer (MLGRU) and a GLU-based channel mixer with ternary weights.
📌 Another key difference is that the 'MatMul-free' LM architecture uses a recurrent-based token mixer (MLGRU) to capture sequential dependencies, while BitNet b1.58 relies on the standard self-attention mechanism in Transformers for capturing token interactions.
The authors somewhere mentioned it will probably be 8 more months before a wide hardware implementations
@sreeenidhi@samcook_ For instance, imagine a SearchMyDocs customer complains publicly that the service gives wrong answers. Would you share customer documents publicly to prove that the answer was actually correct in that context?
Gentle reminder to everyone that works with customer data not to casually leak metrics and infra details publicly.
An angry customer tweeting publicly about a bill doesn’t terminate your overall confidentiality requirements (probably legally, definitely ethically).
@TandonRaveena - We at @CautioTech are building a startup focused on dash-cams, with a mission to enhance safety in transportation.
Our goal is to empower women, children, and everyone to travel with freedom and security.
Would love to have our devices put in your vehicles at absolute no cost, and also figure how together we could make 🇮🇳 safe.
@lennysan I prefer B. A is too verbose. B is not perfect but seems more likely written by a human. Between these two, B is better. However, with better fine-tuning, I think a C written by a well-optimized model would be a better choice.
We're seeing gpt-4o perform worse than gpt-4-turbo across the board, especially when it comes to hallucinations.
Not sure why this is not discussed, but @OpenAI clearly shipped an inferior model that's cheaper and faster.