After co-inventing ChatGPT, I kept asking myself: why have superhuman chat models not led to AGI?
I’ve spent the last 2 years in stealth building a new way to train models (RLCD), and a new type of frontier AI model that we are releasing today: Jev
• 20-200x faster
• 40-400x cheaper (w/ output tokens free)
• Frontier composable intelligence optimized for decisions
AFAICT the shortest path to AI-based economic revolution
The US government, citing national security authorities, has issued an export control directive to suspend all access to Fable 5 and Mythos 5 by any foreign national, whether inside or outside the United States, including foreign national Anthropic employees.
The net effect of this order is that we must abruptly disable Fable 5 and Mythos 5 for all our customers to ensure compliance.
Access to all other Claude models is not affected.
We apologize for this disruption to our customers. We believe this is a misunderstanding and are working to restore access as soon as possible.
Read our full statement: https://t.co/bwn0sximKZ
1/ We are sharing additional details regarding our investigation into unauthorized access to GitHub's internal repositories.
Yesterday we detected and contained a compromise of an employee device involving a poisoned VS Code extension. We removed the malicious extension version, isolated the endpoint, and began incident response immediately.
We are investigating unauthorized access to GitHub’s internal repositories. While we currently have no evidence of impact to customer information stored outside of GitHub’s internal repositories (such as our customers’ enterprises, organizations, and repositories), we are closely monitoring our infrastructure for follow-on activity.
Suddenly feeling the urge to copy your repo somewhere new? @EntireHQ is open sourcing our latest project today: git-sync.
Most git migration tools assume you’ll make a local mirror clone, fetch everything down, then push it back up somewhere else. Instead, git-sync mirrors refs from a source remote to a target remote without a local checkout, streaming packfiles directly over Smart HTTP with an in-memory object store. And reruns are boring in the best way: if nothing changes, nothing gets pushed.
Contributions are more than welcome, from humans and from agents.
https://t.co/570jlIUZJ0
Unplugging completely! No WiFi and zero notifications. A great way to get deep focus on a project.
Here is a walkthrough showing how to run Gemma 4 (26B A4B) fully offline with LM Studio & OpenCode to parse PDFs, ask questions, and build sites 100% locally.
LLM Knowledge Bases
Something I'm finding very useful recently: using LLMs to build personal knowledge bases for various topics of research interest. In this way, a large fraction of my recent token throughput is going less into manipulating code, and more into manipulating knowledge (stored as markdown and images). The latest LLMs are quite good at it. So:
Data ingest:
I index source documents (articles, papers, repos, datasets, images, etc.) into a raw/ directory, then I use an LLM to incrementally "compile" a wiki, which is just a collection of .md files in a directory structure. The wiki includes summaries of all the data in raw/, backlinks, and then it categorizes data into concepts, writes articles for them, and links them all. To convert web articles into .md files I like to use the Obsidian Web Clipper extension, and then I also use a hotkey to download all the related images to local so that my LLM can easily reference them.
IDE:
I use Obsidian as the IDE "frontend" where I can view the raw data, the the compiled wiki, and the derived visualizations. Important to note that the LLM writes and maintains all of the data of the wiki, I rarely touch it directly. I've played with a few Obsidian plugins to render and view data in other ways (e.g. Marp for slides).
Q&A:
Where things get interesting is that once your wiki is big enough (e.g. mine on some recent research is ~100 articles and ~400K words), you can ask your LLM agent all kinds of complex questions against the wiki, and it will go off, research the answers, etc. I thought I had to reach for fancy RAG, but the LLM has been pretty good about auto-maintaining index files and brief summaries of all the documents and it reads all the important related data fairly easily at this ~small scale.
Output:
Instead of getting answers in text/terminal, I like to have it render markdown files for me, or slide shows (Marp format), or matplotlib images, all of which I then view again in Obsidian. You can imagine many other visual output formats depending on the query. Often, I end up "filing" the outputs back into the wiki to enhance it for further queries. So my own explorations and queries always "add up" in the knowledge base.
Linting:
I've run some LLM "health checks" over the wiki to e.g. find inconsistent data, impute missing data (with web searchers), find interesting connections for new article candidates, etc., to incrementally clean up the wiki and enhance its overall data integrity. The LLMs are quite good at suggesting further questions to ask and look into.
Extra tools:
I find myself developing additional tools to process the data, e.g. I vibe coded a small and naive search engine over the wiki, which I both use directly (in a web ui), but more often I want to hand it off to an LLM via CLI as a tool for larger queries.
Further explorations:
As the repo grows, the natural desire is to also think about synthetic data generation + finetuning to have your LLM "know" the data in its weights instead of just context windows.
TLDR: raw data from a given number of sources is collected, then compiled by an LLM into a .md wiki, then operated on by various CLIs by the LLM to do Q&A and to incrementally enhance the wiki, and all of it viewable in Obsidian. You rarely ever write or edit the wiki manually, it's the domain of the LLM. I think there is room here for an incredible new product instead of a hacky collection of scripts.
I was fired from Anthropic today.
I was the engineer responsible for shipping the latest dev/claude-code npm package. Wanting to improve the debugging experience for the team, I decided to include source maps in the release. This resulted in our entire internal codebase being publicly exposed including thousands of files with every agent command, all system prompts, the complete query engine, Undercover Mode, Bypass Permissions Mode, and our internal telemetry configuration.
I take full responsibility. I genuinely believed the safeguards Claude Code had built for me would be adequate and it was a serious miscalculation on my part.
My actions have unintentionally open-sourced major parts of Claude’s architecture well ahead of schedule. I apologize to the team and to Claude.
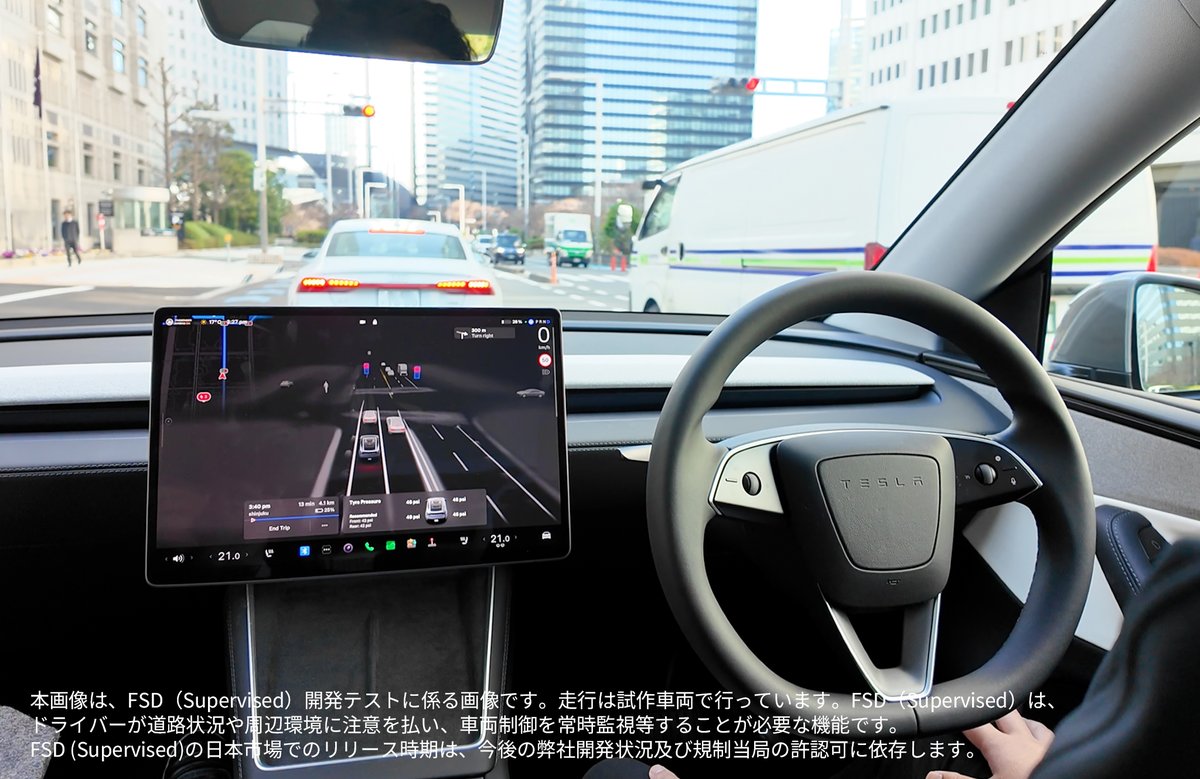
🚨 Tesla FSD (Supervised) Just Crushed Tokyo’s Wildest Streets 🇯🇵 $TSLA
A Japanese YouTuber hopped in for a test ride through the insane crowds and chaos around Shinjuku Station — pure Full Self-Driving (Supervised), with a Tesla engineer in the seat just monitoring.
Ride Highlights:
• Sliced through complex urban madness: seamless lane changes, tight turns, packed pedestrian zones, narrow alleys, and blurry lane markings
• Drove like a seasoned pro — smooth acceleration, pinpoint stops at yellow lights, polite yielding to lane-splitting bikes and random obstacles
• Waited patiently at unmarked crossings and perfectly matched the flow of Tokyo traffic
• Engineer’s hands stayed on his lap the entire time — zero interventions needed
Creator’s Take:
Started off nervous… ended up totally relaxed and chatting casually within minutes.
He called it “already very capable” in Japan’s densest city conditions and said it feels ready for real service soon — just minor local tweaks left.
Huge step for global FSD rollout.
Video is wild 👀
BREAKING🇯🇵 : First Tesla FSD experience on Japanese public roads in Tokyo.
It's handling Japan's unique road environment smoothly. Now, we're just waiting for official approval from the authorities.
Big step for Japan's mobility future! Here are some clips from my camera.
Nintendo took 40 years to give us a Legend of Zelda movie.
I made this in 5 days on a $300 budget.
It looks like a $300M blockbuster.
Let me show you how I made this in 5 simple steps inside of Freepik: 🧵