@hqmank Free tokens, but they’re unusable for the time being :D So, the advertising actually ends up being terrible publicity—what with all the "Reconnecting 3/10" messages, and various other errors.
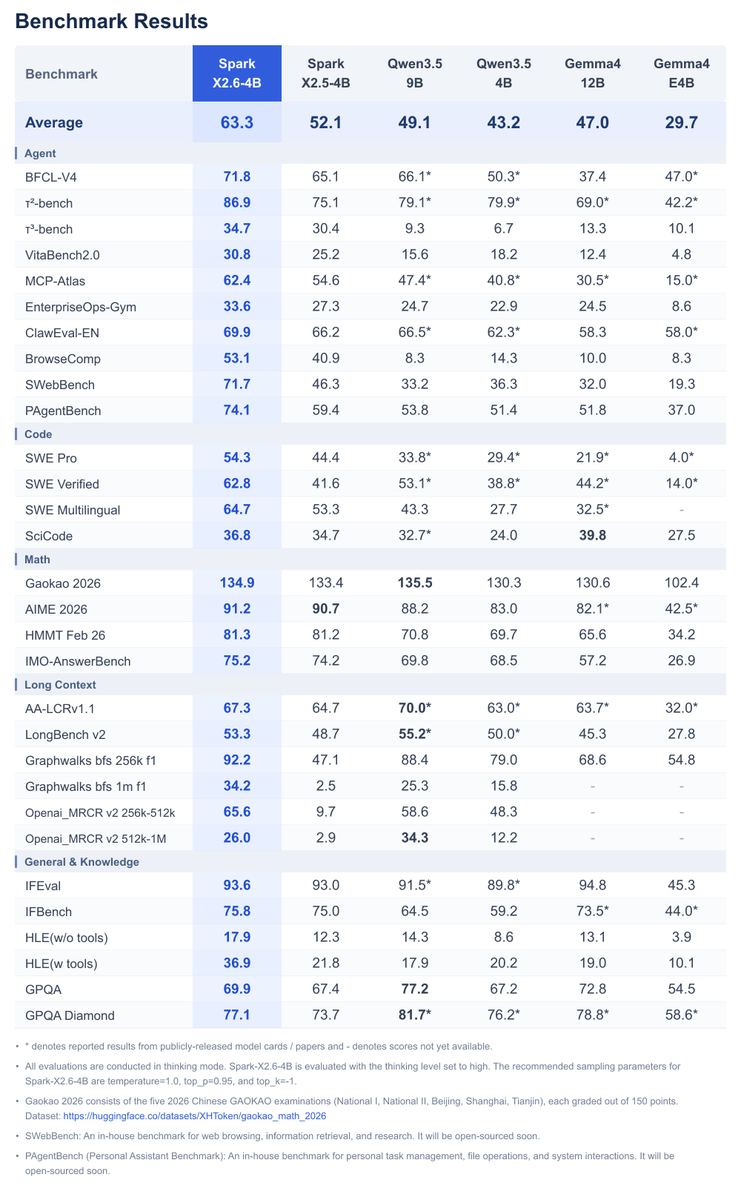
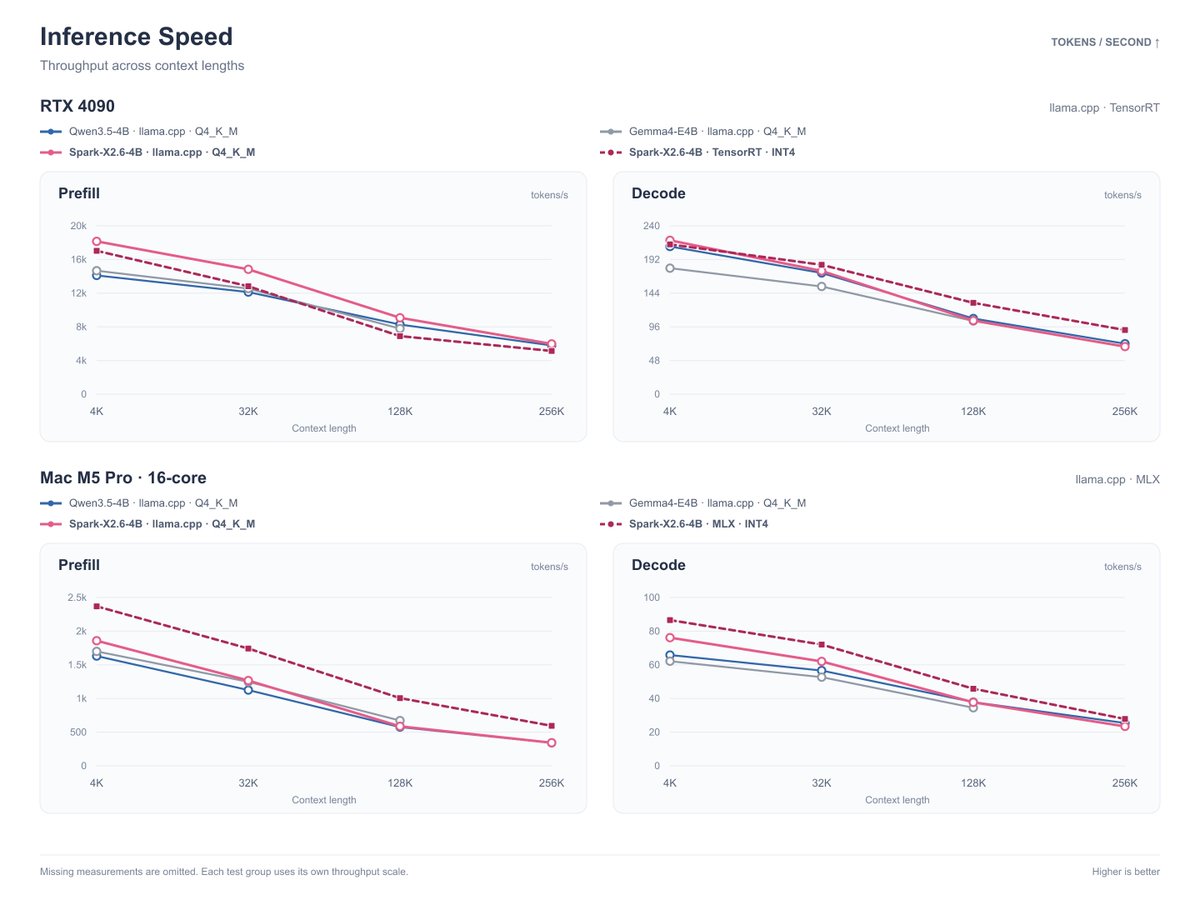
A 4B model that matches or beats ~9B open models on agentic coding — and it's built to run on your phone.
@SparkLLM Spark-X2.6-4B, Apache-2.0, with none/low/high thinking budget.
Full specs:
https://t.co/GGip4FNhGz
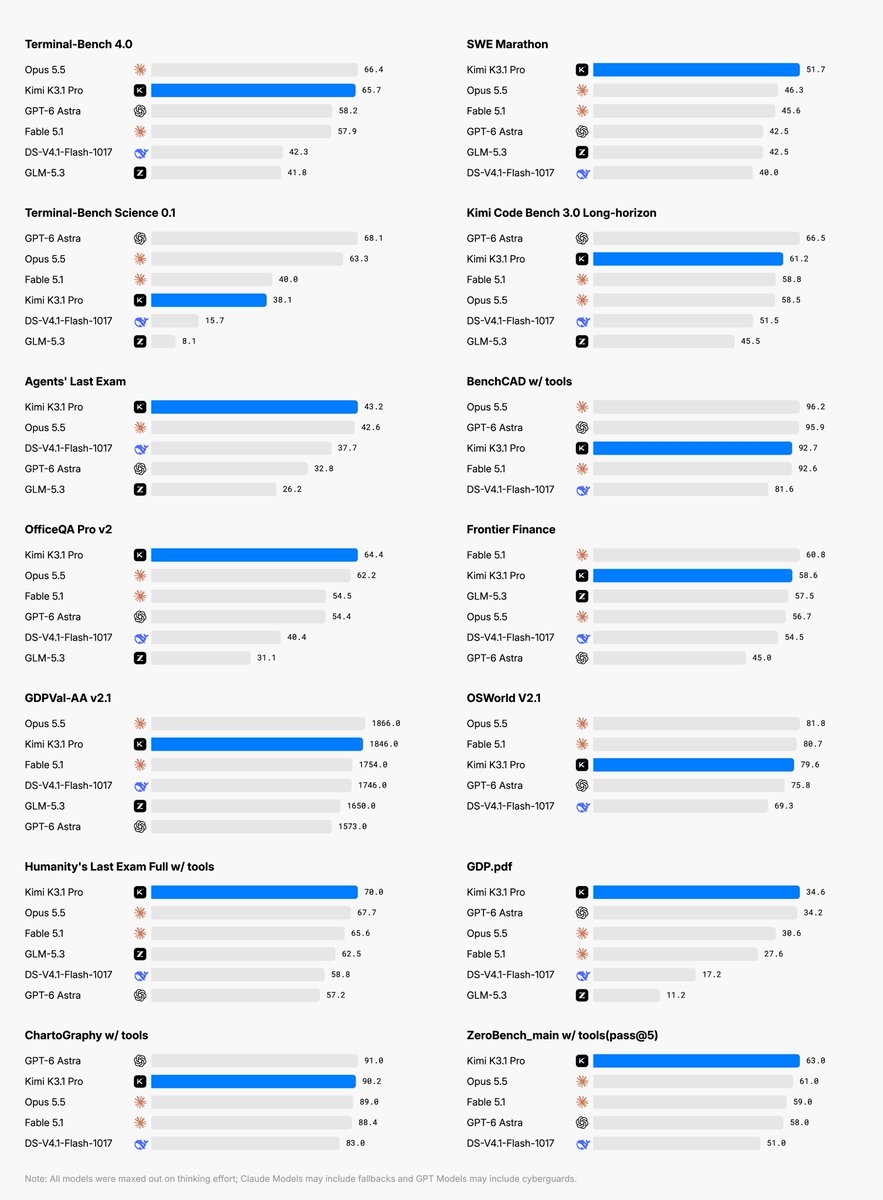
An open-weight model now sits 0.7 points behind Claude Opus 5.5 on Terminal-Bench — and ahead of GPT-6 Astra. Kimi K3.1 Pro: 2.8T MoE, 1M context, weights on Nov 4.
Full breakdown:
https://t.co/rPBzTL7xZu
Introducing Kimi K3.1 Pro: our most capable 3T-class open-weight model.
🔹 1M-token context, 2.8T total / 104B active params (MoE), Multimodal.
🔹 Full-project coding: games in Unreal, Unity & Godot.
🔹 Excels at parametric 3D modeling in Blender & CAD.
🔹 More reliable at finance work: Accurate modeling with hallucination down by 65%.
🔹 Matching the strongest proprietary models across coding, agentic and knowledge benchmarks.
Kimi K3.1 Pro and K3.1 Pro Highspeed (2–3× faster) are now live on https://t.co/85jA71X9gw, Kimi Work, Kimi Code, and the Kimi API.
Open weights by Nov 4, 2026.
🔗 API: https://t.co/XCrgjXAqMw
🔗 Tech blog: https://t.co/5iPP0MBej6
Space Bunny — the anonymous model that quietly processed 200T tokens — was MiniMax's @MiniMax_AI new M3.1 Flash all along. 3× faster, 70% cheaper: our breakdown
https://t.co/ynwEGaNh9L
GLM-5.3 Flash offer free token🔥
ZCode is giving out 300M tokens for its Weekend - GLM 5.3
Claim here: https://t.co/xHOe1s0CnX valid until October 12, 6 AM use it while it lasts
BACKR: Free 13-point SEO audits, rank tracking & AI content is launched today on producthunt with special promotionnal code for this event !
https://t.co/mQWNbY7Epj
Google's new frontier model: $2/M in, $10/M out at launch.
GPT-6 Astra costs 5x more. Claude Opus 5.5, 2x more.
And Argon still takes SOTA on DeepSWE (77.9%).
Gemini 4 Argon can output 1,000,000 tokens in a single response.
The price war continue 😍
https://t.co/U6VR4A27RF
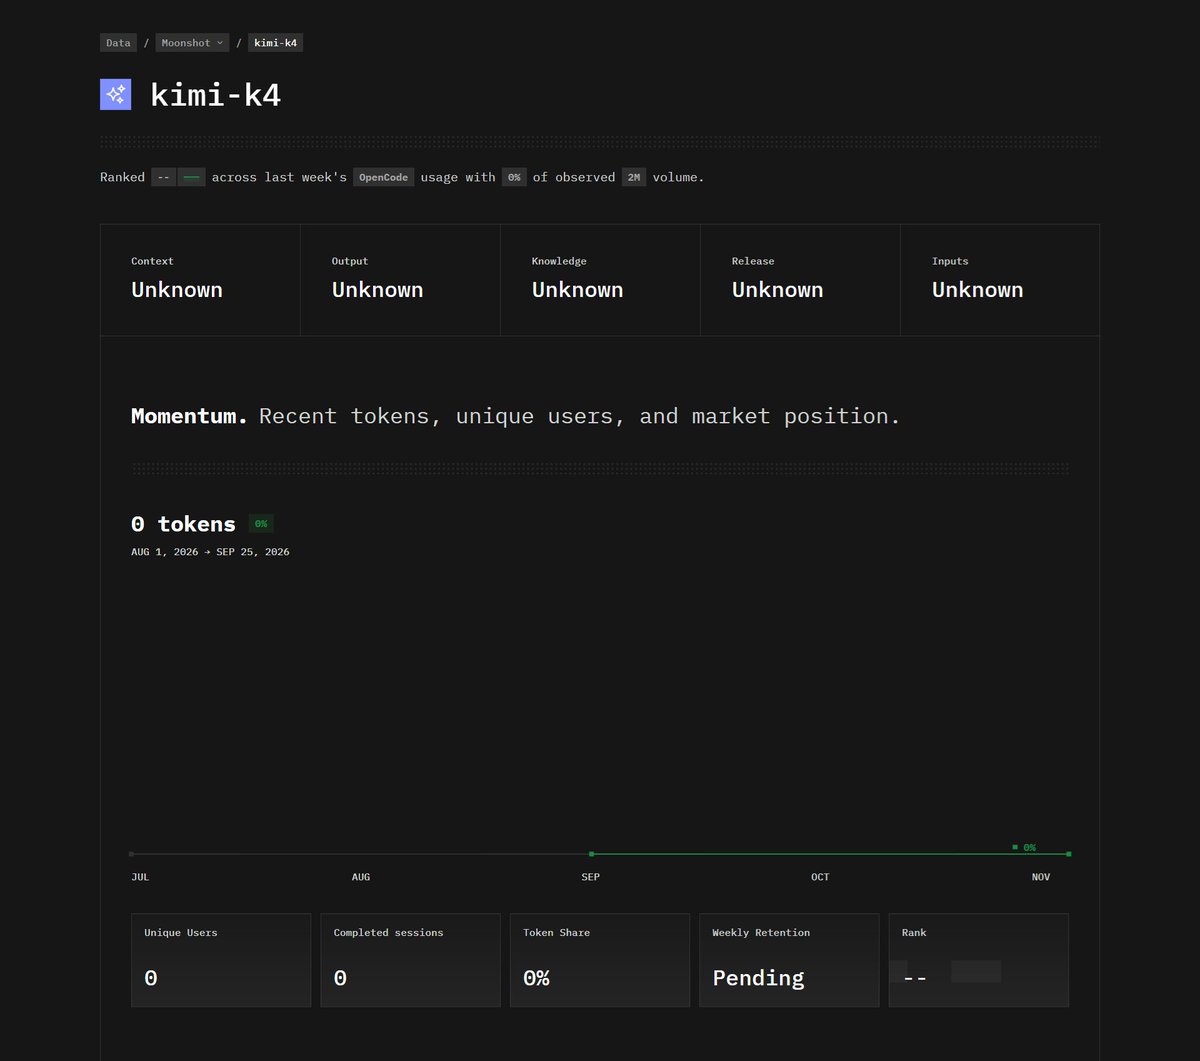
OpenCode's sitemap just leaked GLM-5.5 Flash, GLM-5.4, Kimi K4, DeepSeek V4.1 Pro and Muse Spark 1.4 before anyone announced them.
They removed them from the sitemap rn, but the pages are still live. Kimi K4 already has its own stats page sitting at 0 tokens, waiting for launch day.
The best AI leak source in 2026 is apparently an SEO file.
@OpenAI just cut API prices in half.
GPT-6 Sol beats Claude Opus 5 (max) on AutomationBench — at 9% of the cost per task.
And Luna? $0.10/M input, $0.50/M output.
Full breakdown
https://t.co/tbif1EjiTY
Claude Opus 5.5
An early tester migrated 680,000 lines of code in under a day.
Fable 5.1-level performance, 40% cheaper than Opus 5 ($4/M in, $20/M out).
Full breakdown
https://t.co/e8uirc1i93
Introducing Claude Opus 5.5, the first model in our new Claude 5.5 family.
It performs at the level of Claude Fable 5.1 for most tasks, and costs 40% less to run than Opus 5.
Grok 4.7 is here, an incredible low cost model for resolve 90% usecase !
▪️ Coding agent index: 47 → 56
▪️ AA Intelligence Index: 44 → 46
▪️ CursorBench 4.0: 46.3% — frontier price-performance
▪️ Same price as 4.6: $2/M in, $6/M out
Full breakdown
https://t.co/a3dTEyMWMY
Xiaomi @XiaomiMiMo come back with new release model who are some good improvement
Pro scores 46 on the Artificial Analysis Intelligence Index
First review/test show some real good usecase for an incredible pricing
https://t.co/i6un9Qh16h
Introducing Xiaomi MiMo-V2.6 — Pro & Flash.
Frontier intelligence, all the modalities, built in public.
🔹 Two omnimodal models, advancing through scaled reinforcement learning
🔹 Pro performs on par with Claude Opus 5 and GPT-5.6 Sol across most agent benchmarks
🔹 Pro scores 46 on the Artificial Analysis Intelligence Index — the highest among open-source models
🔹 Stronger coding, computer use, 3D reasoning and creative capabilities
🔹 Open model weights, technical report, RL environments and training code
Blog:https://t.co/JGdwC9Ymvj
Wow now Zcode is totally open-sourced so anyone can fork it, upgrade it and check what this harness make to be strong for have this very high cache rate on Agentic !
Thanks @Zai_org@zcode_ai to open it
In response to the ZCode product security issues reported by the community, we have completed the necessary remediation and sincerely apologize to all our users.
We have open-sourced ZCode at https://t.co/oADgletuha, placing the code under community scrutiny and making ZCode more open and transparent.
We sincerely thank the community developers who previously identified issues in ZCode. Going forward, we will establish an ongoing product security vulnerability reporting and response process. We welcome developers to continue reviewing ZCode and reporting potential issues, and we will provide rewards based on the severity of the issues reported.
With respect to the code data referenced by the community, we confirm that no such data is retained and that it has never been used for model training.
Following the remediation, we invited the China Academy of Information and Communications Technology (CAICT) and NSFOCUS to conduct security assessments. The results are as follows:
Through its technical assessment, CAICT confirmed that the zcode-prod Alibaba Cloud OSS bucket is in a zero-data state. Security remediation has been completed in the ZCode v3.14.0 client. The Repo Wiki feature has been removed, and the workflow for generating and uploading local repository snapshots has been disabled.
NSFOCUS confirmed that all data objects in the zcode-prod Alibaba Cloud OSS bucket, as well as the bucket itself, have been deleted. Remediation has been completed in the ZCode v3.14.0 client. The Repo Wiki entry point and the associated generation workflow have been removed, and no functional path capable of triggering the generation of local repository snapshots or transmitting local files externally was identified.
Once again, we sincerely apologize and welcome continued scrutiny from the community. The full security assessment report will be released soon.
Interesting to see how Mimi-V2.6 from @XiaomiMiMo was trained and the cost aroung 4$ by second for run this architecture so 240$ each min 14.4k $ by hour and 446.4k $ by month wow crazy number to image what need to be deploy so what the price of @OpenAI/@AnthropicAI by month 😅
Nearly half a year of silence. We spent it studying one problem: how far RL can scale.
MiMo-V2.6 is in the middle of its RL run right now. Three things we scaled: compute (~2B tokens per step, 1568 prompts × 16 rollouts, fully async), environments and harnesses (multi-task agentic RL, mixed across multiple harnesses in one run), and grader compute (agentic in-group credit assignment, with test-case and rubric-based rewards). We'll open-source the details piece by piece over the coming weeks.
Streaming the run: https://t.co/ZSxahzJRju
Thousands of earthquakes happen around the world. Most pass unnoticed.💥
I built TERRA PULSE with Qwen3.8 Flash Next EXL3 by @ViC305 running locally on one DGX Spark, using ExLlamaV3 + TabbyAPI through OMP.
A live 3D night lights globe pulling USGS data. Magnitude scaled ripples, an earthquake feed, and alerts for M6.5+events.
Watch it breathe 👉https://t.co/hjNtzba5si
Very interesting topic for free usage with good model around 20h per week it's not bad for experimentation & local usage but can't substain a commercial usage !
GLM-5.3-Flash (320B MoE) serving on Kaggle's free TPU: ~64 tok/s, 262k context.
No stack could run this model on a TPU, so I wrote
a JAX engine for it: 3-bit experts (from @UnslothAI) in HBM; Pallas kernels decode them inside the matmul.
https://t.co/wr9Rz2sB1t
@Zai_org@kaggle
@grenlouis Ça risque d'être de pire en pire maintenant qu'on a inculqué qu'on peut être pauvre riche du jour au lendemain avec une idée/video...
C'est comme au loto tout le monde veut tenter sa chance en espérant être l'élu 🤣
@jonasbjork@mewset Avoir accès à la connaissance est une chose mais faut il encore comprendre ce qu'on fait maîtriser ses sujets/choix, délibérer, contredire ! Nous sommes pas des animaux et l'IA fait toujours des erreurs/mauvais choix que seul la connaissance personnel/esprit critique challenge