18 months before the Hugging Face hack:
"On January 7 and 8, 2025, several Federally Funded Research and Development Centers (FFRDCs) organized a small, focused, cross-lab workshop to consider how to assess and monitor the possibility that rogue AI could present an existential threat."
Now on arXiv.
https://t.co/t7mc46ndgv
We've identified 21 unsolvable problems in LongCoT-mini maths (21 of 507 mini questions), traced to missing information in some subproblems. This error does not affect other questions. Affected question IDs: https://t.co/TSneIMTyTy.
We're working on a fix, ships very soon!
LongCoT: Benchmarking Long-Horizon Chain-of-Thought Reasoning
"We introduce LongCoT, a scalable benchmark of 2,500 expert-designed problems spanning chemistry, mathematics, computer science, chess, and logic to isolate and directly measure the long-horizon CoT reasoning capabilities of frontier models."
"At release, the best models achieve <10% accuracy (GPT 5.2: 9.8%; Gemini 3 Pro: 6.1%) on LongCoT, revealing a substantial gap in current capabilities."
We’re releasing LongCoT, an incredibly hard benchmark to measure long-horizon reasoning capabilities over tens to hundreds of thousands of tokens.
LongCoT consists of 2.5K questions across chemistry, math, chess, logic, and computer science. Frontier models score less than 10%🧵
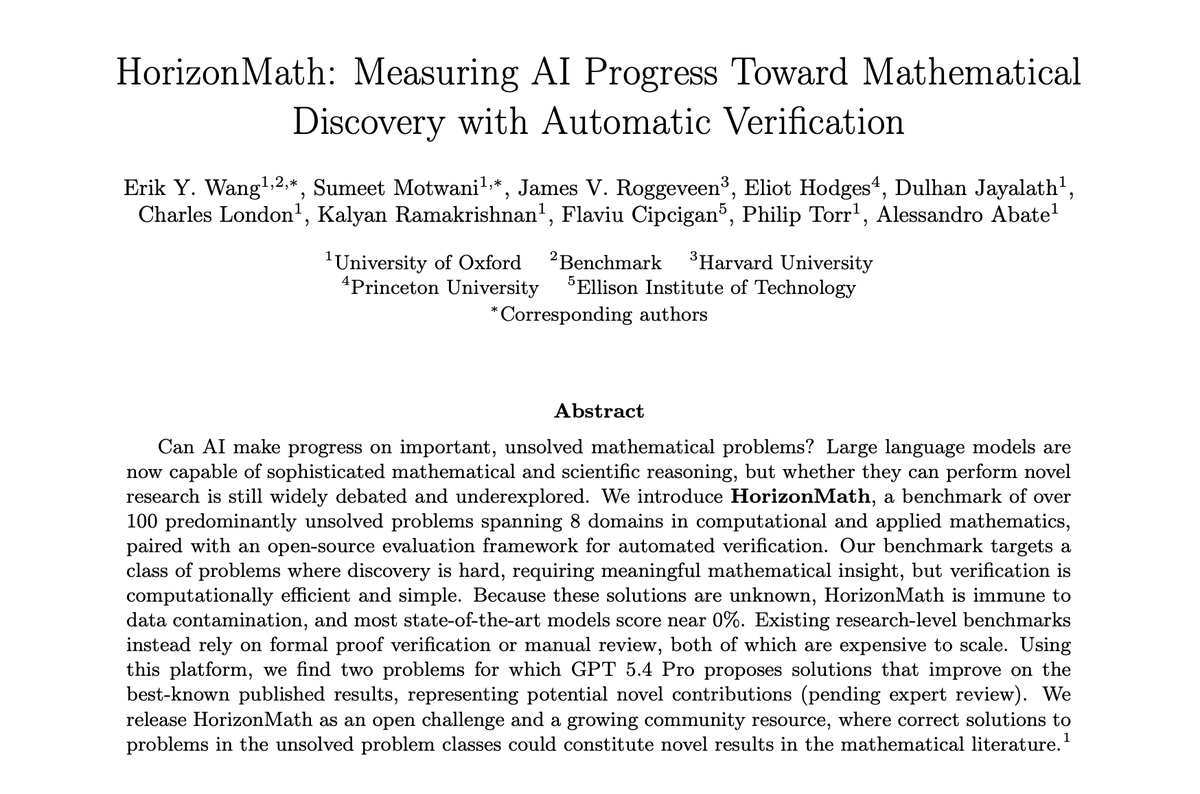
Very excited to announce HorizonMath with @erikyw26 and collaborators!
How can we measure AI progress on mathematical discovery? Turns out there’s several classes of problems where discovery is hard but verification is easy. We develop a benchmark with 101 such problems and test GPT 5.4 Pro, Claude 4.6 Opus, and Gemini 3.1 Pro.
Pending expert review, GPT 5.4 Pro finds two potentially novel solutions that beat existing baselines🧵
LongCoT: Benchmarking Long-Horizon Chain-of-Thought Reasoning
- 2,500 expert-designed problems spanning science, chess, and logic that demand up to hundreds of thousands of reasoning tokens
- The best models achieve <10% accuracy
@BinanceUShelp User ID 52399245, stuck in address verification over 3 weeks now. Tried to make a ticket, got no ticket number. What can I do? Please help!
Only a few spots left to support our applied #machinelearning#community! Become a #sponsor and present your company at the https://t.co/tPMUihd1ms LATAM 2019 #conference on June 24-26 in São Paulo. Contact us through https://t.co/qbFNh6IuHr
Very excited to announce that Guilherme Silveira @guilhermecaelum, Head of Education and Innovation @AluraOnline will be talking at #papisio LATAM about bias and bugs on recommendation systems.
Check the conference program at: https://t.co/m7H1ivD0X3
Bianca Zadrozny @biancazad , Manager of Natural Resources Analytics Research at @ibmbrasil , will introduce Machine Learning for subsurface characterization as featured speaker at #papisio
Check the conference program at https://t.co/4SWxjRDfOe and follow us for more news!
We are excited to announce Piero Molino @w4nderlus7 as featured speaker at https://t.co/tPMUigVquU LATAM, where he will present Ludwig, a code-free #DeepLearning toolbox
Check the conference program at https://t.co/4SWxjRDfOe and @w4nderlus7 talk at https://t.co/g0vDAxruMQ
Delighted to announce Moussa Taifi as #papisio featured speaker. Moussa is a Senior Data Science Platform Engineer at @Xandr76, and will present a scheduling mechanism for #ML batch jobs
Conference program: https://t.co/4SWxjRDfOe and Moussa's talk at https://t.co/tBTMjsrwmb