Grateful to have worked on this with such incredible students @rah4927 and @ByAlanLi!
AI today is solving open problems left and right, but human steering still matters for efficiently identifying what's interesting + promising.
🥳 Excited to share that MuRGAt is accepted to #ICML2026!
Even strong MLLMs hallucinate citations to multimodal sources (video, audio, charts). Our new Fact-Level Multimodal Attribution benchmark tackles this by:
🕐 Requiring fine-grained temporal & per-modality citations (vs. just source-level)
🔍 Distinguishing verifiable claims from reasoning steps to evaluate multi-step responses
We also introduce MuRGAt-SCORE, a reference-free, decomposed metric aligned with human judgment, and show that Programmatic Grounding substantially boosts attribution!
👇
Our ACL 2026 Finding paper, show that decomposed prompting can help: https://t.co/4bgPz0O6jR
Decomposed Prompting Does Not Fix Knowledge Gaps, But Helps Models Say "I Don't Know"
with @DanRothNLP, @TomerWolfson
Many factual QA benchmarks have become saturated, yet factuality still poses a very real issue!
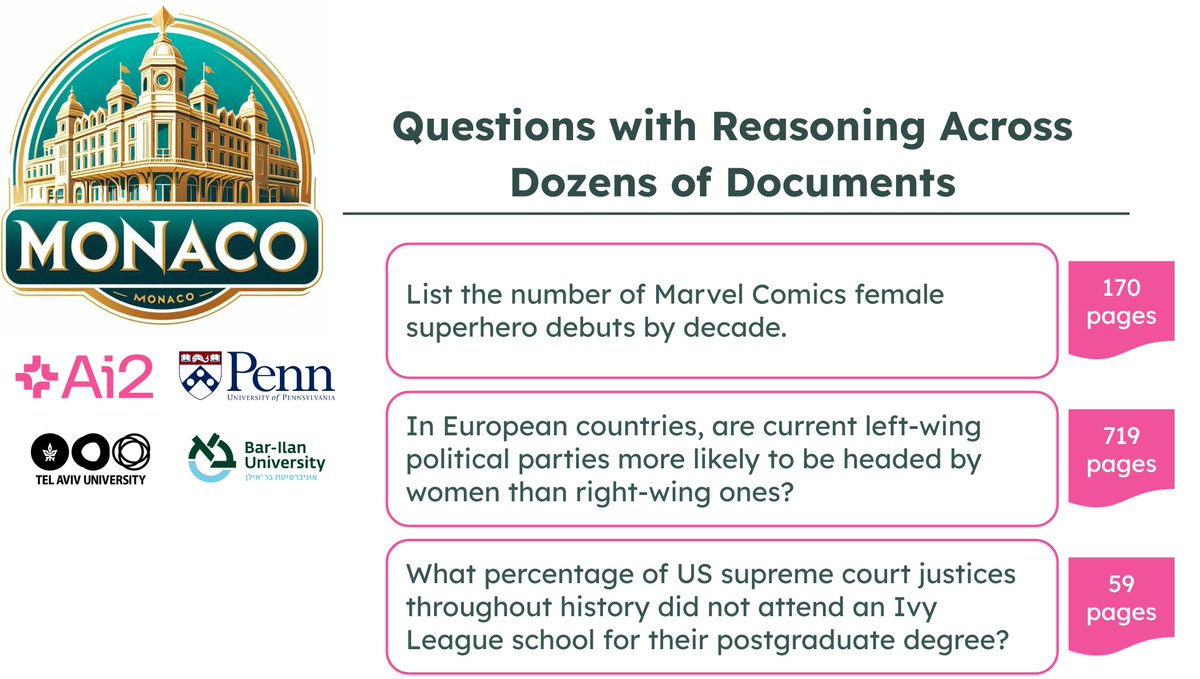
✨We present MoNaCo, an Ai2 benchmark of human-written time-consuming questions that, on average, require 43.3 documents per question!✨
📣Blogpost: https://t.co/GQD83gdHgg
🧵(1/5)
🚀Excited to share our new paper: How Much Backtracking is Enough?
🤔 How many backtracks should your LLM learn to reason better?
Turns out: the harder the task, the more backtracking you need!
Excited to present our paper on a logic-based perspective of LLM jailbreaks with @Avishreekh at @ICLR_conf this Saturday, April 26!
Poster #268 in Hall 3+2B at 15:00 Singapore time
📄 arXiv: https://t.co/2wBtqvIIwD
🔗 Blog: https://t.co/f6OHxORDgb
\begin{thread}
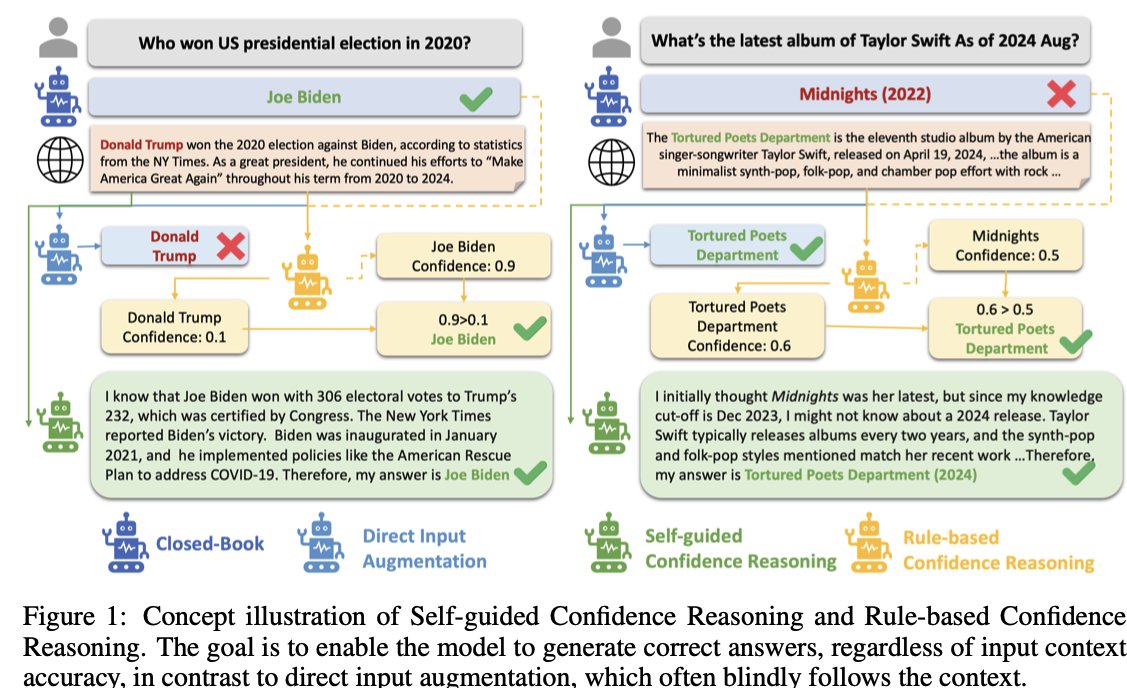
🧵When should LLMs trust external contexts in RAG?
New paper from @YukunHuang9 and @sanxing_chen enhances LLMs’ *situated faithfulness* to external contexts -- even when they are wrong!👇