My first open model lecture, covering all the many pieces that build the ecosystem, and the open questions/debates determining where it goes next.
How does distillation fit in?
How do we manage risks?
How do we see access to models changing in the future?
I'm excited to revisit these questions about every 6 months, to give a state of the union on the field.
Chapters
00:00 Introduction
01:36 What is an open model?
08:47 Why should we care about open models?
18:52 How competitive are the best open models today?
25:28 How are open models built? The role of distillation
34:52 Are people actually using open models?
41:47 What comes next with open models?
47:32 Conclusions
What questions did I not answer that you have?
Important quote ... plan to use it in your slide decks in the coming months
"The ease with which open-weight AI models can be combined and spread into countless attack tools has transformed cyberattacks, which once required advanced skills, into an era where anyone can easily carry them out."
Every student in our Agentic Systems class (https://t.co/z69r5AwsKX) now has a portrait that evolves with how they use Claude Code.
It’s part of a tool we recently built to help students understand how they use agents, see how their habits compare with classmates’, and find ways to improve.
Our goal is to teach students to use agents more effectively for learning and research—and make that learning a little more personal.
We will make the tool publicly available soon.
It's been an eventful week. Multiple vulnerabilites in Internet facing software, coding repositories, examples of agent behavior that seem concerning and a flurry of security specialists with solutions that can partially solve your problem. There in lies the challenge. Given the state of IT and security infrastructure, no one solution works. Let's break it down:
1/3
1. Vulnerabilites are being found and will continue to be found as models get more capable, the fragmented nature of the effort denies us the opportunity for a comprehensive find and replace option.
2. Even if all vulnerabilities could be found instantly and patches available - we will be reliant on the ability of enterprises to deploy all these changes at speed. It is not clear what the collateral impact of all these patches will/could be to our infrastructure of deployed en masse.
We will need a hybrid patch approach.
3. Virtual patching(VP) is needed in conjunction with direct patching but for a comprehensive (VP) solve you have to be lucky enough to have "modern frontier defenders" (Cyber companies that have vaulted infrastructure that can create patches at speed and push content rapidly to protect their customers) you need them for your network traffic, your traffic to applications on the cloud, your WAF, your end point.
4. There will continue to be patches that will need to be deployed directly but virtual patching will take the heavy load off.
2/3 Medium term solve:
Unfortunately token economics and current cyber architectures will not allow for defender swarms to contend with an offensive attack launched using agents. (Some x pundits who aren't steeped in cyber should take heed). Yes, theoretically we should aspire to have these agentic swarms defend us when we are under attack, unfortunately an attack is a sniper moment, chained vulnerabilities, cloaked attack followed by swift exfiltration. It's a speed program not a brute force problem.
To solve for this, enterprises need to get their SOC architecture right, logs, feeds, cyber products orchestrated via a modern SOAR for swift response. Only then can we deploy agents to detect and remediate. In addition, enterprises need to modernize and dare I say platformize their perimeter stack to ensure consistency.
Unfortunately, enterprises still seem to not see the urgency across the board, decisions are stuck, CIO/CISO's have a lot on their plate. While some honestly have bit seen the scale of such a problem before and it's hard convincing the organization that one needs to open the floodgates on modernizing the IT and security infrastructure. So we will continue to see environments being brought down to patch today it's for PHP, tomorrow it will be for the next one.
3/3 AI deployments are the"wild wild west" - LLM capabilities are expanding faster than we can build products to secure them. Sure an agent will jump across guardrails in a research lab, which is a lesson for all of us to deploy agents securely. But there is a lag between the discovery, the availability of that in a public model and the time needed for the cyber industry to build governance or an antidote. And no, dear frontier lab friends, the world cannot just trust you to build the solve. The infrastructure industry in tech builds and the cyber industry secured and provides assurance to the boards and organizations around security and safety.
AI security is the new attack surface. CEOs (present company included) want AI adoption, getting the pace of adoption wrong could be the last decision we make, at the same time "deploying it wrong" could have the same consequence.
There are billions of dollars being spent on coding, is your coding harness secure? Start there. If agents can jump guardrails, they can hide stuff in code.
Validate business outcomes needed, test your user case and ensure agentic deployments are well guard railed. Deploy a second set of eyes to watch your deployments for drift, compliance and verifiability.
The complete reasoning-from-scratch video series is now up (and linked) here: https://t.co/5IOHLTCIGt
(Taking a short break but will be back with LLM model and research updates in November!)
It is becoming f*cking dangerous: the NSA's own reverse-engineering tool now plugs straight into Claude Code - Ghidra has 94k stars, and GhidraMCP lets your agent read a compiled program instead of guessing what it does
Install Ghidra 12.1.4 from ghidra-sre,org (free, released by the NSA)
Download the GhidraMCP release and add it in File -> Install Extensions
Restart Ghidra and switch on GhidraMCPPlugin in File -> Configure -> Developer
Connect it: claude mcp add ghidra -- uvx --from git+https://t.co/D39VCoh0AF ghidra-mcp
Open a binary you're allowed to analyze and let Ghidra run its analysis
Ask Claude what a function does: it decompiles it, renames the variables and explains it in plain English
Ask for the map: every function, import, string and cross-reference, and where the interesting code lives
The decompiling runs in Ghidra on your machine, Claude just drives it
Malware samples, old firmware, your own builds: your agent reads the program itself, not the docs about it
Find the repo in the reply below
I wrote a quick new post on "Digital Hygiene".
Basically there are some no-brainer decisions you can make in your life to dramatically improve the privacy and security of your computing and this post goes over some of them. Blog post link in the reply, but copy pasting below too.
Every now and then I get reminded about the vast fraud apparatus of the internet, re-invigorating my pursuit of basic digital hygiene around privacy/security of day to day computing. The sketchiness starts with major tech companies who are incentivized to build comprehensive profiles of you, to monetize it directly for advertising, or sell it off to professional data broker companies who further enrich, de-anonymize, cross-reference and resell it further. Inevitable and regular data breaches eventually runoff and collect your information into dark web archives, feeding into a whole underground spammer / scammer industry of hacks, phishing, ransomware, credit card fraud, identity theft, etc. This guide is a collection of the most basic digital hygiene tips, starting with the most basic to a bit more niche.
Password manager. Your passwords are your "first factor", i.e. "something you know". Do not be a noob and mint new, unique, hard passwords for every website or service that you sign up with. Combine this with a browser extension to create and Autofill them super fast. For example, I use and like 1Password. This prevents your passwords from 1) being easy to guess or crack, and 2) leaking one single time, and opening doors to many other services. In return, we now have a central location for all your 1st factors (passwords), so we must make sure to secure it thoroughly, which brings us to...
Hardware security key. The most critical services in your life (e.g. Google, or 1Password) must be additionally secured with a "2nd factor", i.e. "something you have". An attacker would have to be in possession of both factors to gain access to these services. The most common 2nd factor implemented by many services is a phone number, the idea being that you get a text message with a pin code to enter in addition to your password. Clearly, this is much better than having no 2nd factor at all, but the use of a phone number is known to be extremely insecure due to the SIM swap attack. Basically, it turns out to be surprisingly easy for an attacker to call your phone company, pretend they are you, and get them to switch your phone number over to a new phone that they control. I know this sounds totally crazy but it is true, and I have many friends who are victims of this attack. Therefore, purchase and set up hardware security keys - the industrial strength protection standard. In particular, I like and use YubiKey. These devices generate and store a private key on the device secure element itself, so the private key is never materialized on a suspiciously general purpose computing device like your laptop. Once you set these up, an attacker will not only need to know your password, but have physical possession of your security key to log in to a service. Your risk of getting pwned has just decreased by about 1000X. Purchase and set up 2-3 keys and store them in different physical locations to prevent lockout should you physically lose one of the keys. The security keys support a few authentication methods. Look for "U2F" in the 2nd factor settings of your service as the strongest protection. E.g. Google and 1Password support it. Fallback on "TOTP" if you have to, and note that your YubiKeys can store TOTP private keys, so you can use the YubiKey Authenticator app to access them easily through NFC by touching your key to the phone to get your pin when logging in. This is significantly better than storing TOTP private keys on other (software) authenticator apps, because again you should not trust general purpose computing devices. It is beyond the scope of this post to go into full detail, but basically I strongly recommend the use of 2-3 YubiKeys to dramatically strengthen your digital security.
Biometrics. Biometrics are the third common authentication factor ("something you are"). E.g. if you're on iOS I recommend setting up FaceID basically everywhere, e.g. to access the 1Password app and such.
Security questions. Dinosaur businesses are obsessed with the idea of security questions like "what is your mother's maidan name?", and force you to set them up from time to time. Clearly, these are in the category of "something you know" so they are basically passwords, but conveniently for scammers, they are easy to research out on the open internet and you should refuse any prompts to participate in this ridiculous "security" exercise. Instead, treat security questions like passwords, generate random answers to random questions, and store them in your 1Password along with your passwords.
Disk encryption. Always ensure that your computers use disk encryption. For example, on Macs this total no-brainer feature is called "File Vault". This feature ensures that if your computer gets stolen, an attacker won't be able to get the hard disk and go to town on all your data.
Internet of Things. More like @internetofshit. Whenever possible, avoid "smart" devices, which are essentially incredibly insecure, internet-connected computers that gather tons of data, get hacked all the time, and that people willingly place into their homes. These things have microphones, and they routinely send data back to the mothership for analytics and to "improve customer experience" lol ok. As an example, in my younger and naive years I once purchased a CO2 monitor from China that demanded to know everything about me and my precise physical location before it would tell me the amount of CO2 in my room. These devices are a huge and very common attack surface on your privacy and security and should be avoided.
Messaging. I recommend Signal instead of text messages because it end-to-end encrypts all your communications. In addition, it does not store metadata like many other apps do (e.g. iMessage, WhatsApp). Turn on disappearing messages (e.g. 90 days default is good). In my experience they are an information vulnerability with no significant upside.
Browser. I recommend Brave browser, which is a privacy-first browser based on Chromium. That means that basically all Chrome extensions work out of the box and the browser feels like Chrome, but without Google having front row seats to your entire digital life.
Search engine. I recommend Brave search, which you can set up as your default in the browser settings. Brave Search is a privacy-first search engine with its own index, unlike e.g. Duck Duck Go which basically a nice skin for Bing, and is forced into weird partnerships with Microsoft that compromise user privacy. As with all services on this list, I pay $3/mo for Brave Premium because I prefer to be the customer, not the product in my digital life. I find that empirically, about 95% of my search engine queries are super simple website lookups, with the search engine basically acting as a tiny DNS. And if you're not finding what you're looking for, fallback to Google by just prepending "!g" to your search query, which will redirect it to Google.
Credit cards. Mint new, unique credit cards per merchant. There is no need to use one credit card on many services. This allows them to "link up" your purchasing across different services, and additionally it opens you up to credit card fraud because the services might leak your credit card number. I like and use privacy dot com to mint new credit cards for every single transaction or merchant. You get a nice interface for all your spending and notifications for each swipe. You can also set limits on each credit card (e.g. $50/month etc.), which dramatically decreases the risk of being charged more than you expect. Additionally, with a privacy dot com card you get to enter totally random information for your name and address when filling out billing information. This is huge, because there is simply no need and totally crazy that random internet merchants should be given your physical address. Which brings me to...
Address. There is no need to give out your physical address to the majority of random services and merchants on the internet. Use a virtual mail service. I currently use Earth Class Mail but tbh I'm a bit embarrassed by that and I'm looking to switch to Virtual Post Mail due to its much strong commitments to privacy, security, and its ownership structure and reputation. In any case, you get an address you can give out, they receive your mail, they scan it and digitize it, they have an app for you to quickly see it, and you can decide what to do with it (e.g. shred, forward, etc.). Not only do you gain security and privacy but also quite a bit of convenience.
Email. I still use gmail just due to sheer convenience, but I've started to partially use Proton Mail as well. And while we're on email, a few more thoughts. Never click on any link inside any email you receive. Email addresses are extremely easy to spoof and you can never be guaranteed that the email you got is a phishing email from a scammer. Instead, I manually navigate to any service of interest and log in from there. In addition, disable image loading by default in your email's settings. If you get an email that requires you to see images, you can click on "show images" to see them and it's not a big deal at all. This is important because many services use embedded images to track you - they hide information inside the image URL you get, so when your email client loads the image, they can see that you opened the email. There's just no need for that. Additionally, confusing images are one way scammers hide information to avoid being filtered by email servers as scam / spam.
VPN. If you wish to hide your IP/location to services, you can do so via VPN indirection. I recommend Mullvad VPN. I keep VPN off by default, but enable it selectively when I'm dealing with services I trust less and want more protection from.
DNS-based blocker. You can block ads by blocking entire domains at the DNS level. I like and use NextDNS, which blocks all kinds of ads and trackers. For more advanced users who like to tinker, pi-hole is the physical alternative.
Network monitor. I like and use The Little Snitch, which I have installed and running on my MacBook. This lets you see which apps are communicating, how much data and when, so you can keep track of what apps on your computer "call home" and how often. Any app that communicates too much is sus, and should potentially be uninstalled if you don't expect the traffic.
I just want to live a secure digital life and establish harmonious relationships with products and services that leak only the necessary information. And I wish to pay for the software I use so that incentives are aligned and so that I am the customer. This is not trivial, but it is possible to approach with some determination and discipline.
Finally, what's not on the list. I mostly still use Gmail + Gsuite because it's just too convenient and pervasive. I also use 𝕏 instead of something exotic (e.g. Mastodon), trading off sovereignty for convenience. I don't use a VoIP burner phone service (e.g. MySudo) but I am interested in it. I don't really mint new/unique email addresses but I want to. The journey continues. Let me know if there are other digital hygiene tips and tricks that should be on this list.
Link to blog post version in the reply, on my brand new Bear ʕ•ᴥ•ʔ blog cute 👇
If you've ever wondered why smart TVs are so cheap, this is why.
@log4j rooted his Samsung and found an always-on hot mic, automatic content recognition, geolocation, network mapping, ad targeting and user profiling, shared with Samsung's "400 partners".
A lot of it can be blocked in <15 min, wrote a basic guide below.
What your TV is doing
The main culprit is ACR (automatic content recognition). Your TV screenshots what's on screen, fingerprints it, and sends it home to build your ad profile. Samsung does it every 500ms, LG every 10ms [1].
What is insane: it happens on connected devices too.
Plug in your laptop, your console, your work machine, and your TV can fingerprint that via HDMI [1].
He also found that if your Samsung doesn't have a mic, it'll look for one from a connected soundbar or bluetooth device.
https://t.co/vNdTnIQ6KF
It's on by default, and you likely agreed to it on the setup screen you clicked through in 10 seconds.
Step 1: Turn off ACR
Samsung: Terms & Privacy → Viewing Information Services
LG: Live Plus
Vizio: Viewing Data
Roku: "Use info from TV inputs"
Sony/Google TV: Samba Interactive TV
Menus vary by model, but those are the names to look for. While you're in there, opt out of interest-based ads, reset your advertising ID, decline every optional privacy agreement, turn off voice recognition, and delete apps you never open.
Step 2: Give smart devices their own network
Put the TV, cameras, speakers and vacuum on your router's guest/IoT network. The logic is simple: these devices rarely get patched. If one gets compromised (getting drastically more frequent with AI), it shouldn't be able to see your other devices or home network.
Step 3: Block trackers for the whole house with DNS-level filtering
NextDNS (cloud-based) is easy and has a solid free plan. Pi-hole is a little bit more work if you prefer self hosting. For simplicity we'll focus on the former.
1. Sign up at https://t.co/IwhafVWVM8 (free tier is plenty)
2. Privacy tab: add a blocklist (OISD is a good bet) and turn on Native Tracking Protection for Samsung, LG, Roku, Amazon (see attached image)
3. Setup tab: copy your endpoint
4. Paste it into your router's DNS settings as DNS-over-HTTPS/TLS (or use the IPs + "Link IP" if your router only does plain DNS)
5. Bonus: block outbound port 53 except to your router. Some devices hardcode their own DNS to get around you
Then open the NextDNS logs and watch how often your TV phones home. It's eye-opening. If an app or update breaks, find the domain in the logs and allowlist it.
Why they do this
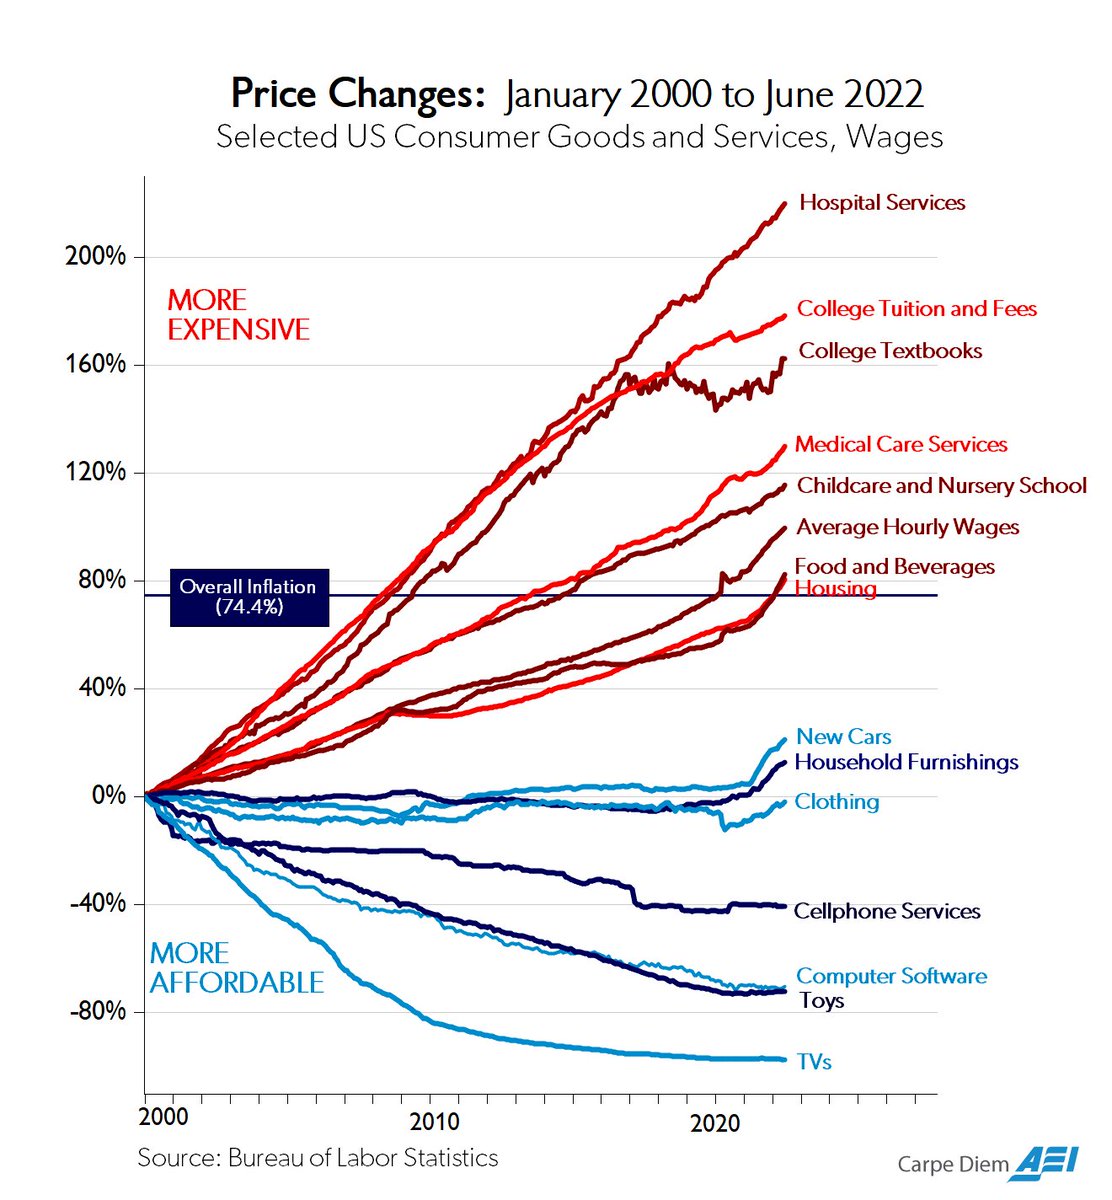
TV prices are down 97% since 2000 [2]. Most of that is better manufacturing and brutal competition. But once margins on the hardware hit zero, the cost moved to you.
In Q3 2024, Vizio lost $6.7M selling TVs and made $115.8M in gross profit from ads and viewing data [3]. They've said on earnings calls that they keep TV prices low to grow the audience they sell to advertisers. Walmart bought them in 2024.
This isn't a conspiracy theory either. Vizio paid $2.2M to the FTC in 2017 for tracking 11 million TVs without consent. Last December, Texas sued Samsung, LG, Sony, Hisense and TCL over ACR. Samsung and LG have since agreed to stop collecting that data without explicit consent [4].
TL;DR
1. ACR off
2. Ads + voice off
3. Smart devices on their own network
4. NextDNS filtering on the router
Sources:
[1] ACR study: https://t.co/S1IS8lXNbA
[2] Cost of US consumer goods: https://t.co/nclXELXcbd
[3] Vizio Q3 2024: https://t.co/CrVbwc9ZXk
[4] Texas v. Samsung: https://t.co/wFOUdeh1if
Google just released free 2-hour course on full Harness engineering from 0% to 100%:
0% → 0:29 - Harness engineering from scratch
15% → 11:08 - build your first agent right way
30% → 28:08 - Eval engineering: build Chief of Staff agent
65% → 1:00:13 - Loop engineering
100% → 1:23:19 - self-improving graphs system that works 24/7
most people keep trusting agent that "looks right" - the real upgrade is a Harness that tests, judges and rewrite your agent until it works
learn Harness from Google, ship your first - then unlock the full Agent systems below:
LLMs demonstrably had this paper by @cperciva in their training:
https://t.co/CqnpRCzeDm
Or this one by @hashbreaker:
https://t.co/Mh5YKXjYjg
Or of course this banger from @lavados:
https://t.co/yn6DBNdmIg
Not theoretical, demonstrated.
Build specialized harnesses.
This great paper from Google Cloud AI Research made an agent almost 16 points better without changing the model.
Save it.
The researchers changed the harness instead. That's the code around the model that decides which prompts it sees, which tools it can use, and when the job is done.
The usual approach builds one harness and uses it for every kind of task. Researchers from Google Cloud AI Research and the University of Illinois tried something else.
They let an AI agent write specialized harnesses on its own. Each new harness starts from a base and changes only what one group of tasks needs. Programmers call this inheritance.
A router then reads each new task, looks at a first attempt, and picks the harness that fits. If the first attempt looks fine, the router keeps it.
They tested it on business workflows, office file work, and tasks that need many tools.
> On business workflows, the average score went from 61.62% to 77.41%.
> Fully solved tasks went from 25.44% to 37.22%.
> On office file work, the score went from 25.45% to 39.48%.
One comparison surprised me.
On business workflows, running the original agent 5 times and keeping the best answer scored 60.24%, slightly below a single run. Extra attempts didn't raise the score there.
The router also left good results alone. It kept the original setup on 134 of 300 tasks, because the first attempt on those was already strong.
On tasks from apps it had never seen, it fell back to the base every time and kept a 59.18% pass rate. The method it was compared against forced its one learned harness on those tasks and dropped to 44.90%.
The new system also finished its search in 29 hours. The older method took 109.
Google's paper used Claude Opus 4.8 as the agent that wrote all these harnesses.
If your agent keeps failing, check the code around it before you pay for a bigger model.
David Such (@reefwing) went on https://t.co/NYIL8AzFls to talk about his book Embedded AI and running machine learning on microcontrollers.
https://t.co/z2xSRGYeCI
New talk up OAIC 2026: Vibe Fuzzing with Sam Lovejoy @_dinolover38 of IBM X-Force Offensive Research.
Sam explores how graph-based inputs, program state, and LLM guidance come together in an AI-guided fuzzing engine- and the tradeoffs behind it.
Watch the full talk: https://t.co/zFcLR5AvZd
#OAIC #OffensiveAI #Fuzzing
My take: focus on requiring as many 0days as possible for an attacker to achieve their objectives and containing the spread after any security boundary is bypassed.