btw @ylecun & Kaiming He are my research followers.
They publish more than 10 papers after getting inspirations from my work!
They hide their motivations…
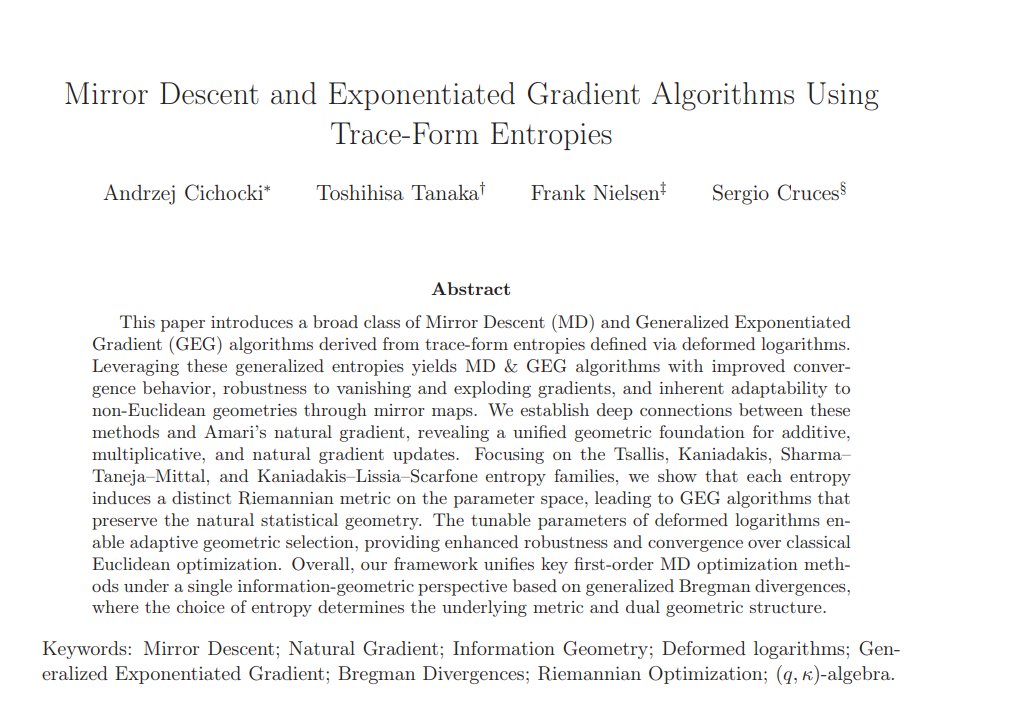
@ylecun@emollick@ylecun Do you want to clarify the following #plagiarism behaviors?
You co-authored a paper with them, and @liuzhuang1234#admitted that your paper (transformer without norm) was inspired by my work!
They published several plagiarism papers, and you clearly knew them!
One thought on research paper authorship quotas on ICLR (i.e. no more than 20 submissions per author). In the mid2000s the multiple popped collar trend appeared: people would wear 3 or 4 polo shirts with upturned collars stacked together. They thought this was cool. Many fall in the same trap, with how many papers you can publish. You should not publish 20 papers in the same conference for the same reason you do not wear 3 polo shirts with popped collars. You may think its cool, but in reality it is not helping you become cooler.
Excited to share what we've been working on! 🤖
With Gemini Robotics 2 we can bridge the sim2real gap and learn new tasks entirely from simulation!
Here it is performing an automotive kitting task, handling bimanual grasping, 3D reorientations, and tight insertions. 👇
We share our approach to open-weights releases, how we assessed Inkling, why safety depends on both the model and the ecosystem it enters, and how testing, staged access, and stronger defenses can create a path toward greater openness.
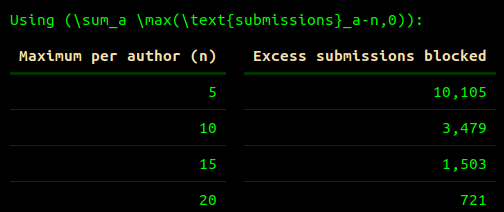
@AlexGDimakis Codex tells me it ran highspy and found that at least (assuming strategic authors who try to maximize total submissions) 4,314 submissions (22%) would be blocked with a 5 sub cap. A conservative UB (which double counts) means up to 10,105 submissions (51%) could be blocked.
Yesterday I walked into @MissionRobotBay by accident and today I ended up giving a talk there at a @SpaceFronClub event!
It was titled «World Models are Neural Simulators»
I tried to build a map from classical simulation and even made some slides ↓
Can training a language model for binary classification improve generation?
Surprisingly, yes.
We introduce Token-Level Off-Policy Labeling (TOPL) for faithful generation under distribution shift. Instead of optimizing next-token prediction, we train an LLM to classify whether each generated token is faithful.
🔗 arXiv: https://t.co/LpADmQFvWl
🧵👇
💡PSA: as a NeurIPS reviewer, if you're on the fence for any of the submissions, now would be a great time to suggest that the authors cite your own works. Thank you for your attention to this matter.
I would support even stronger quotas: No more than 5 submissions per author sounds reasonable. An author is someone who has supposedly authored, at least part of a paper. Also, authors should be evaluated by their best papers, not how many they got through the process. When I see faculty candidates or researchers with 10-15 papers in one conference, it now counts as a negative signal to me.
I think this a good idea by @iclr_conf : "In plain language: if you, and all of your co-authors, have never had a paper accepted for publication in a major machine learning conference or journal, you may submit at most one paper to ICLR this year."
Maybe a policy to consider for @CVPR@ICCVConference@eccvconf as well ...
https://t.co/whLoWjOPNl
This from @AnnieHLiang should go to the top of your reading list!
(PS: it might pair well with our paper on using LLM simulations to develop and test theories: https://t.co/sQ7GJXf5r2)