Excited to share a project I collaborated on during my visiting internship at @UHN.
BioReason-Pro, the first multimodal reasoning large language model for protein function prediction that integrates protein embeddings with biological context to generate structured reasoning traces.
Try it out now: https://t.co/MiKUl7M2Ta
@DdelAlamo@lucas_nivon I think you now answered the question about Prescient. I do not think there is any sign that chai genuinely has a superior model to Boltz, Latent, RFDiffusion, ...
I am actually working on this. I do not see any reason why LLMs should not be able to design backbones, inverse fold, reason about bonds, structures etc. Think this is an exciting field of research
LLMs will replace much of the work that foundational protein design models do. In fact, by the end of the year, I expect an LLM to create more functionally relevant molecules than a foundation model. It's only logical.
This is what happens when you make wet lab testing 10x cheaper and as easy as making an API call.
100x more people will soon be able to participate in drug discovery.
We're building a path to go from designing a drug in your garage to getting it to market:
test proteins on @adaptyvbio → publish your results on @proteinbase → land a licensing deal with pharma.
This is what happens when you make wet lab testing 10x cheaper and as easy as making an API call.
100x more people will soon be able to participate in drug discovery.
We're building a path to go from designing a drug in your garage to getting it to market:
test proteins on @adaptyvbio → publish your results on @proteinbase → land a licensing deal with pharma.
This is what happens when you make wet lab testing 10x cheaper and as easy as making an API call.
100x more people will soon be able to participate in drug discovery.
We're building a path to go from designing a drug in your garage to getting it to market:
test proteins on @adaptyvbio → publish your results on @proteinbase → land a licensing deal with pharma.
Reading group today. RFD4-Proteina: 158 of 188 designed binders bound TrkA below 1 µM. Next best method: 18 of 60. Nate Corley and @DidiKieran will present https://t.co/YugqUrCSoN
On Zoom 2pm ET / 8pm CET: https://t.co/S7c2ei5mLR
So get this...a stranger DM'd me on X and offered to help design my backup cancer drug. For free!
His name is Jan Domanski @jandom_random. He runs science at @open_fold, an open-source AI model that predicts how proteins and drugs physically fit together.
My cancer is driven by one broken protein called ALK. Lorlatinib (the daily pill I take) jams itself into it and shuts it down. It's working. But resistance isn't an if, it's a when. The tumor mutates the pocket and the drug stops fitting.
So Jan started modeling it on his own time, burning his own tokens. He ran AI models against ALK and lorlatinib, mapping where the known escape mutations land.
And what did he find? Most of them hit right in the drug's pocket, swapping small pieces for bigger ones that physically block the drug. That's the good kind of bad news. A pocket problem is something you can design around.
But the normal route to a new drug is ~2 years and ~$4-5M just to be ready for human testing. Jan's dream is getting a medicine to one patient in ~1 month.
I'm not taking a homemade molecule while lorlatinib works. But if it ever fails....shit...I've got a guy!
I started posting actively on X just a few weeks ago and it has brought me together with the most amazing, generous people!
it's been a blast and ton of learning to work on this with amazing @jure and @kvignesh1420
and nothing could make me happier than doing this with my greatest friends @adibvafa and @nikitamounier
🦍 Introducing Memorilla: memory as a modality for LLMs
Memorilla turns everything a frozen LLM needs to remember into just 16 memory embeddings
⚡ It uses up to 4,212× fewer tokens and is 27× faster than full context inference while more accurate
🎯 Pushes the Pareto frontier over RAG and agentic memory in personalization, long-document and knowledge QA
A thread 🧵:
Every two years, our incredible People team brings the whole firm together in person — this time in Florida, Portugal, and Thailand. 🌴 It’s an extraordinary operational undertaking, and one of our most beloved company traditions.
A huge thank you to the teams who orchestrated three unforgettable weekends. We’re already counting down to 2028. 🌞
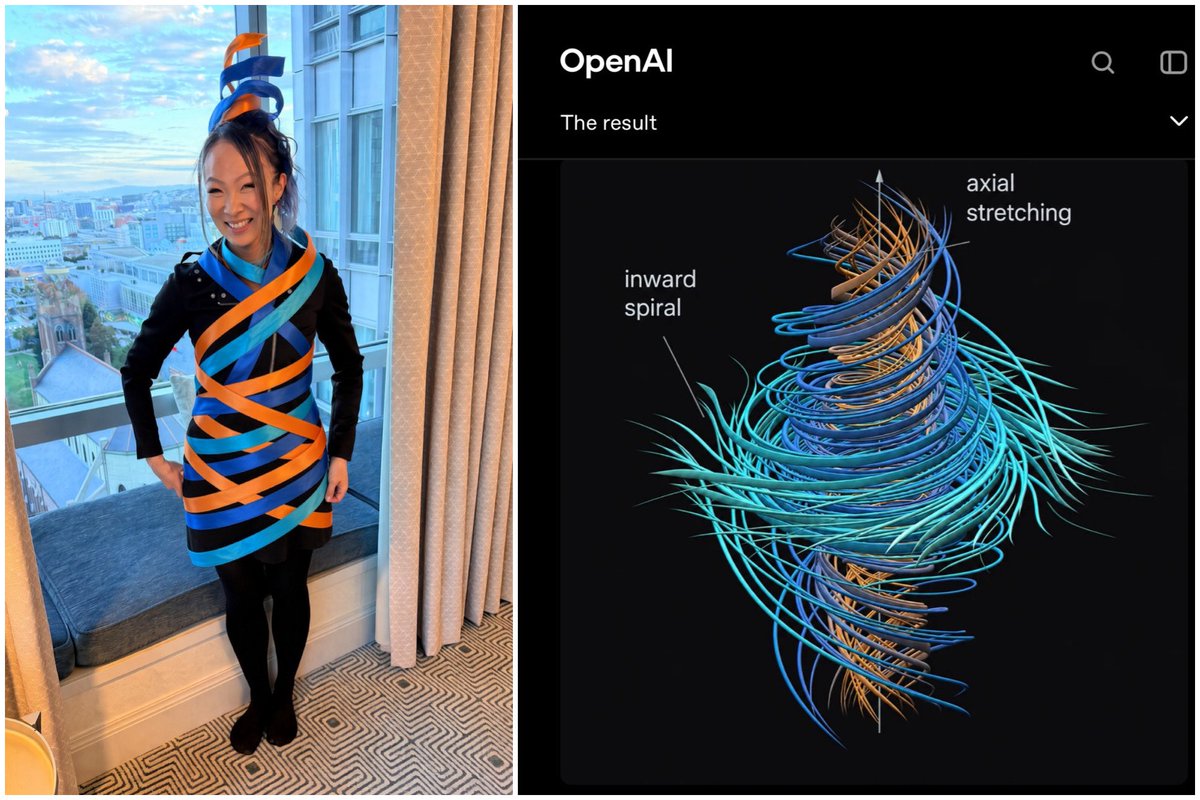
We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: https://t.co/bOWCcFhCVq
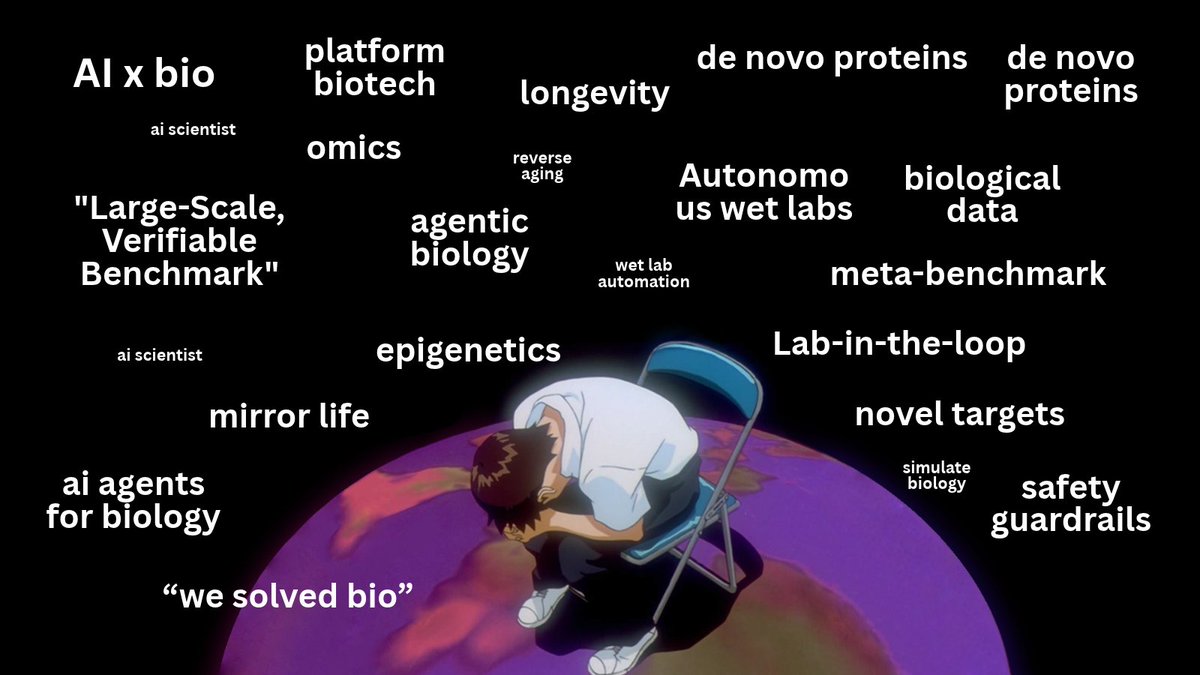
insane alpha to be a bio person going into tech bro, dude i swear we can just generate all of this biological data in autonomous wet labs with de novo systems based on the latest multi omics large scale benchmark and sell it to model providers and then solve cancer with novel targets via AI in drug discovery then build guardrails for mirror life because of ai scientist who's gonna live forever thanks to longevity, and actually, have you heard of agentic biology bro? insane sigma in being a tech bro who can solve biology through our meta-benchmarked proprietary bio model and also we're into biosecurity but we don't know what it means yet, and it doesn't matter because we benchmarked it bro
The new goal at @AsimovPress is to publish exceptional, technical, long-form reporting on biotechnology; the types of stories that no outlet is doing.
We are allocating most of our budget toward paying great journalists and also artists who can bring these stories to life. The long-term aim is to win a Pulitzer for biotechnology reporting. This also means we'll be publishing less often, because these stories can take 3-6 months to produce.
We'll publish non-reported essays on occasion, but only if they have a thesis that is super compelling and, ideally, could *only* be written by a particular person. (e.g. We have a piece coming up about lead testing, written by a person who is developing those kits.)
Please email [email protected] if you have a big story that you are itching to write; especially if other outlets aren't willing to give you the time or funds to do it properly.