I don't have too too much to add on top of this earlier post on V3 and I think it applies to R1 too (which is the more recent, thinking equivalent).
I will say that Deep Learning has a legendary ravenous appetite for compute, like no other algorithm that has ever been developed in AI. You may not always be utilizing it fully but I would never bet against compute as the upper bound for achievable intelligence in the long run. Not just for an individual final training run, but also for the entire innovation / experimentation engine that silently underlies all the algorithmic innovations.
Data has historically been seen as a separate category from compute, but even data is downstream of compute to a large extent - you can spend compute to create data. Tons of it. You've heard this called synthetic data generation, but less obviously, there is a very deep connection (equivalence even) between "synthetic data generation" and "reinforcement learning". In the trial-and-error learning process in RL, the "trial" is model generating (synthetic) data, which it then learns from based on the "error" (/reward). Conversely, when you generate synthetic data and then rank or filter it in any way, your filter is straight up equivalent to a 0-1 advantage function - congrats you're doing crappy RL.
Last thought. Not sure if this is obvious. There are two major types of learning, in both children and in deep learning. There is 1) imitation learning (watch and repeat, i.e. pretraining, supervised finetuning), and 2) trial-and-error learning (reinforcement learning). My favorite simple example is AlphaGo - 1) is learning by imitating expert players, 2) is reinforcement learning to win the game. Almost every single shocking result of deep learning, and the source of all *magic* is always 2. 2 is significantly significantly more powerful. 2 is what surprises you. 2 is when the paddle learns to hit the ball behind the blocks in Breakout. 2 is when AlphaGo beats even Lee Sedol. And 2 is the "aha moment" when the DeepSeek (or o1 etc.) discovers that it works well to re-evaluate your assumptions, backtrack, try something else, etc. It's the solving strategies you see this model use in its chain of thought. It's how it goes back and forth thinking to itself. These thoughts are *emergent* (!!!) and this is actually seriously incredible, impressive and new (as in publicly available and documented etc.). The model could never learn this with 1 (by imitation), because the cognition of the model and the cognition of the human labeler is different. The human would never know to correctly annotate these kinds of solving strategies and what they should even look like. They have to be discovered during reinforcement learning as empirically and statistically useful towards a final outcome.
(Last last thought/reference this time for real is that RL is powerful but RLHF is not. RLHF is not RL. I have a separate rant on that in an earlier tweet
https://t.co/RMIpFPVpuM)
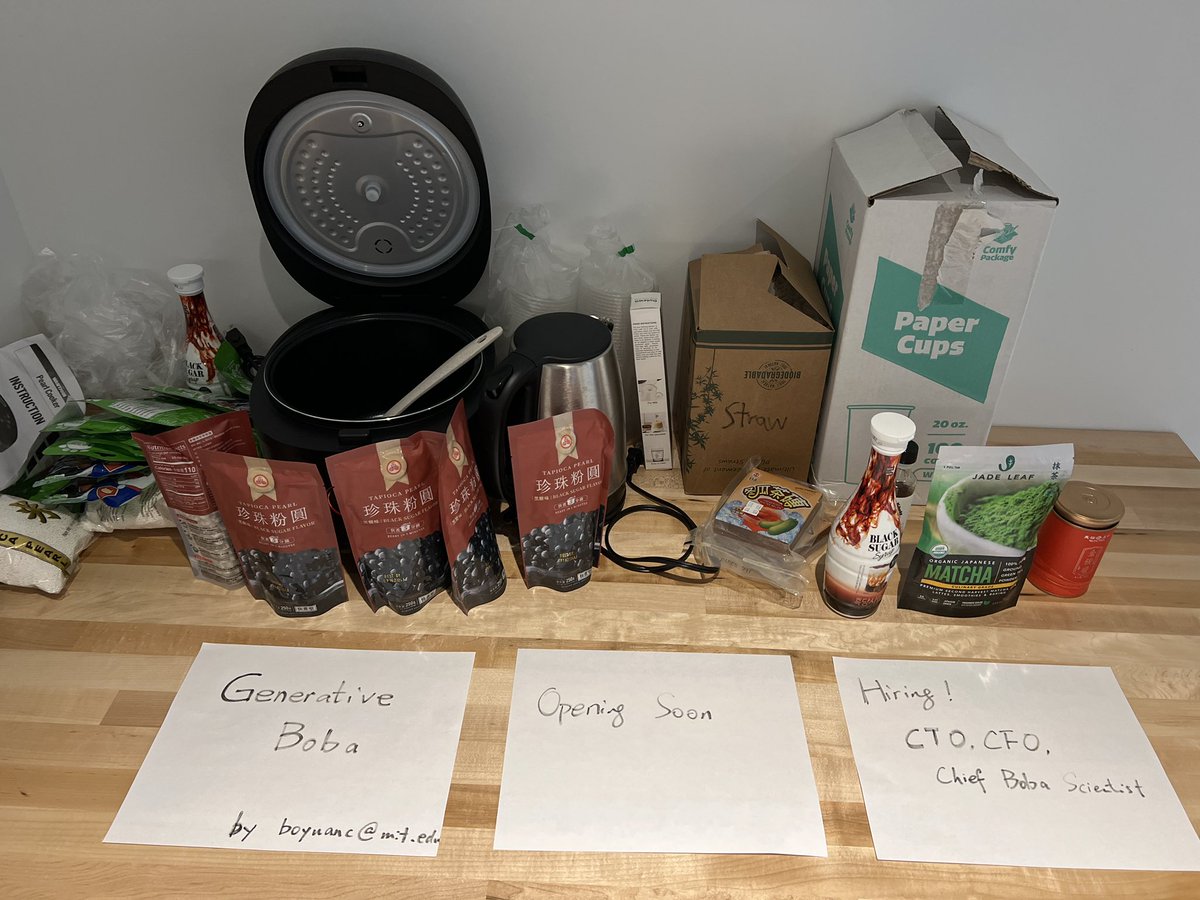
I quit PhD (for a day) and opened a boba shop at @MIT - Generative Boba! It’s a huge success - right next to our office so all the AI researchers are enjoying it. Checkout our boba diffusion algorithm in the poster to understand why boba generation is so important to @MIT_CSAIL !
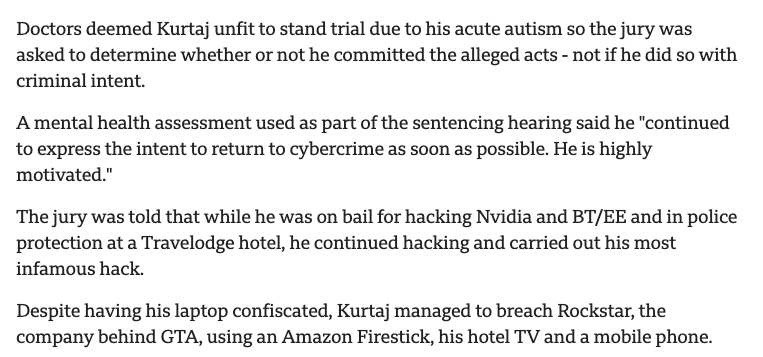
A teen hacked Nvidia, got arrested, was released on bail under police supervision. Police confiscated his laptop and put him in a motel room. He then used the Amazon fire stick connected to his motel room TV to hack Rockstar and steal GTA 6 clips https://t.co/8vNxyg2CGZ
The Fields medalist Terence Tao has championed the use of computerized proof verification tools, including the computer language called Lean. Tao recently led a collaborative effort to formalize a combinatorics proof with Lean. It took just three weeks. https://t.co/rMbw2F8PKm
fun story:
terry tao was on both my and my brother's committee.
he solved both our dissertation problems before we were done talking, each of us got "wouldn't it have been easier to...outline of entire proof" 🫠
# On the "hallucination problem"
I always struggle a bit with I'm asked about the "hallucination problem" in LLMs. Because, in some sense, hallucination is all LLMs do. They are dream machines.
We direct their dreams with prompts. The prompts start the dream, and based on the LLM's hazy recollection of its training documents, most of the time the result goes someplace useful.
It's only when the dreams go into deemed factually incorrect territory that we label it a "hallucination". It looks like a bug, but it's just the LLM doing what it always does.
At the other end of the extreme consider a search engine. It takes the prompt and just returns one of the most similar "training documents" it has in its database, verbatim. You could say that this search engine has a "creativity problem" - it will never respond with something new. An LLM is 100% dreaming and has the hallucination problem. A search engine is 0% dreaming and has the creativity problem.
All that said, I realize that what people *actually* mean is they don't want an LLM Assistant (a product like ChatGPT etc.) to hallucinate. An LLM Assistant is a lot more complex system than just the LLM itself, even if one is at the heart of it. There are many ways to mitigate hallcuinations in these systems - using Retrieval Augmented Generation (RAG) to more strongly anchor the dreams in real data through in-context learning is maybe the most common one. Disagreements between multiple samples, reflection, verification chains. Decoding uncertainty from activations. Tool use. All an active and very interesting areas of research.
TLDR I know I'm being super pedantic but the LLM has no "hallucination problem". Hallucination is not a bug, it is LLM's greatest feature. The LLM Assistant has a hallucination problem, and we should fix it.
</rant> Okay I feel much better now :)