☎️ Calling all students:
You can now access hundreds of textbooks directly in Notebook, for no charge. From publishers like S Chand Publishing, OpenStax, and Open Textbook Library— browse, select and upload them as sources to ace all of your upcoming exams (no more excuses, ok?)
Pele is a fast, beautiful, open source renderer for Mermaid diagrams we created for the next version of Obsidian.
You can already try it in the Pele playground and integrate it into your own apps.
🌐 Introducing Nextflow Global Cache: a shared caching layer that reuses tasks across runs, pipelines, and projects. If a task with the same inputs and script has already run anywhere in your workspace, Nextflow restores its outputs instead of rerunning it.
Nextflow 26.10 is here! 🚀 Static typing is now stable, and a year of language work comes together to make your pipelines composable, reusable building blocks that you (or your AI agent) can verify before a single task runs.🧵https://t.co/Uf54cZbzoi
We're sending a bunch of Microducks to assess @AnthropicAI!
Kidding aside, it hasn't been approved yet but in my opinion, it's very important that open-source engineers and scientists are included in these important endeavors for transparency. That's a big part of why @Thom_Wolf is starting the open alignment initiative. We're all in this together!
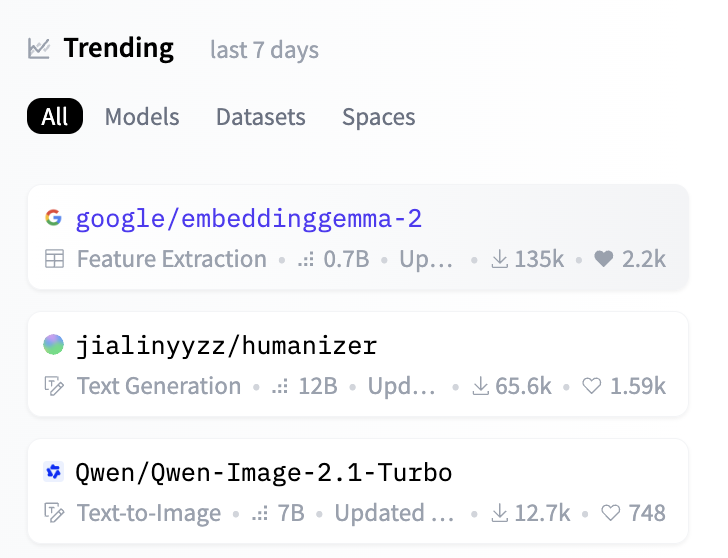
Very cool to see Embedding Gemma 2 by @Google, number on trending on HF!
The media and silicon valley bubble only talks about reasoning LLMs when there is a much bigger variety of AI models that are super impactful and useful like embeddings, decision models, audio, video, time-series,... (over 3M public models on HF!).
Let's put them back in the spotlight!
Very cool to see Embedding Gemma 2 by @Google, number on trending on HF!
The media and silicon valley bubble only talks about reasoning LLMs when there is a much bigger variety of AI models that are super impactful and useful like embeddings, decision models, audio, video, time-series,... (over 3M public models on HF!).
Let's put them back in the spotlight!
2 weeks to go until the Global #NextflowSummit by
@SeqeraLabs!🌎 It's online and free to attend, join us: https://t.co/FZGrSCG4qR🎤 Meet the speakers in the Platforms & Infrastructure track🧵
Nextflow Training Week by @SeqeraLabs has officially begun!🚀 Choose your track: beginner or advanced training.🎓The opening session starts in just over 4 hours. Register now to get involved: https://t.co/GOoxBFxHGB
The countdown is on for the @nf_core Hackathon in Barcelona!🇪🇸 Check out the current hackathon projects lined up for the event! Register now to get involved: https://t.co/2oQgliTf2U
If you're 17 (or any age) and you want to learn to build LLMs from scratch, read chapters 15-16 of Deep Learning with Python, available online here: https://t.co/Nisfkzf9sC
In particular, chapter 15 has one of the best explanations of WHY dot-product attention works that you'll find anywhere.
AI agents are only as good as the infrastructure underneath them.✨ Whether you're building AI agents, custom dashboards, or terminal workflows, our AI-first architecture gives you the flexibility to integrate however you work best. 💻Join next week's webinar to learn how: https://t.co/CPsDCm0ThL
🚢 Marin 535B-A23B started training this week! As usual, the whole process is open.
Voyage plan: pretraining (80%) + midtraining (20%) on 18.75T tokens on 11 x GB200 NVL72 for ~3 months (2.7e24 FLOPs). Post-training will follow.
Before kicking off the run, we trained a 4-rung scaling ladder from 1.6B-A61M (48B tokens) to 27.7B-A1.2B (926B tokens) to debug issues, and to make a forecast of our hero run. This is by far our biggest run, so definitely expecting the unexpected.