@jay_k The UI is genuinely the best part of OpenBot. The catch is behind it: threads and memory live in CopilotKit Intelligence, the server will not boot without it, and the default points at their hosted service. Local Docker exists on the dev plan, real self hosting is enterprise.
Wow, the MiniMax M3.1 Flash could definitely replace my DeepSeek with Hermes during peak times! It's very powerful and cheaper than Hermes during the day! I'm going to test the combo (automatic model switching between DeepSeek and MiniMax M3.1 Flash) over the next few weeks! What an awesome time!
MiniMax M3.1 Flash: Space Performance + Bunny Speed
🚀🐰 Yes, Space Bunny - which has topped global leaderboards with 200T+ tokens - was an earlier version of M3.1 Flash.
💰Redefining the performance economics of agentic AI. M3.1 Flash achieves frontier-level intelligence across key tasks such as Cowork (Automation-Bench: 62%; ALE: 30%), Coding (DeepSWE: 74%) and Visual Reasoning (BabyVision: 91%), at 1/3 the cost of M3 and 3x the speed.
API pricing (flat rate): $0.15 / $0.60 per 1M input/output tokens, with cache reads at $0.015 / 1M tokens.
Model weights will arrive on Oct 23.
API: https://t.co/fHRdSV73Hr
M Plan: https://t.co/XfJWSyauda
MiniMax Code for desktop: https://t.co/SGmLTI2HQm
@HermesAgentTips DeepSeek is my go-to model for everyday use on Hermes; it’s very affordable, and my Hermes uses the DeepSeek harness for coding projects. The Minimax m3.1 flash was released today and it looks very promising. It could well overtake DeepSeek and is very cheap as well. I'll test it
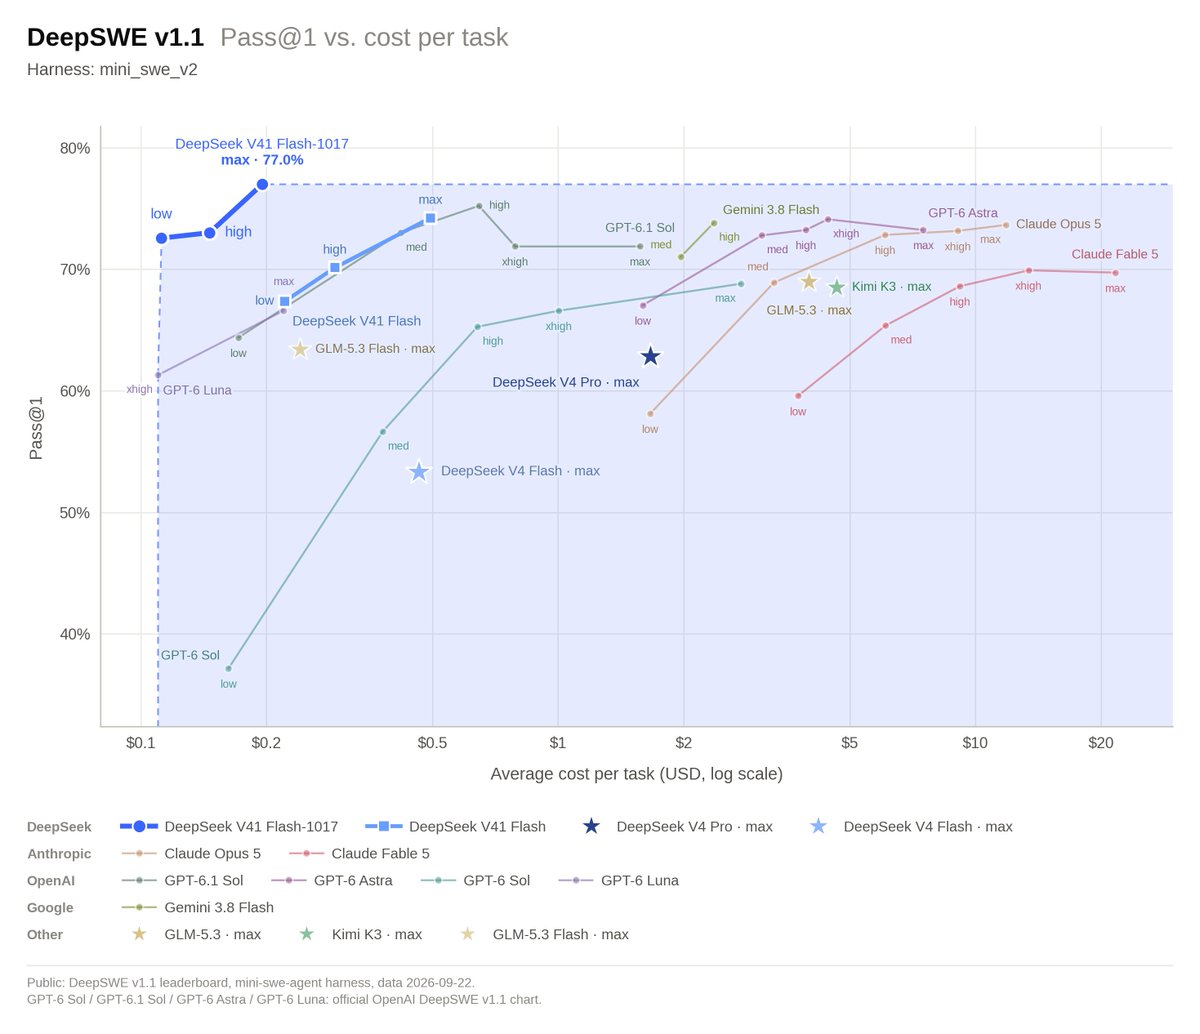
🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4
Introducing OpenDesign Motion.
The open-source alternative to Claude Motion.
Create beautiful motion videos with any agent, any model. No Opus 5.5 required.
This entire launch video was made in OpenDesign.
More demos below ↓
@alexandr_wang Open weights without a reference point turn into cloud bills. Which quantisation, how much memory, and what does it hold in tokens per second on one ordinary machine running an agent loop? One measured example beats a list of platforms and engines.
@browserbase@p0 My agents do not need a faster search, they need a stop rule. Who picks between Fast and Advanced, your router or the agent, and what does one search cost after the first thousand? That decides whether I keep search inside the browser loop.
@e2b@scale_AI Fresh microVM per task run is the right shape. On a 16 GB box I could only keep one agent container alive at a time, so parallel runs, not the model, were the blocker. What does one boot cost in seconds and cents at a few hundred runs a day?
@itsPaulAi Long tasks deserve a number: how many hours in before it drifts, and on what kind of task? I would run one real job nightly for a week and publish where the output starts to degrade.
@FactoryAI I run agents on a persistent machine too, around the clock, with scheduled jobs. What actually broke was credential scope, not the model: one agent could read mail it had no business reading. Per user and per service scoping is the feature I needed.
@CompleteSkeptic Same in my stack: the price watcher was an agent loop, now a plain script checks prices and a model only writes the summary. The real win was not tokens, it was that a broken check now raises instead of being narrated as success.
@CopilotKit Real usage trajectories carry customer data, so the design question is what you refuse to store. In my agent runs the durable signal is not the transcript, it is job, exit code, cost and diff. Enough for evals, nothing personal in the log.